
IberBench
收藏资源简介:
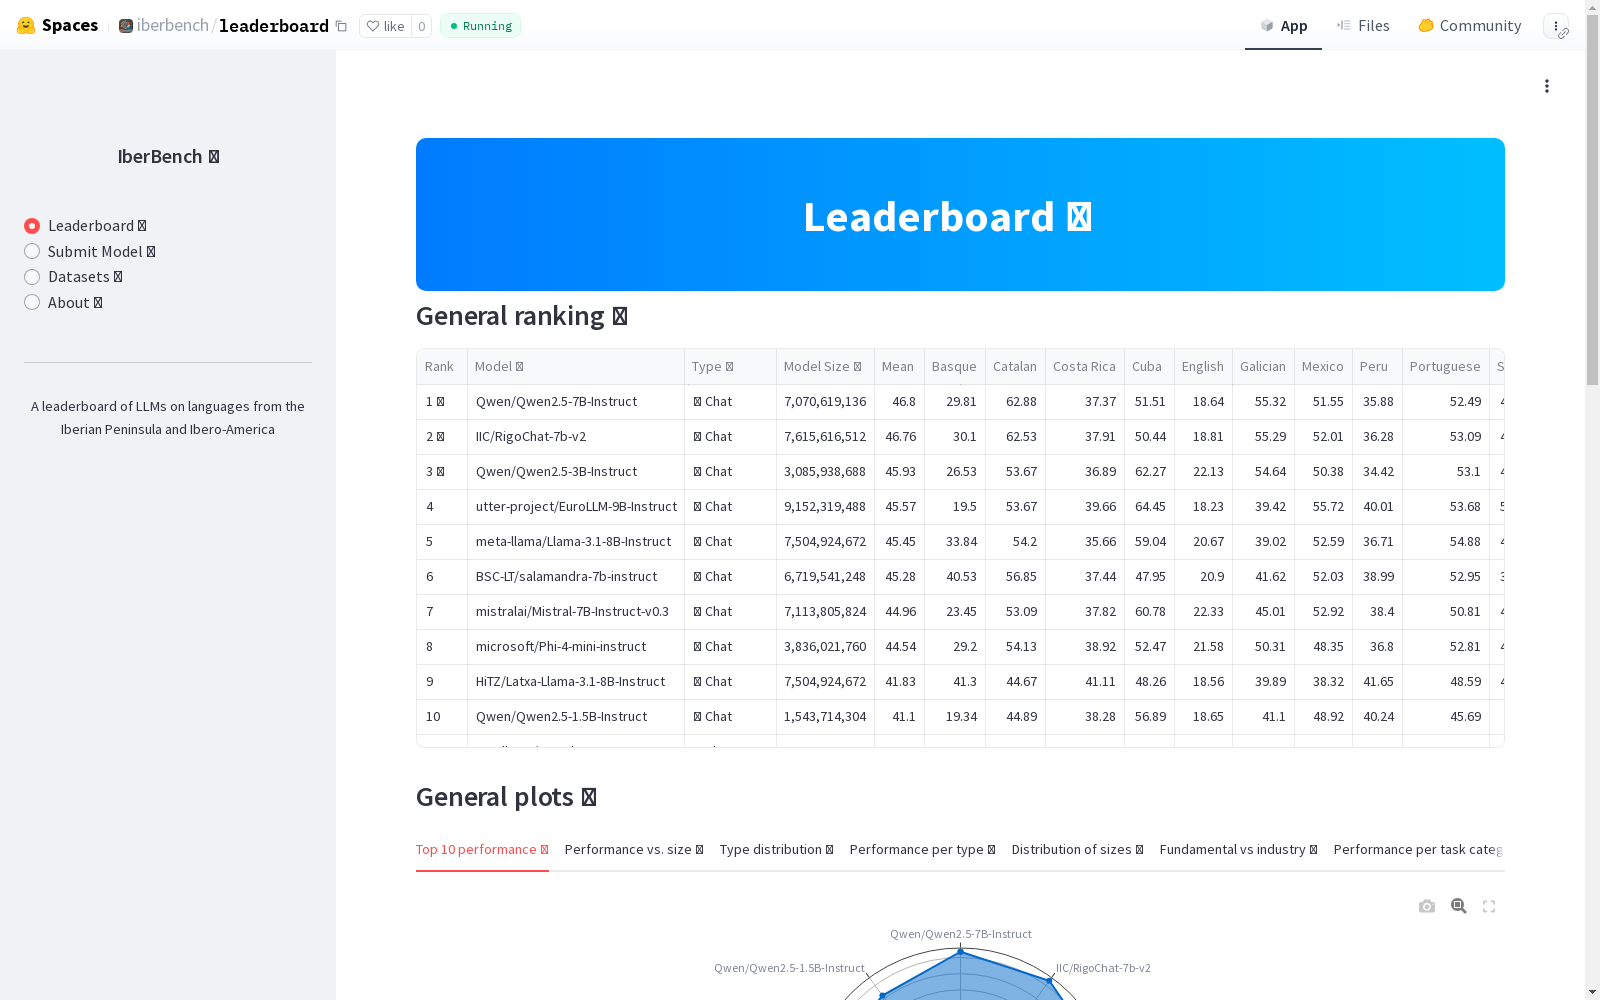
IberBench是一个全面且可扩展的基准测试,旨在评估大型语言模型在伊比利亚半岛和伊比美洲语言的基本和行业相关自然语言处理任务上的性能。该数据集由101个数据集组成,涵盖22个任务类别,如情感和情绪分析、毒性检测和摘要等。IberBench解决了现有评估实践中的关键局限性,如缺乏语言多样性和静态评估设置,通过允许持续更新和社区驱动的模型和数据集提交,由专家委员会进行审核。
IberBench is a comprehensive and scalable benchmark designed to evaluate the performance of Large Language Models (LLMs) on both fundamental and industry-relevant natural language processing tasks for languages of the Iberian Peninsula and Ibero-American regions. This benchmark comprises 101 datasets spanning 22 task categories, including sentiment and emotion analysis, toxicity detection, summarization, and more. IberBench addresses critical limitations of existing evaluation practices, such as insufficient linguistic diversity and static evaluation setups, by allowing continuous updates and community-driven submissions of models and datasets, which are reviewed by an expert committee.
- 1IberBench: LLM Evaluation on Iberian LanguagesSymanto Research, Keepler Data Tech, Universitat Politècnica de València, United Nations International Computing Centre (UNICC) · 2025年


