animal-welfare-conversations
收藏资源简介:
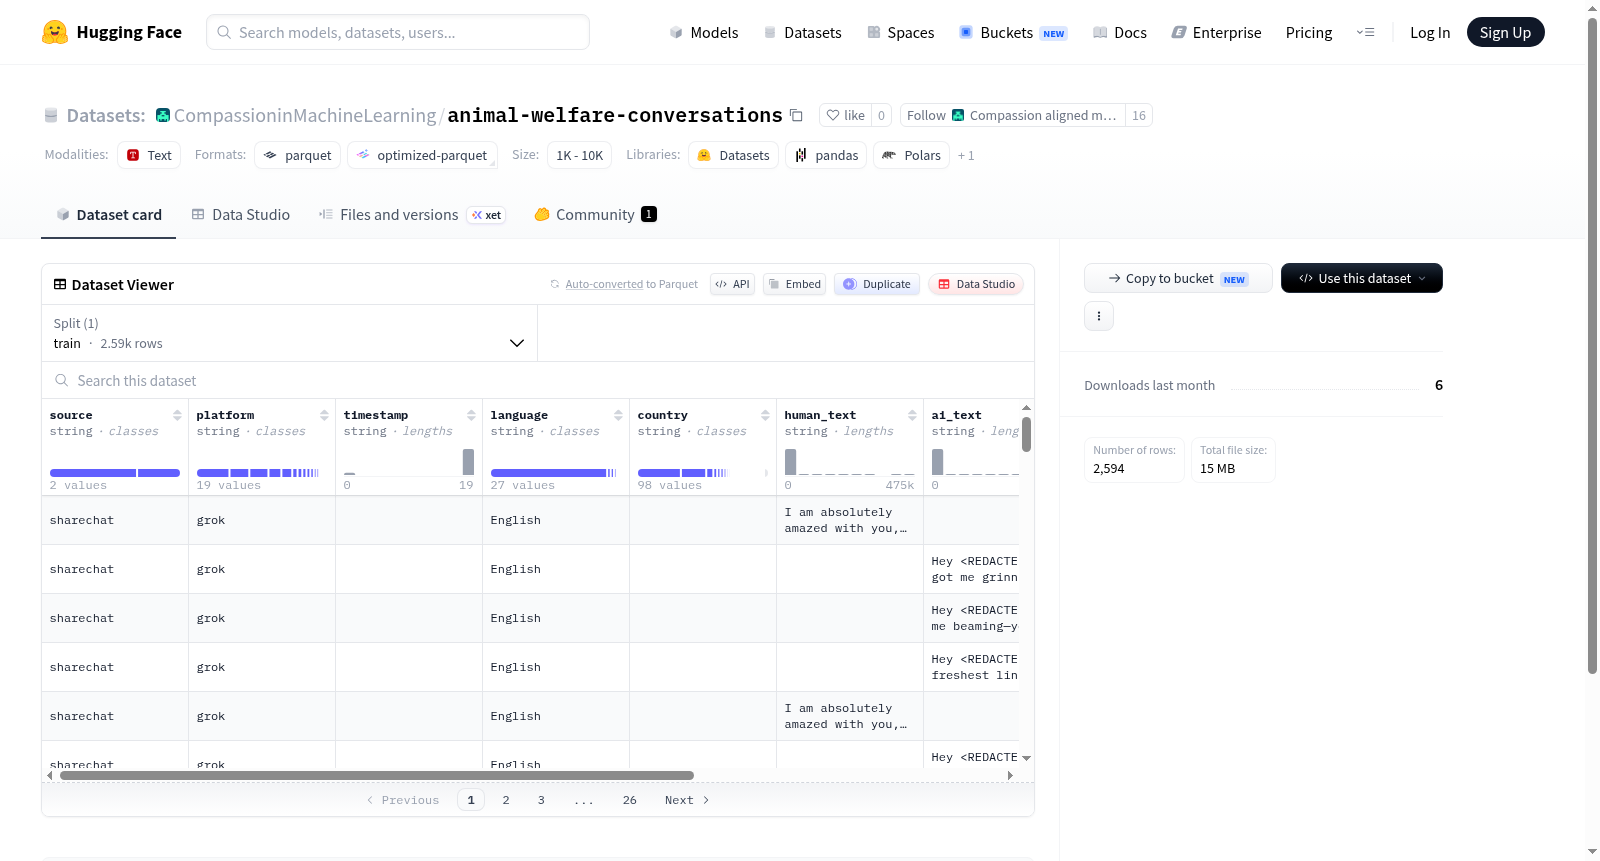
该数据集是一个包含人类生成文本与人工智能生成文本配对对比的数据集。数据集的核心特征包括human_text(人类文本)和ai_text(AI文本)两个主要文本字段,每个样本都提供了这两种文本的对应实例。此外,数据集还包含丰富的元数据信息:source表示数据来源,platform表示采集平台,timestamp记录时间戳,language标识文本语言,country表示国家/地区信息,category对文本内容进行分类,confidence可能表示某些判断或标注的置信度。数据集规模为2594个训练样本,总大小约32.85MB。该数据集适用于文本生成质量评估、AI文本检测、人机对话对比分析、内容分类研究等自然语言处理任务。
This dataset is a paired comparative dataset containing human-generated text and AI-generated text. Its core features include two primary text fields: human_text and ai_text, with each sample providing corresponding instances of these two text types. Additionally, the dataset includes rich metadata: source denotes the data source, platform represents the collection platform, timestamp records the acquisition timestamp, language identifies the text's language, country specifies the country/region information, category classifies the text content, and confidence may represent the confidence level of certain judgments or annotations. The dataset consists of 2594 training samples with a total size of approximately 32.85 MB. This dataset is applicable to natural language processing tasks including text generation quality evaluation, AI text detection, comparative analysis of human-machine dialogues, and content classification research.
- 数据集名称:animal-welfare-conversations
- 核心主题:动物福利对话数据
- 数据规模:训练集包含2594个样本,总数据量约32.85 MB(下载大小约15.04 MB)
- 数据特征:每条样本包含以下字段:
source(字符串):来源platform(字符串):平台timestamp(字符串):时间戳language(字符串):语言country(字符串):国家human_text(字符串):人类文本ai_text(字符串):AI文本category(字符串):类别confidence(字符串):置信度
- 数据划分:仅提供训练集(
train) - 配置文件:默认配置(
default),数据文件路径为data/train-*