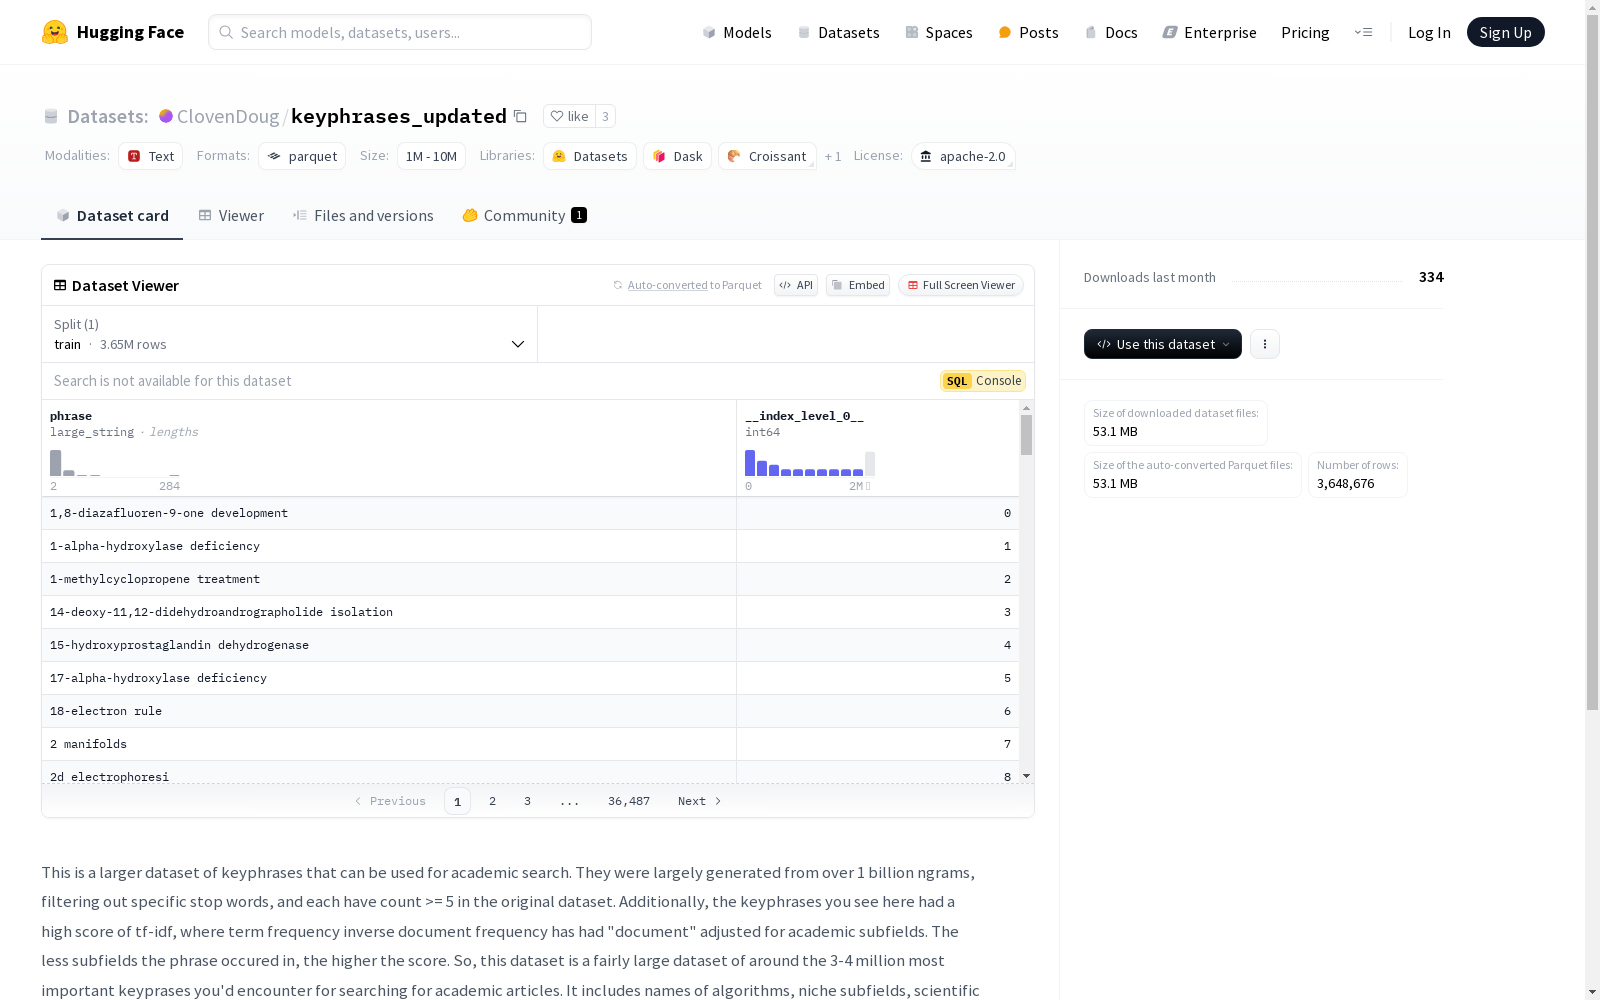
keyphrases_updated
收藏资源简介:
该数据集是一个较大的关键词短语集合,主要用于学术搜索。这些关键词短语主要从超过10亿个ngrams中生成,经过特定停用词的过滤,并且在原始数据集中每个短语的计数至少为5。此外,这些关键词短语具有较高的tf-idf分数,其中术语频率逆文档频率的“文档”已针对学术子领域进行了调整。短语出现的子领域越少,分数越高。因此,该数据集包含了大约3-4百万个最重要的关键词短语,适用于搜索学术文章。数据集包括算法名称、特定子领域、科学概念、疾病等。数据集分为不同长度的短语:单字短语(Unigrams)有142,690个唯一短语,双字短语(Bigrams)有378,041个唯一短语,三字短语(Trigrams)有2,444,002个唯一短语,四字短语(Fourgrams)有711,771个唯一短语。
This dataset is a large collection of keyword phrases primarily utilized for academic search. These keyword phrases are generated from over 1 billion ngrams, filtered with specific stop words, and each phrase has a count of at least 5 in the original dataset. Furthermore, these keyword phrases feature relatively high TF-IDF scores, where the 'document' unit for term frequency-inverse document frequency (TF-IDF) has been adjusted for academic subfields. The fewer academic subfields a phrase appears in, the higher its score. Thus, this dataset contains approximately 3 to 4 million of the most critical keyword phrases suitable for academic article search. The dataset encompasses algorithm names, specific academic subfields, scientific concepts, diseases, and other relevant categories. The dataset is categorized by phrase length: there are 142,690 unique unigrams, 378,041 unique bigrams, 2,444,002 unique trigrams, and 711,771 unique fourgrams.
数据集概述
数据集名称
- keyphrases_updated
数据集描述
- 该数据集包含大量关键短语,适用于学术搜索。
- 数据集中的关键短语主要从超过10亿个ngrams中生成,经过特定停用词过滤,且在原始数据集中出现次数不少于5次。
- 关键短语的tf-idf得分较高,其中“文档”已根据学术子领域进行调整。
- 短语在越少的子领域中出现,得分越高。
- 数据集包含约3-4百万个最重要的关键短语,涵盖算法名称、细分领域、科学概念、疾病等。
数据集规模
- Unigrams: 103,314个唯一短语
- Bigrams: 378,041个唯一短语
- Trigrams: 2,444,002个唯一短语
- Fourgrams: 711,771个唯一短语
许可证
- Apache 2.0