eval-fsr-a1-github-dockerfiles-swe-r358-rf0711-traces
收藏资源简介:
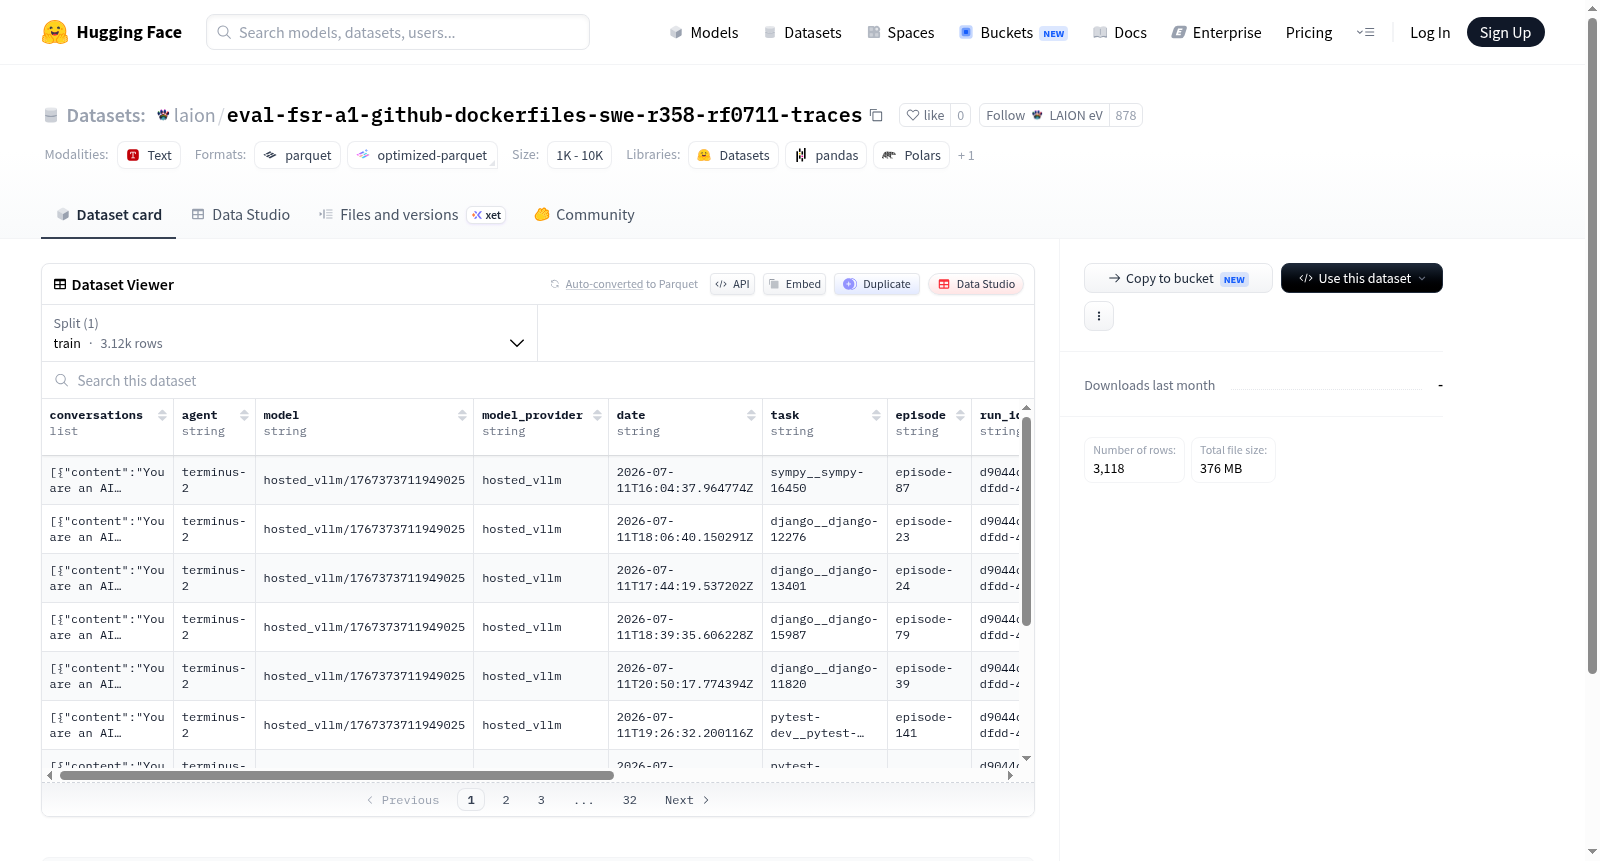
该数据集是一个记录基于代理的对话交互实验的数据集,核心内容是多轮对话记录,每个样本包含完整的对话历史(conversations字段,其中每条消息包括内容content和角色role)。此外,数据集提供了丰富的元数据:包括使用的代理类型(agent)、对话生成所使用的模型及其提供商(model, model_provider)、对话日期(date)、所属任务类型(task)、实验序列标识(episode, run_id, trial_name)、对话结果(result)、验证器输出(verifier_output)以及数据溯源信息(trace_source)。数据规模方面,训练集包含3,118个对话样本。该数据集适用于对话系统评估、多轮对话建模、代理行为分析、人机交互研究以及基于实验轨迹的机器学习任务。
This dataset is a curated collection of agent-based conversational interaction experiment data, with its core content consisting of multi-turn conversation records. Each sample contains a complete conversation history (the `conversations` field, where each individual message includes `content` and `role`). Additionally, the dataset provides comprehensive metadata: including the utilized agent type (`agent`), the conversation generation model and its corresponding provider (`model`, `model_provider`), conversation date (`date`), affiliated task type (`task`), experiment sequence identifiers (`episode`, `run_id`, `trial_name`), conversation results (`result`), verifier output (`verifier_output`), and data provenance information (`trace_source`). In terms of data scale, the training set contains 3,118 conversation samples. This dataset is applicable to conversational system evaluation, multi-turn conversation modeling, agent behavior analysis, human-computer interaction research, and machine learning tasks based on experimental trajectories.
- 数据集名称:eval-fsr-a1-github-dockerfiles-swe-r358-rf0711-traces
- 数据集来源:LAION
- 数据集大小:
- 下载大小:376,485,822 字节(约359 MB)
- 数据集总大小:463,791,553 字节(约442 MB)
- 数据拆分:
- 训练集(train):3,118 个样本,共 463,791,553 字节
- 特征字段:
- conversations:对话内容列表,每条包含 content(字符串)和 role(字符串)
- agent:代理(字符串)
- model:模型(字符串)
- model_provider:模型提供方(字符串)
- date:日期(字符串)
- task:任务(字符串)
- episode:集数(字符串)
- run_id:运行ID(字符串)
- trial_name:试验名称(字符串)
- result:结果(字符串)
- verifier_output:验证器输出(字符串)
- trace_source:跟踪来源(字符串)
- 数据文件:默认配置文件,训练集数据文件路径为 data/train-*