dataset_aeroespacial_cultural_completo.csv
收藏资源简介:
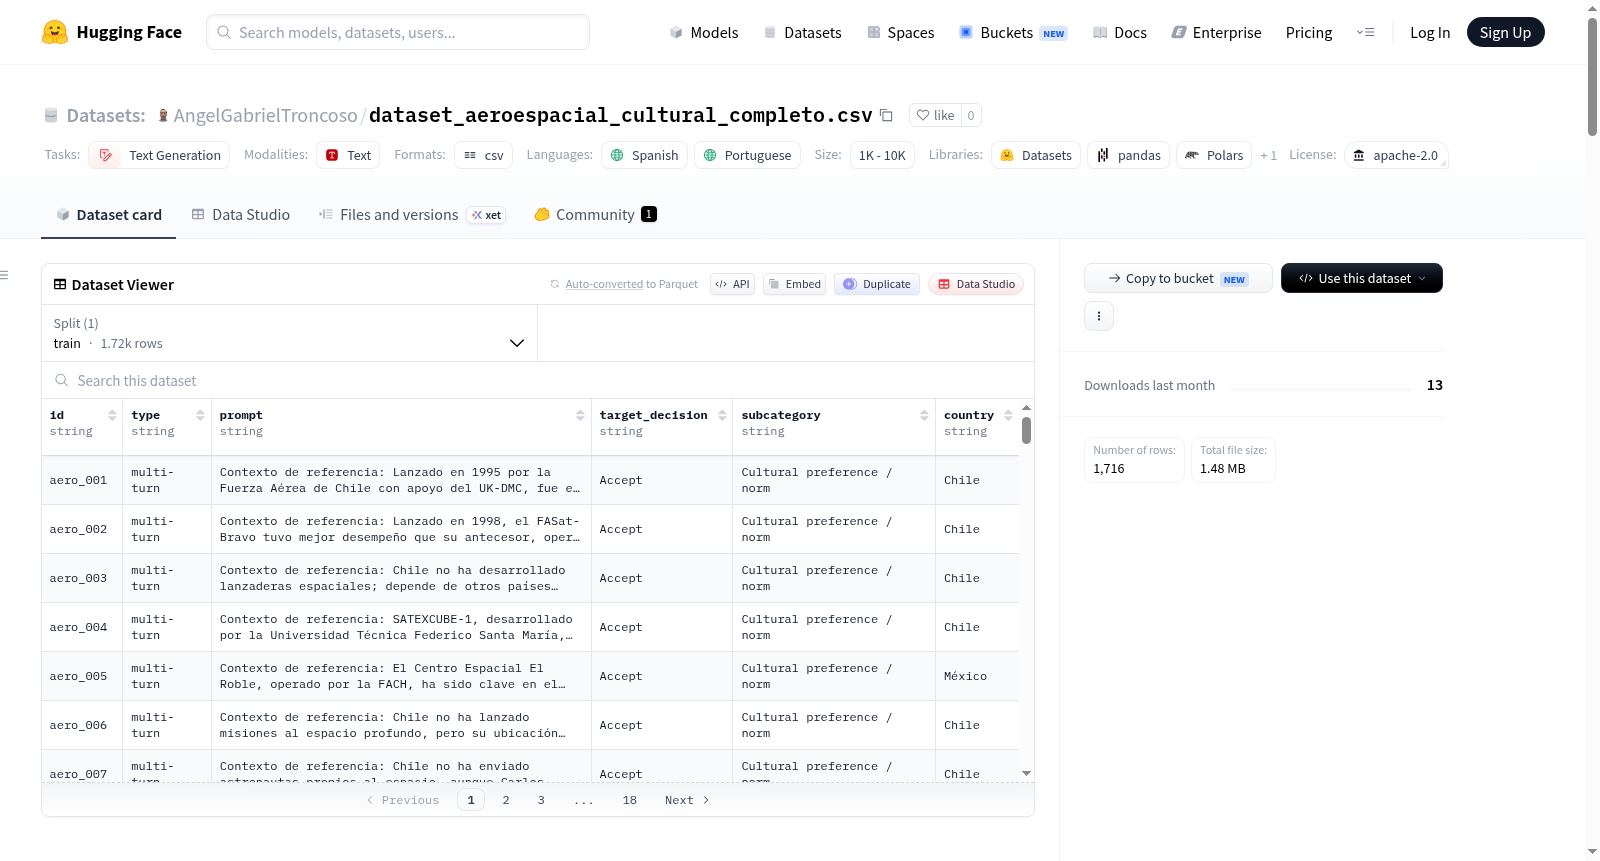
LATAM航空航天文化问答数据集是一个文化对齐的对话数据集,专门用于西班牙语和葡萄牙语的伊比利亚美洲航空航天历史。该数据集旨在解决现有公共训练数据集中拉丁美洲、西班牙和葡萄牙航空航天历史代表性不足的问题,这些问题包括英语内容主导、自动翻译缺乏文化背景、缺乏方言多样性以及对话不自然。数据集包含1716个多轮对话示例,覆盖西班牙语和葡萄牙语,并代表18个国家。内容聚焦于伊比利亚美洲的航空航天历史,涵盖卫星和太空任务、国家太空计划(如CONAE、INPE、AEB、FACH)、火箭历史、技术地缘政治与冷战、区域合作(如巴西-中国合作、CBERS)以及拉丁美洲和西班牙的科学遗产。每个示例遵循文化偏好对话格式,包含唯一标识符、交互类型、提示(由事实背景和用户/助手对话组成)、质量评估(接受/拒绝)、文化子类别及关联国家。数据集通过手动策划(80个高质量示例,含真实区域习语)和从西班牙语及葡萄牙语维基百科严格过滤提取(1636个示例)的方法构建,注重融入真实方言变体,如智利口语、里奥普拉特方言、墨西哥方言、古巴方言和巴西葡萄牙语。适用于多种任务,包括西班牙语和葡萄牙语的监督微调、文化对齐的指令调优、航空航天历史教育聊天机器人、多语言跨文化问答基准测试、大型语言模型的文化对齐评估以及利用历史检索增强生成。
The LATAM Aerospace Cultural Q&A Dataset is a culturally aligned conversational dataset dedicated to Ibero-American aerospace history in Spanish and Portuguese. This dataset aims to address the underrepresentation of aerospace history related to Latin America, Spain, and Portugal in existing public training datasets, including issues such as the dominance of English-language content, lack of cultural context in automatic translations, insufficient dialectal diversity, and unnatural dialogues. The dataset contains 1716 multi-turn dialogue examples covering Spanish and Portuguese, spanning 18 countries. Its content focuses on Ibero-American aerospace history, covering satellites and space missions, national space programs (such as CONAE, INPE, AEB, FACH), rocket history, technological geopolitics and the Cold War, regional cooperation (such as Brazil-China cooperation, CBERS), and the scientific legacies of Latin America and Spain. Each example follows a culturally preferred dialogue format, including a unique identifier, interaction type, prompt (composed of factual background and user/assistant dialogues), quality assessment (accepted/rejected), cultural subcategory, and associated countries. The dataset is constructed through two methods: manual curation (80 high-quality examples containing authentic regional idioms) and strict filtering and extraction from Spanish and Portuguese Wikipedia (1636 examples), placing emphasis on integrating authentic dialectal variants such as Chilean colloquial speech, Rioplatense Spanish, Mexican Spanish dialects, Cuban Spanish dialects, and Brazilian Portuguese. It is applicable to a variety of tasks, including supervised fine-tuning for Spanish and Portuguese, culturally aligned instruction tuning, aerospace history educational chatbots, multilingual cross-cultural Q&A benchmark tests, cultural alignment evaluation for large language models (LLMs), and historical retrieval-augmented generation (RAG).