autophagycode_D_train_Qwen3-14B_lr0.0001_c142_trust_g5
收藏资源简介:
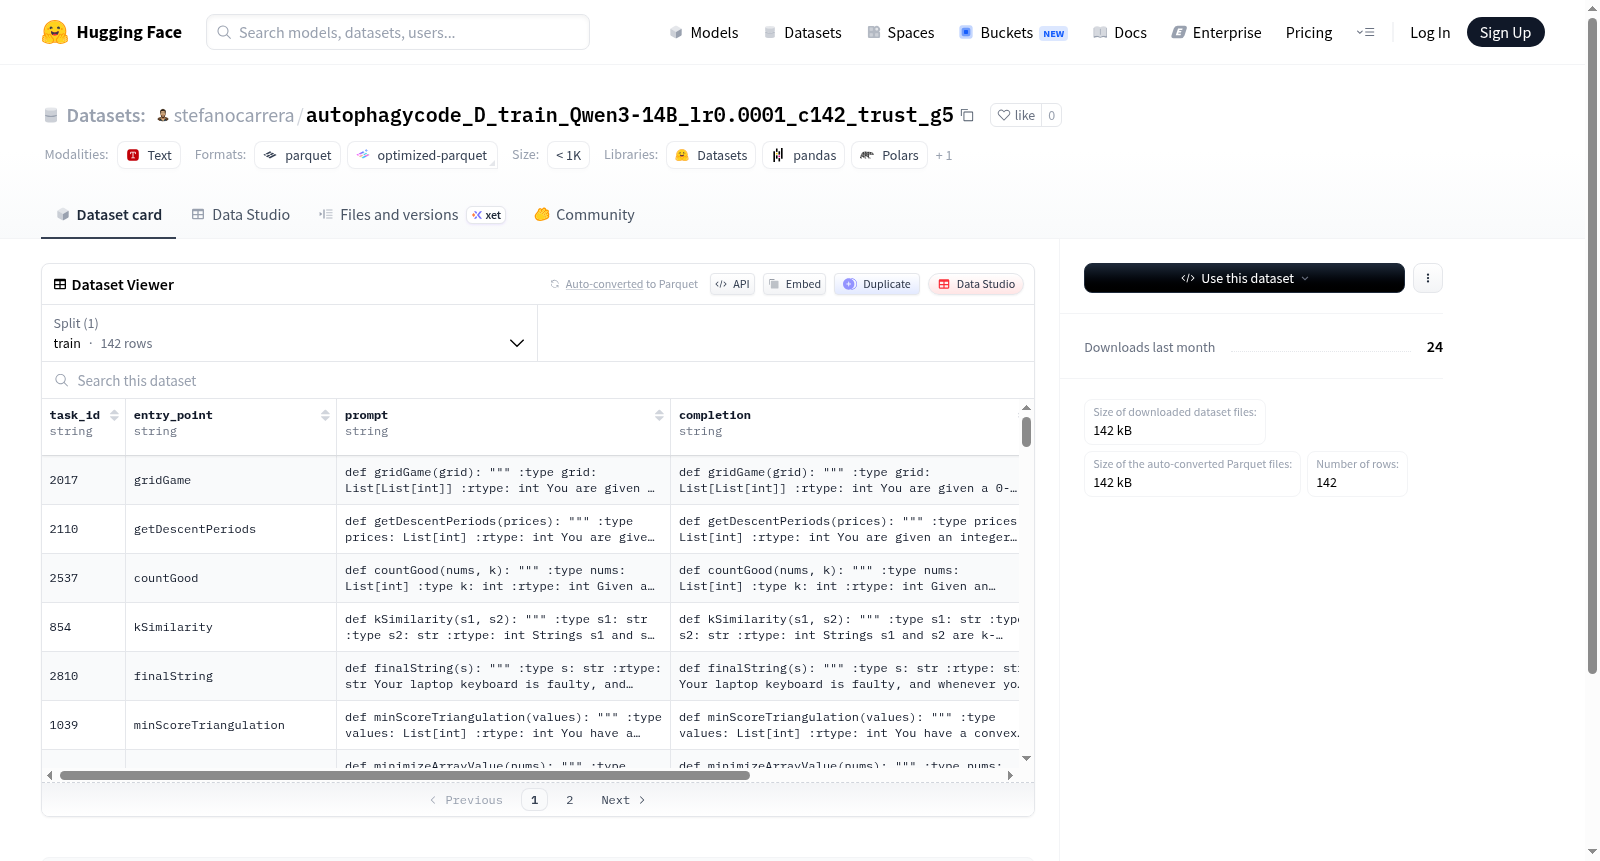
该数据集包含142个训练样本,总大小为327287字节。每个样本包含以下字段:'task_id'(字符串类型,表示任务标识符)、'entry_point'(字符串类型,可能表示程序入口点)、'prompt'(字符串类型,可能表示输入提示)、'completion'(字符串类型,可能表示完成文本或代码)以及'test'(字符串类型,可能表示测试用例或验证内容)。数据集仅提供训练集拆分,下载大小为142400字节。由于缺乏背景描述,推测可能用于代码生成、文本补全或任务导向型自然语言处理任务。
This dataset contains 142 training samples, with a total size of 327,287 bytes. Each sample includes the following fields: 'task_id' (string type, representing the task identifier), 'entry_point' (string type, potentially denoting the program entry point), 'prompt' (string type, potentially referring to the input prompt), 'completion' (string type, potentially representing the completed text or code), and 'test' (string type, potentially indicating test cases or validation content). The dataset only provides a training set split, with a download size of 142,400 bytes. Given the lack of background descriptions, it is speculated that this dataset may be used for code generation, text completion, or task-oriented natural language processing tasks.