stefanocarrera/autophagycode_D_he_train-mercury_Qwen3-4B_strategy_trust_t1.25_g8_run0_metrics
收藏资源简介:
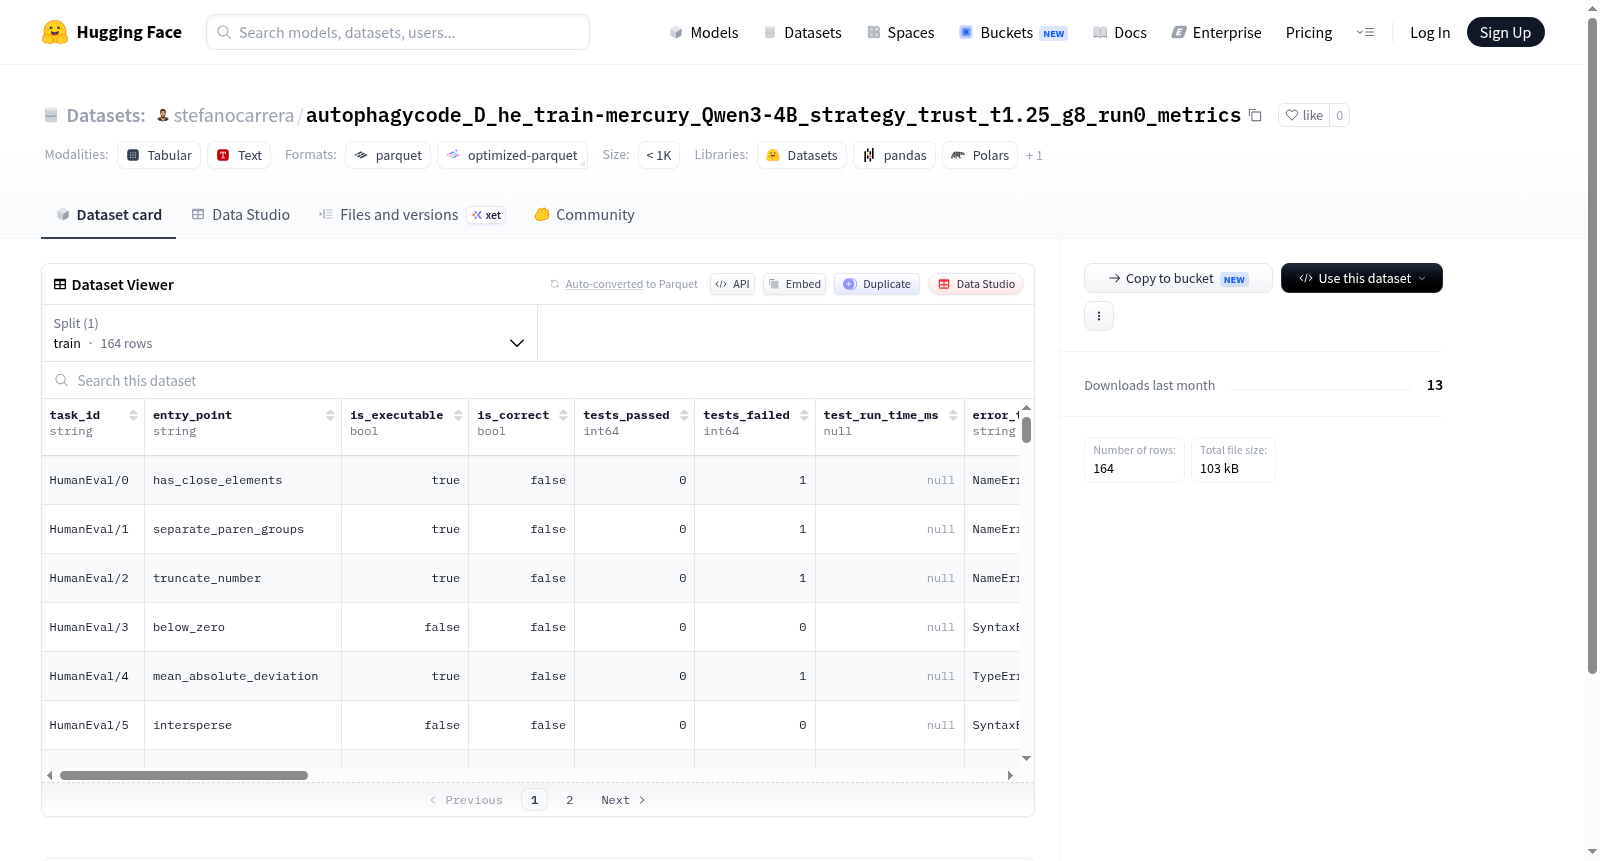
该数据集是一个用于代码分析的数据集,包含164个示例,每个示例代表一个代码任务,具有任务ID、入口点、可执行性、正确性、测试通过/失败数量、测试运行时间(当前为null)、错误类型等字段。此外,数据集还提供了代码复杂度度量,包括Halstead词汇量、长度、体积、难度、努力程度和时间,圈复杂度,可维护性指数,代码行数(LOC和SLOC),注释百分比,类型标记比(TTR),标记字典,香农熵,平均和最大预测熵,定义函数数量,以及入口点重复标记。这些特征可用于评估代码质量、复杂性和执行性能,适用于机器学习或静态分析任务。
This dataset is a code analysis dataset containing 164 examples, each representing a code task with fields such as task_id, entry_point, is_executable, is_correct, tests_passed, tests_failed, test_run_time_ms (currently null), error_type, and code complexity metrics including Halstead vocabulary, length, volume, difficulty, effort, and time, cyclomatic complexity, maintainability index, lines of code (LOC and SLOC), comment percentage, type-token ratio (TTR), token dictionary, Shannon entropy, mean and max predictive entropy, number of defined functions, and entry_point_repeated. These features are useful for evaluating code quality, complexity, and execution performance, suitable for machine learning or static analysis tasks.