rinabuoy/khmer-speech-dataset
收藏资源简介:
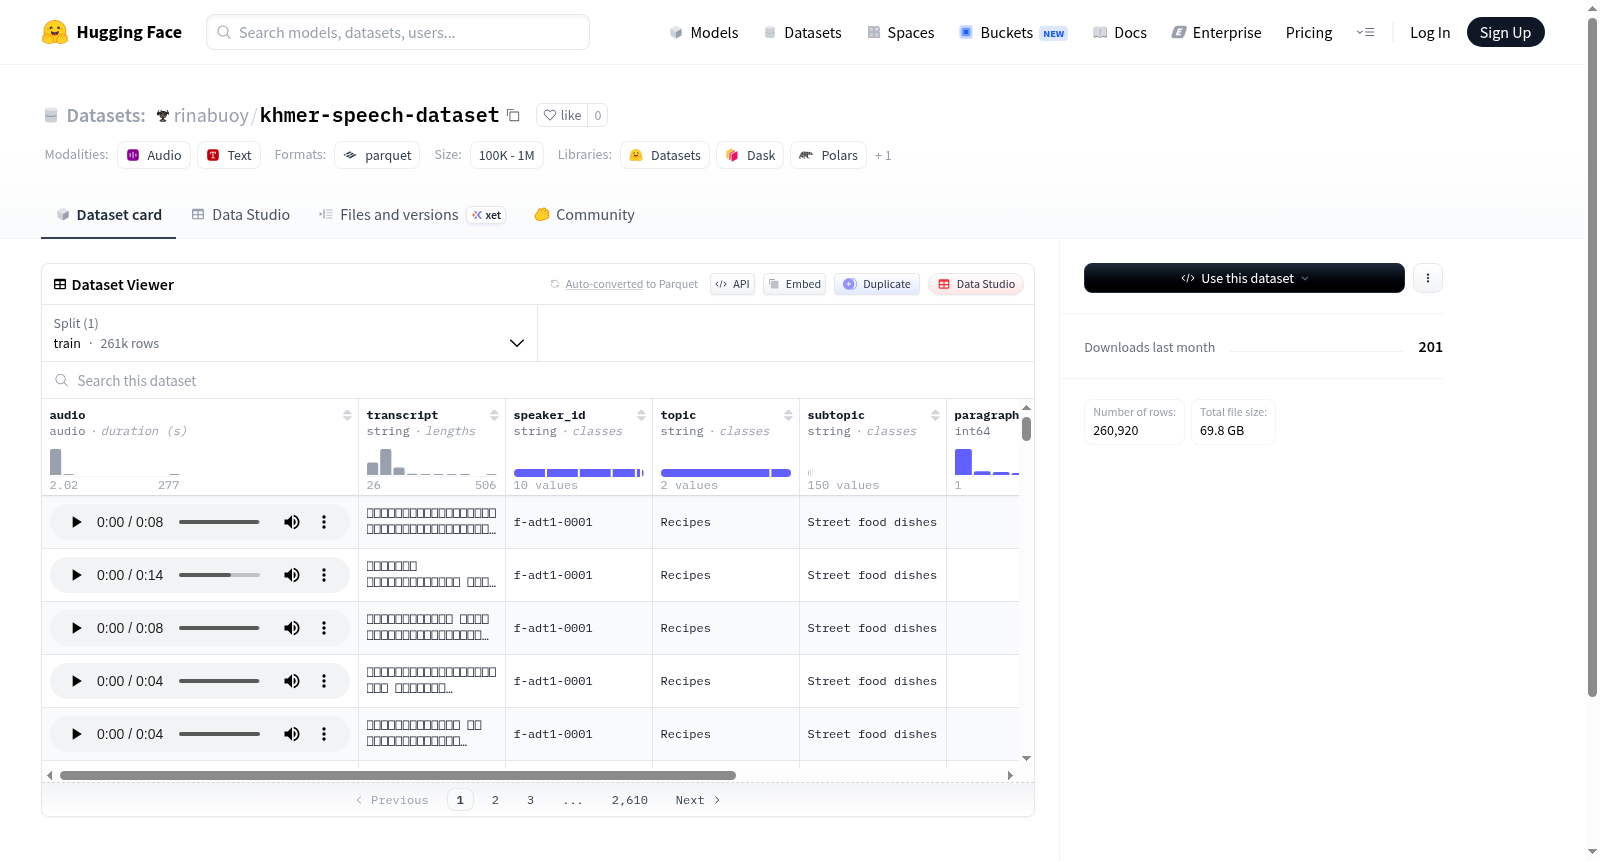
该数据集是一个语音数据集,包含音频文件及其对应的转录文本。音频特征包括采样率为16000Hz的音频数据,其他特征包括说话人ID、主题、子主题、段落ID、句子ID和音频时长。数据集分为训练集,包含260,920个示例,总大小约为70.06 GB,下载大小约为69.77 GB。数据文件路径为data/train-*,适用于语音识别和相关NLP任务的研究与应用。
This dataset is a speech dataset containing audio files and their corresponding transcriptions. The audio features include audio data with a sampling rate of 16000 Hz. Other features include speaker ID, topic, sub-topic, paragraph ID, sentence ID, and audio duration. The dataset is split into the training set, which contains 260,920 examples, with a total size of approximately 70.06 GB and a download size of about 69.77 GB. The data file path is data/train-*, and it is suitable for research and applications of speech recognition and related natural language processing (NLP) tasks.