ucberkeley-dlab/measuring-hate-speech
收藏资源简介:
这是一个公开发布的数据集,包含39,565条评论,由7,912名注释者标注,共计135,556行数据。主要的结果变量是“仇恨言论分数”,但10个构成的有序标签(情感、(不)尊重、侮辱、羞辱、低等地位、暴力、非人化、种族灭绝、攻击/防御、仇恨言论基准)也可以作为结果变量。数据集包括8个目标身份群体(种族/民族、宗教、国籍/公民身份、性别、性取向、年龄、残疾、政治意识形态)和42个目标身份子群体,以及6个注释者人口统计信息和40个子群体。仇恨言论分数通过估计注释者对标注指南解释的差异,结合IRT调整。
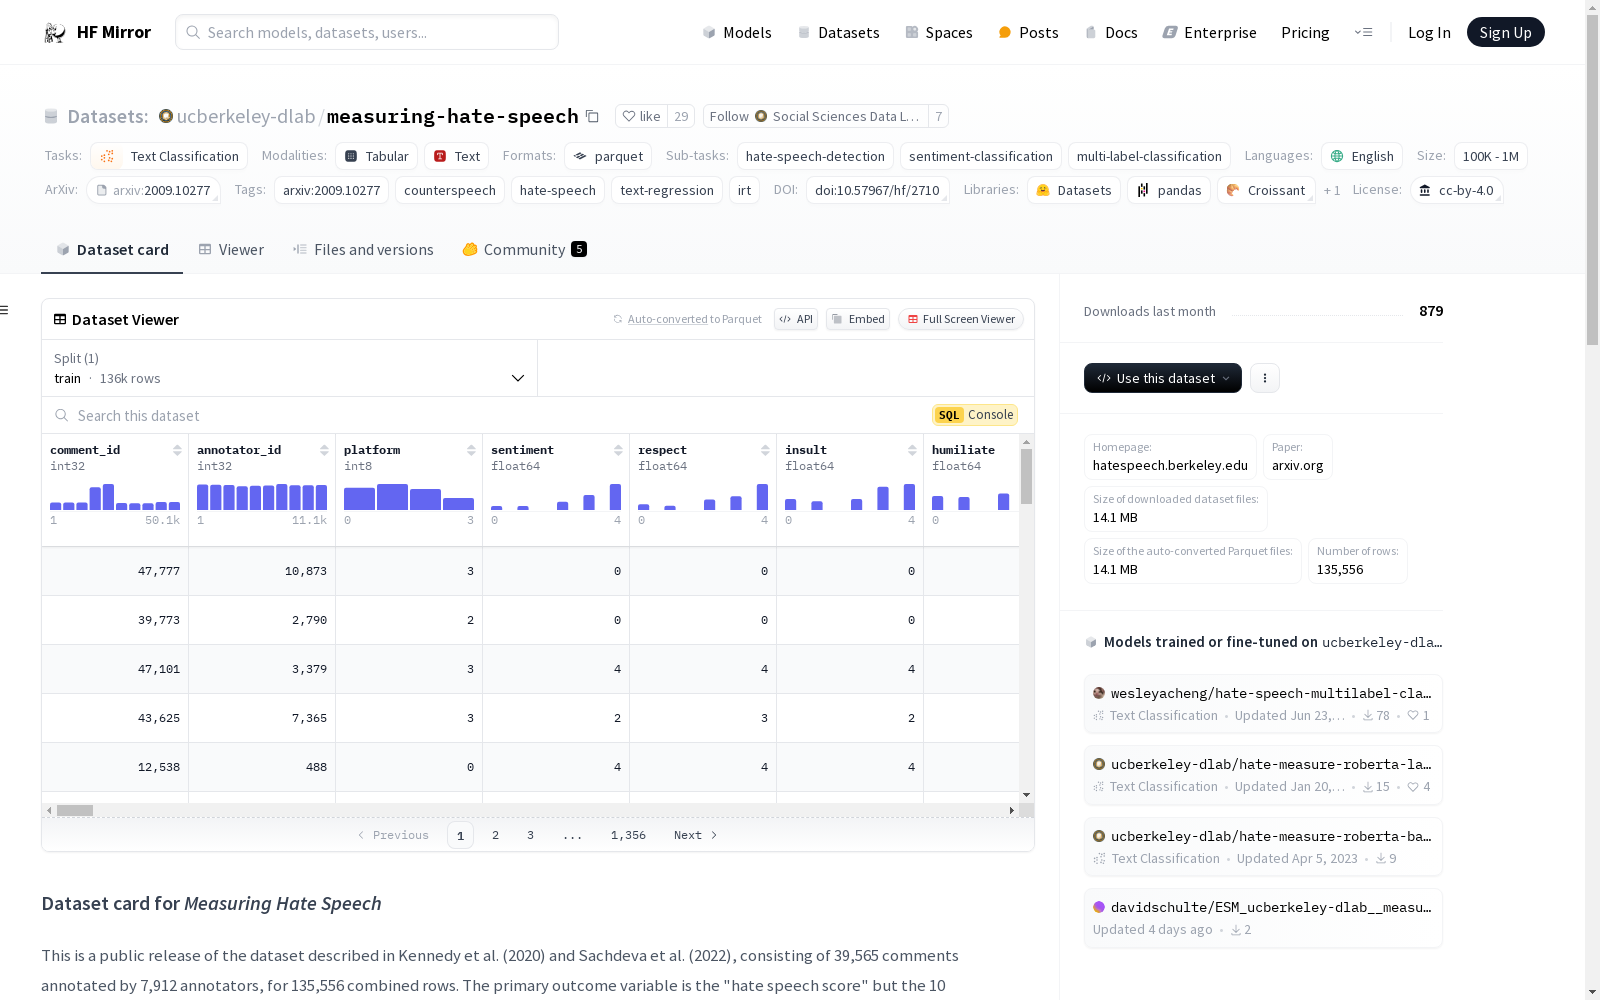
This is a publicly available dataset consisting of 39,565 comments annotated by 7,912 annotators, with a total of 135,556 data rows. The primary outcome variable is the Hate Speech Score, while ten constituent ordered labels including sentiment, (dis)respect, insult, humiliation, inferior status, violence, dehumanization, genocide, attack/defense, and hate speech baseline can also serve as outcome variables. The dataset covers 8 target identity groups (race/ethnicity, religion, nationality/citizenship, gender, sexual orientation, age, disability, political ideology) and 42 target identity subgroups, in addition to 6 annotator demographic characteristics and 40 subgroups. The Hate Speech Score is calibrated using Item Response Theory (IRT) by estimating the discrepancies in annotators' interpretations of the annotation guidelines.
数据集概述
基本信息
- 名称: Measuring Hate Speech
- 语言: 英语
- 许可证: CC-BY-4.0
- 数据来源: 原始数据
- 任务类别: 文本分类
- 任务ID:
- 仇恨言论检测
- 情感分类
- 多标签分类
数据集描述
- 数据集大小: 包含39,565条评论,由7,912名标注者完成,总计135,556行数据。
- 主要变量: 仇恨言论得分,以及10个构成的序数标签(情感、尊重、侮辱、羞辱、低等地位、暴力、非人化、种族灭绝、攻击/防御、仇恨言论基准)。
- 目标身份组: 8个(种族/民族、宗教、国籍/公民身份、性别、性取向、年龄、残疾、政治意识形态)及42个子组。
- 标注者人口统计: 6个及40个子组。
- 仇恨言论得分调整: 通过估计标注者对标注指南解释的变异进行IRT调整。
关键数据列
- hate_speech_score: 连续的仇恨言论测量,数值越高表示越仇恨,低于-1表示反对或支持言论,-1至+0.5表示中性或模糊。
- text: 社交媒體帖子的轻度处理文本。
- comment_id: 每个评论的唯一ID。
- annotator_id: 每个标注者的唯一ID。
- sentiment: 序数标签,合并到连续得分中。
- respect: 序数标签,合并到连续得分中。
- insult: 序数标签,合并到连续得分中。
- humiliate: 序数标签,合并到连续得分中。
- status: 序数标签,合并到连续得分中。
- dehumanize: 序数标签,合并到连续得分中。
- violence: 序数标签,合并到连续得分中。
- genocide: 序数标签,合并到连续得分中。
- attack_defend: 序数标签,合并到连续得分中。
- hatespeech: 序数标签,合并到连续得分中。
- annotator_severity: 标注者估计的调查解释偏差。
数据集下载
使用以下Python代码下载数据集:
python
import datasets
dataset = datasets.load_dataset(ucberkeley-dlab/measuring-hate-speech, binary)
df = dataset[train].to_pandas()
df.describe()
引用信息
@article{kennedy2020constructing, title={Constructing interval variables via faceted Rasch measurement and multitask deep learning: a hate speech application}, author={Kennedy, Chris J and Bacon, Geoff and Sahn, Alexander and von Vacano, Claudia}, journal={arXiv preprint arXiv:2009.10277}, year={2020} }