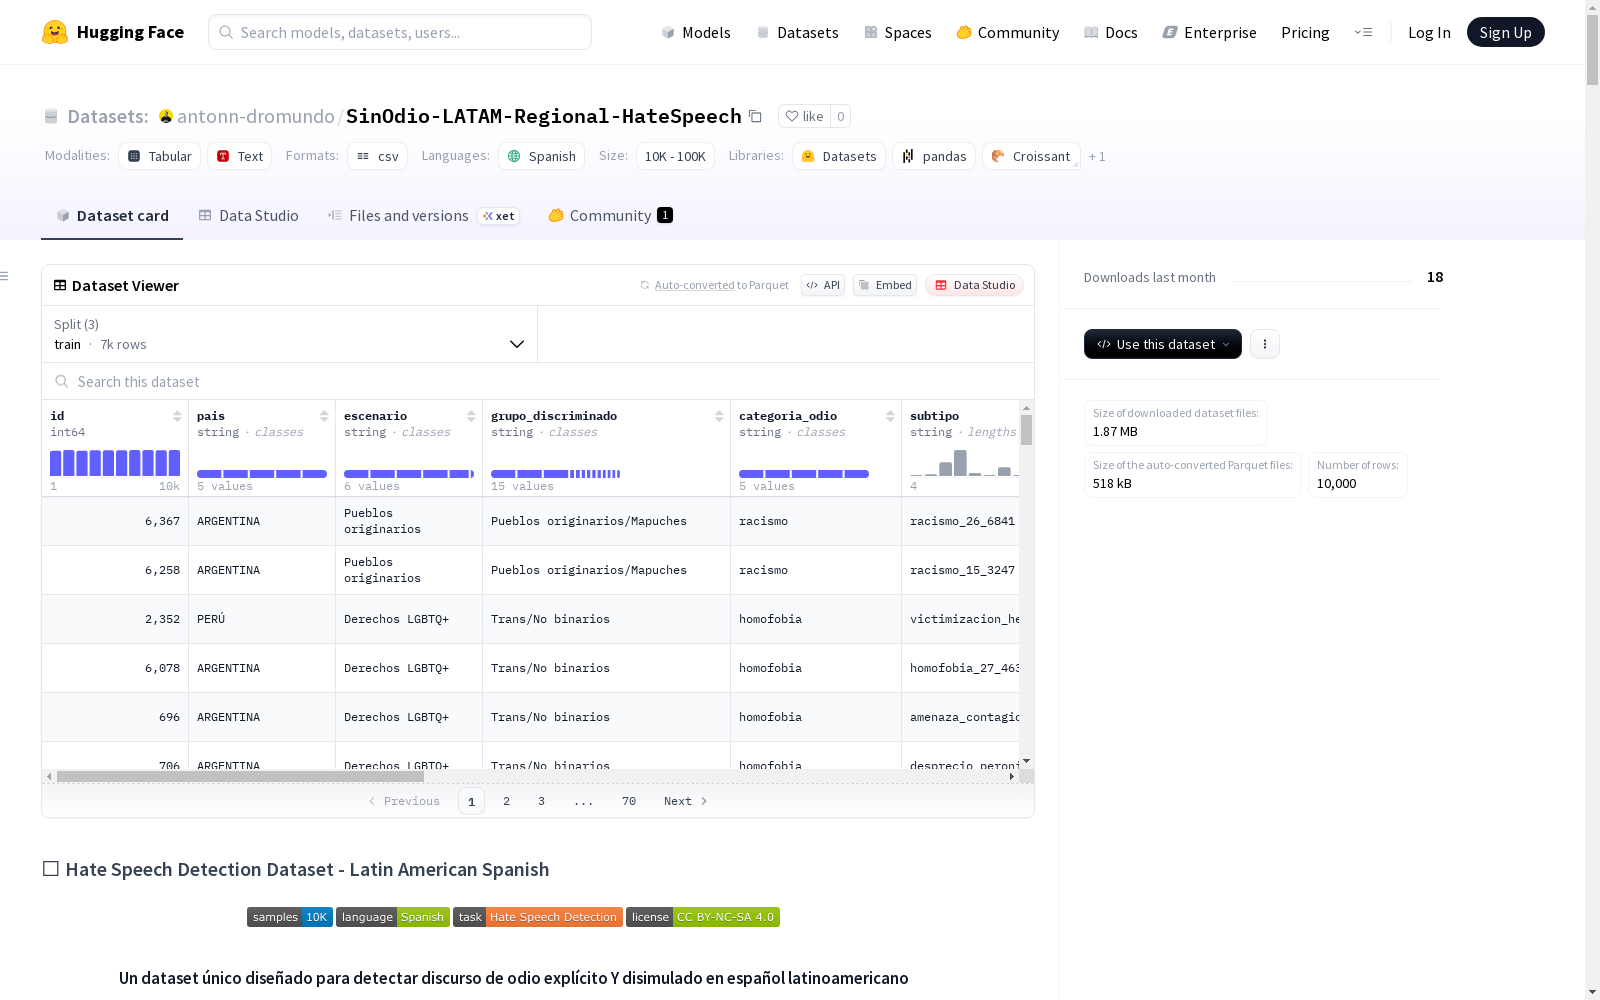
SinOdio-LATAM-Regional-HateSpeech
收藏资源简介:
这是一个专为检测拉丁美洲西班牙语中的仇恨言论而设计的独特数据集。它包含了10,000对示例,每对都包括显性和隐蔽的仇恨言论。数据集覆盖了5个拉丁美洲国家、5种仇恨言论类别和9,371种独特子类型。数据集被分为训练集、验证集和测试集,确保类别和国家的平衡。它还包括了地区的俚语和表达,使其真实和多样化。README强调以负责任和道德的方式使用数据集的重要性,并提供关于允许和禁止使用的指南。它是在CC BY-NC-SA 4.0许可下发布的,允许非商业共享和改编。
This is a unique dataset specifically designed for hate speech detection in Latin American Spanish. It contains 10,000 example pairs, each consisting of explicit and implicit hate speech. The dataset covers 5 Latin American countries, 5 hate speech categories, and 9,371 unique subtypes. It is split into training, validation and test sets, ensuring balanced distribution across categories and countries. It also includes regional slang and expressions, making it authentic and diverse. The accompanying README emphasizes the importance of using the dataset responsibly and ethically, and provides guidelines for permitted and prohibited uses. It is released under the CC BY-NC-SA 4.0 license, allowing non-commercial sharing and adaptation.
SinOdio-LATAM-Regional-HateSpeech 数据集概述
数据集基本信息
- 数据集名称: SinOdio-LATAM-Regional-HateSpeech
- 语言: 西班牙语
- 样本数量: 10,000对示例(总计20,000个文本)
- 任务: 仇恨言论检测
- 许可证: CC BY-NC-SA 4.0
数据集特色
- 专注于检测拉丁美洲西班牙语中的显性和隐性仇恨言论
- 每个示例包含同一偏见的两个版本:显性仇恨言论和隐性仇恨言论
- 覆盖5个拉丁美洲国家:墨西哥、哥伦比亚、阿根廷、智利、秘鲁
- 包含5种仇恨类别:仇外心理、恐同心理、种族主义、阶级歧视、宗教不容忍
数据分布
按国家分布
| 国家 | 示例数量 | 百分比 |
|---|---|---|
| 墨西哥 | 2,000 | 20% |
| 哥伦比亚 | 2,000 | 20% |
| 阿根廷 | 2,000 | 20% |
| 智利 | 2,000 | 20% |
| 秘鲁 | 2,000 | 20% |
按仇恨类别分布
| 类别 | 示例数量 | 百分比 | 主要目标群体 |
|---|---|---|---|
| 仇外心理 | 2,000 | 20% | 委内瑞拉人、中美洲人、玻利维亚人、海地人 |
| 恐同心理 | 2,000 | 20% | 跨性别/非二元性别者、LGBTQ+群体 |
| 种族主义 | 2,000 | 20% | 土著居民、马普切人、非裔哥伦比亚人 |
| 阶级歧视 | 2,000 | 20% | 贫困阶层 |
| 宗教不容忍 | 2,000 | 20% | 非天主教徒 |
数据集结构
主要列
id: 唯一标识符pais: 原产国escenario: 社会背景grupo_discriminado: 仇恨目标群体categoria_odio: 主要仇恨类别subtipo: 具体子类别texto_original: 显性仇恨言论texto_disimulado: 隐性仇恨言论etiqueta_final: 标签
数据划分
| 划分 | 示例数量 | 百分比 | 用途 |
|---|---|---|---|
| 训练集 | 7,000 | 70% | 模型训练 |
| 验证集 | 1,500 | 15% | 超参数调整 |
| 测试集 | 1,500 | 15% | 最终评估 |
关键统计信息
- 独特子类型: 9,371个(93.7%的数据集)
- 文本长度统计:
- 显性文本:平均41个字符,中位数39,范围19-79
- 隐性文本:平均45个字符,中位数47,范围20-92
- 地区俚语: 每个国家包含25+个地区表达方式
引用信息
bibtex @dataset{dromundo2024sinodio_latam, title={SinOdio-LATAM-Regional-HateSpeech: Hate Speech Detection Dataset for Latin American Spanish}, author={Dromundo, Antonio}, year={2025}, publisher={Hugging Face}, howpublished={url{https://huggingface.co/datasets/antonn-dromundo/SinOdio-LATAM-Regional-HateSpeech}}, note={10,000 paired examples of explicit and subtle hate speech across 5 Latin American countries} }
使用限制
- 允许用途: 学术研究、内容审核系统开发、模型训练、教育目的
- 禁止用途: 生成新仇恨言论、训练模型创建攻击性内容、传播仇恨言论