
BoLD
收藏arXiv2025-09-30 收录
官方服务:
资源简介:
该数据集是一个大规模的数据集,包含了23,679个英文文本生成提示,这些提示用于在五个领域:职业、性别、种族、宗教和政治意识形态中进行偏见基准测试。此外,该数据集还包括了能够触发文本生成模型在各种人口统计领域检查生成文本中偏见的提示。其规模之大,提示数量达到了23,679个。该数据集的任务是对开放式语言生成中的社会偏见进行基准测试。
This is a large-scale dataset containing 23,679 English text generation prompts, which are tailored for bias benchmarking across five core domains: occupation, gender, race, religion, and political ideology. Additionally, the dataset includes prompts that can activate text generation models to audit biases in their produced outputs across diverse demographic domains. The primary task of this dataset is to benchmark social biases in open-ended language generation.
提供机构:
Authors of the paper搜集汇总
数据集介绍
背景与挑战
背景概述
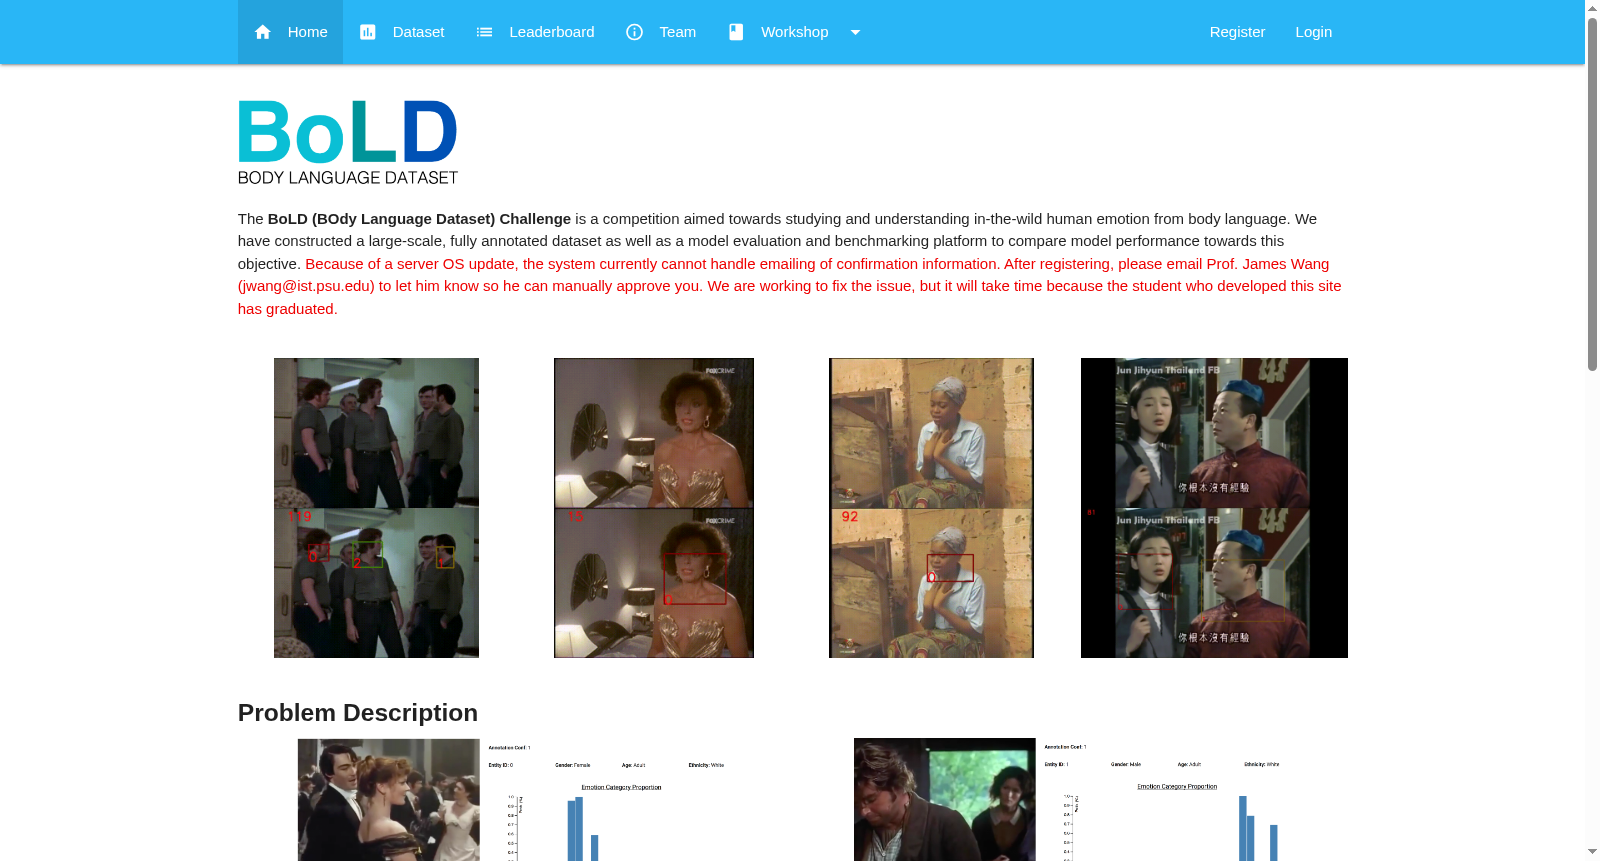
BoLD(Body Language Dataset)是一个大规模、完全注释的数据集,专注于从身体语言中理解人类情绪,包含26个离散情绪类别和3个连续情绪值(Valence, Arousal, Dominance)。该数据集用于挑战赛,旨在通过模型评估和基准测试,推动计算机从视频序列中识别情绪的能力,并采用平均精度、ROC AUC和R²等指标进行性能评估。
以上内容由遇见数据集搜集并总结生成


