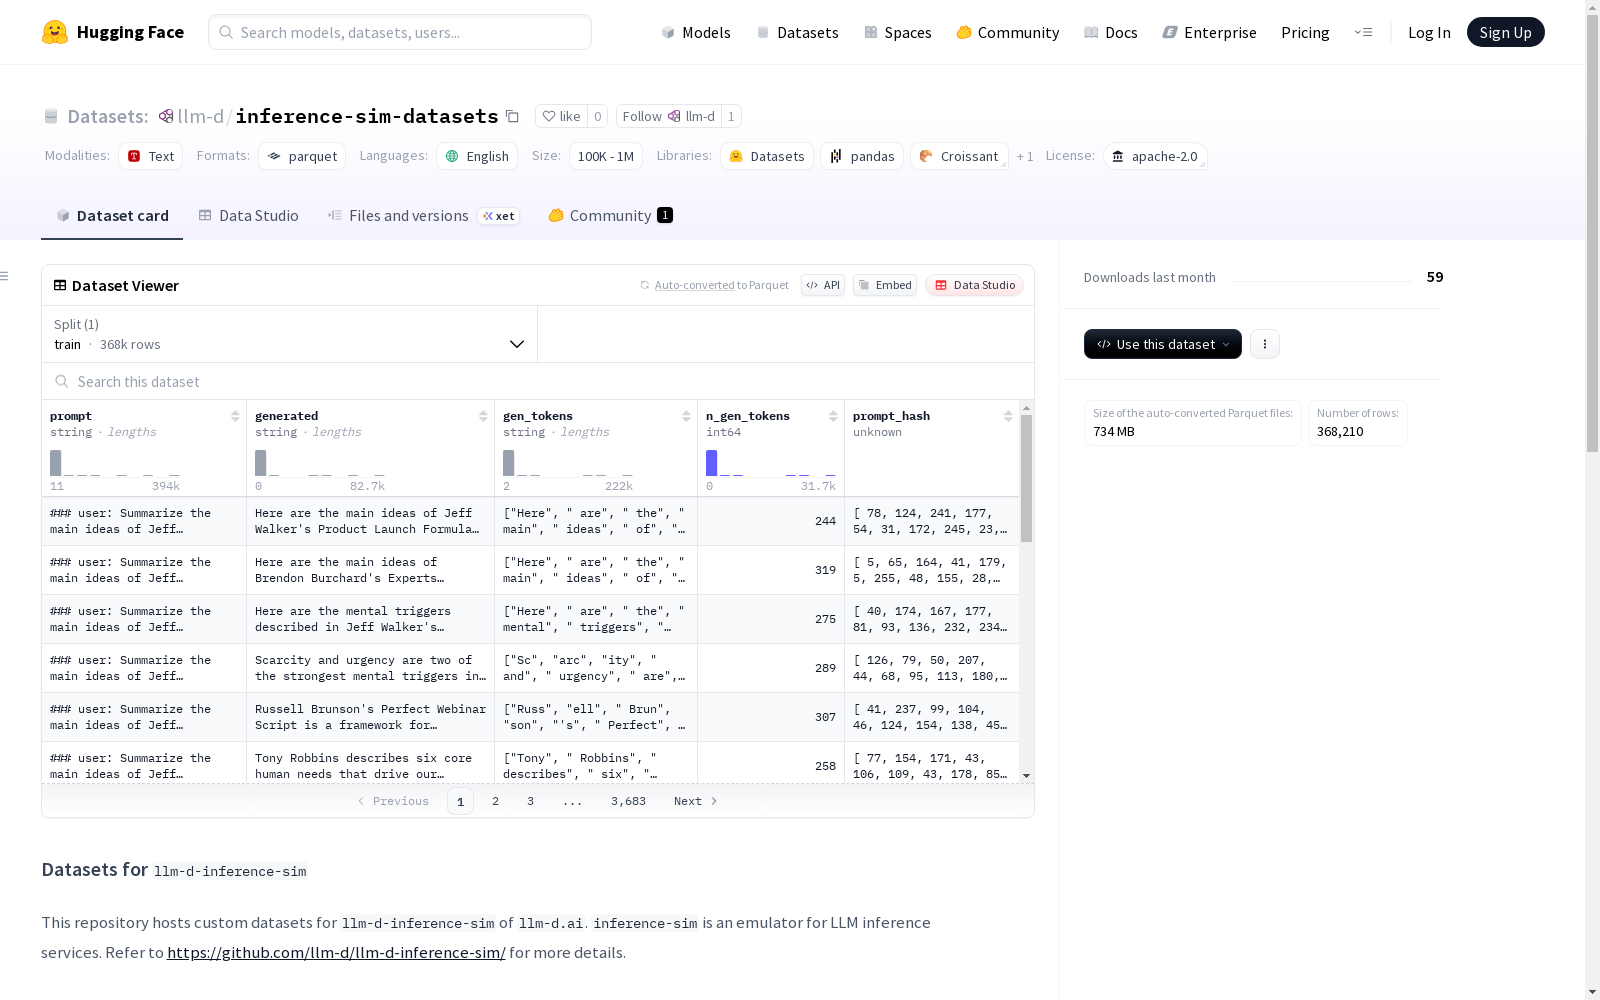
inference-sim-datasets
收藏资源简介:
该数据集是针对llm-d.ai的llm-d-inference-sim模块定制的,用于模拟LLM推理服务。数据集包括未经过滤的ShareGPT Vicuna对话数据,以SQLite3数据库文件的形式存在。数据库中包含了一个名为llmd的表,其中包含prompt_hash、gen_tokens和n_gen_tokens三个字段。
This dataset is customized for the llm-d-inference-sim module of llm-d.ai, and is used to simulate LLM inference services. The dataset includes unfiltered ShareGPT Vicuna conversation data, stored in the form of SQLite3 database files. The database contains a table named `llmd` with three fields: prompt_hash, gen_tokens, and n_gen_tokens.
数据集概述
基本信息
- 许可证: Apache 2.0
- 语言: 英语 (en)
数据集用途
该数据集为 llm-d-inference-sim 提供支持,后者是 llm-d.ai 的 LLM 推理服务模拟器。
数据集来源
- 原始数据集:
anon8231489123/ShareGPT_Vicuna_unfiltered - 原始数据集地址: https://huggingface.co/datasets/anon8231489123/ShareGPT_Vicuna_unfiltered/tree/main
数据处理
-
数据格式转换: 从
ShareGPT_V3_unfiltered_cleaned_split.json创建了 SQLite3 数据库文件。 -
数据库表结构: sql CREATE TABLE llmd ( prompt_hash BLOB PRIMARY KEY, gen_tokens JSON, n_gen_tokens INTEGER );
-
主键生成:
prompt_hash通过 SHA256 哈希生成,源数据为full_prompt。 -
提示词格式: python full_prompt = "" for msg in messages: if msg.role == "human": full_prompt += f"### user: {msg.content} " else: full_prompt += f"### assistant: {msg.content} "
详细信息
更多详情可参考: https://huggingface.co/datasets/llm-d/inference-sim-datasets/tree/980e326f222e3e7390eef9df02a4f5e77d2a6da0/huggingface/ShareGPT_Vicuna_unfiltered