ardauzunoglu/dpo_smollm2_17b_instruct_0528_c4_lowq_200m2b_subsample20m_grpo_prompt
收藏资源简介:
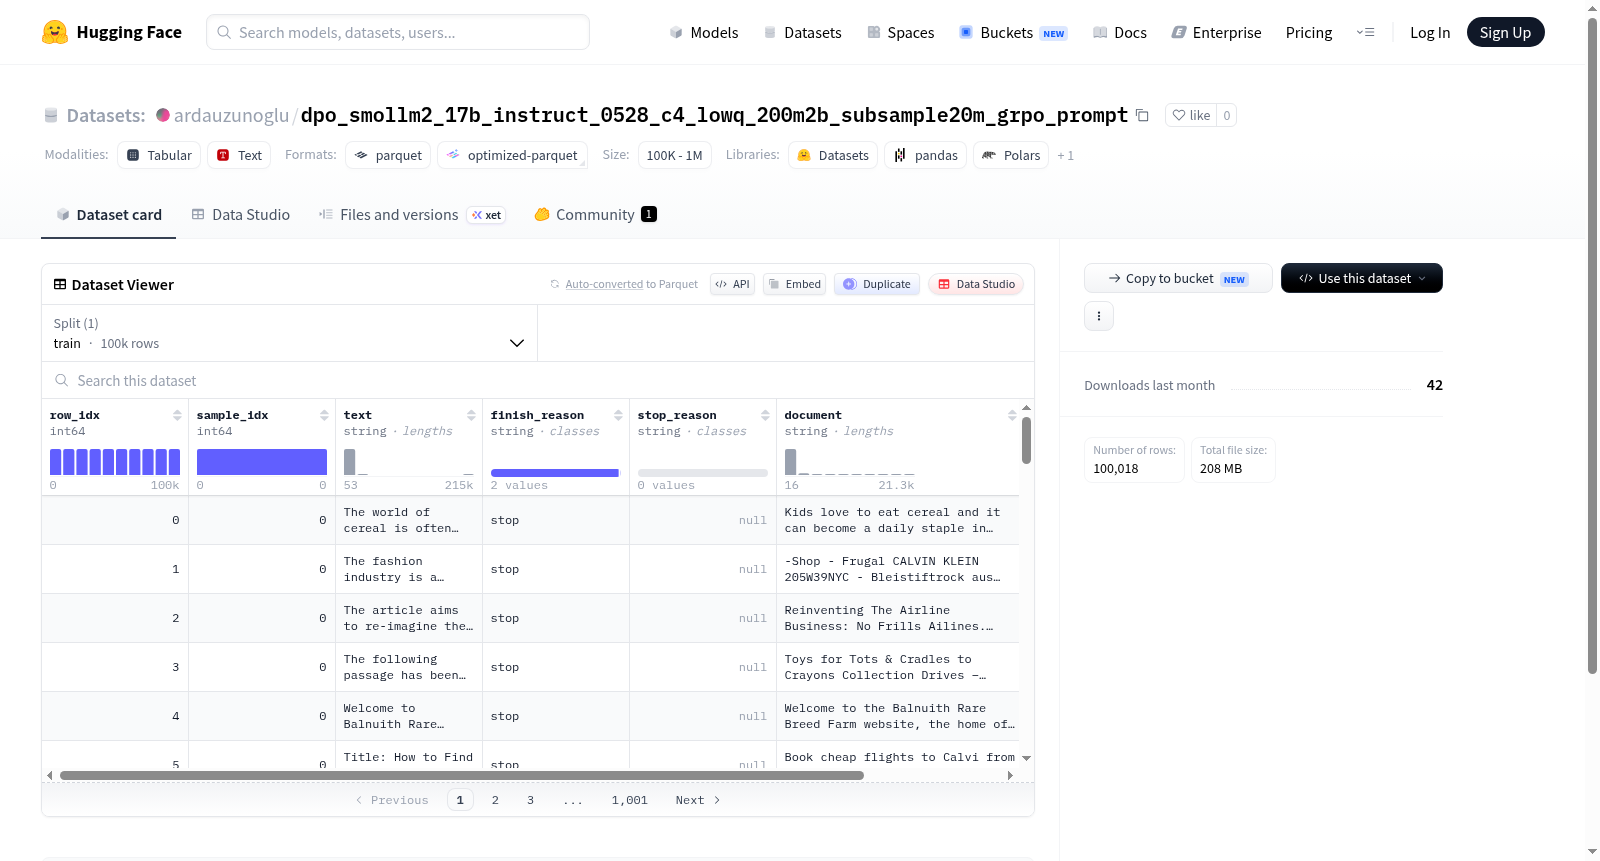
该数据集是一个大型训练数据集,包含100,018个示例,总大小为368,805,866字节。特征包括行索引(row_idx)、样本索引(sample_idx)、文本内容(text)、完成原因(finish_reason)、停止原因(stop_reason)、文档标识(document)和提示令牌计数(prompt_token_count),数据类型主要为整型和字符串。数据集仅提供train分割,用于机器学习和自然语言处理任务,可能涉及文本生成或分析,但具体应用未在README中说明。
This dataset is a large-scale training dataset containing 100,018 examples with a total size of 368,805,866 bytes. Features include row index (row_idx), sample index (sample_idx), text content (text), finish reason (finish_reason), stop reason (stop_reason), document identifier (document), and prompt token count (prompt_token_count), with data types primarily integer and string. The dataset only provides a train split and is intended for machine learning and natural language processing tasks, potentially involving text generation or analysis, though specific applications are not detailed in the README.