structural-protein-families
收藏资源简介:
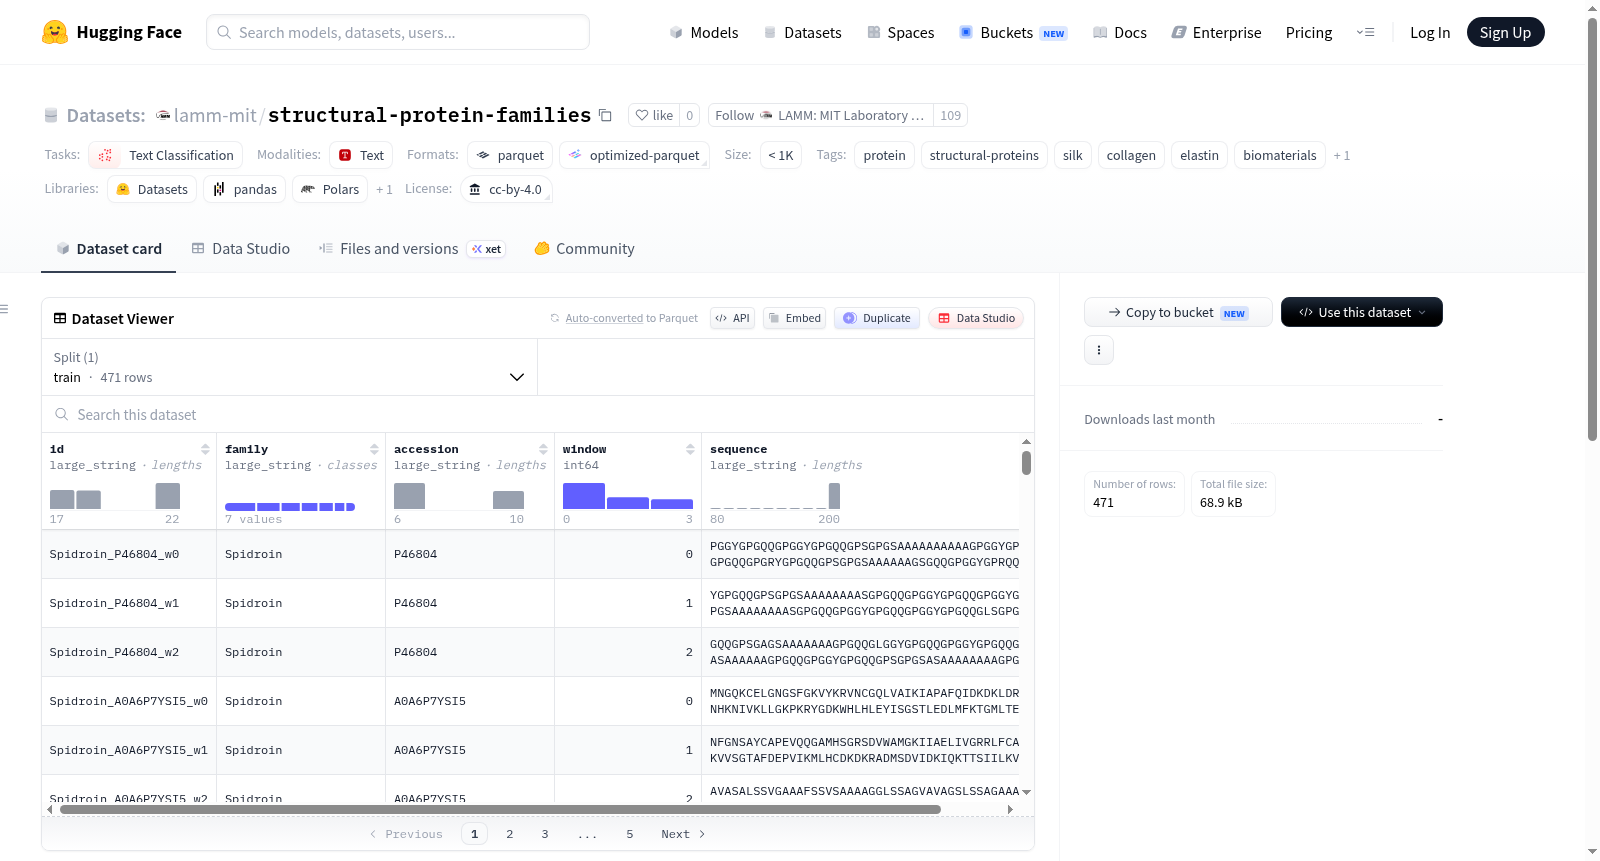
该数据集包含来自多个结构/生物材料蛋白家族(如蜘蛛丝蛋白、蚕丝丝蛋白、胶原蛋白、弹性蛋白、节肢弹性蛋白、角蛋白)以及作为对照的球状蛋白(如溶菌酶、肌红蛋白、细胞色素c)的氨基酸序列窗口。所有序列均提取自UniProt数据库,并被切割成重叠的固定长度窗口。数据集的每一行代表一个序列窗口,并附带一个指示其所属蛋白质家族的类别标签(family)。该数据集专为迁移学习演示而构建,旨在利用预训练的蛋白质语言模型(如ESM)生成的冻结嵌入,训练一个轻量级分类头来预测蛋白质序列窗口所属的家族。数据集包含以下字段:id(由家族标签、UniProt登录号和窗口索引组成的唯一标识符)、family(蛋白质家族类别标签)、accession(源蛋白质在UniProt中的登录号)、window(该窗口在源蛋白质序列中的索引位置)、sequence(氨基酸序列字符串,长度不超过200个残基)。序列窗口的生成规则为:窗口长度为200个氨基酸,滑动步长为150个氨基酸,每个源蛋白质最多取4个窗口。该数据集适用于蛋白质序列分类任务,特别是基于机器学习的蛋白质功能或家族预测研究。
This dataset contains amino acid sequence windows derived from multiple structural/bio-inspired material protein families, including spider silk protein, silkworm silk protein, collagen, elastin, resilin, and keratin, as well as globular proteins used as controls, such as lysozyme, myoglobin, and cytochrome c. All sequences are extracted from the UniProt database and segmented into overlapping fixed-length windows. Each row in the dataset represents a sequence window, accompanied by a category label (family) indicating the protein family it belongs to. This dataset is specifically constructed for transfer learning demonstrations, aiming to train a lightweight classification head using frozen embeddings generated by pre-trained protein language models (e.g., ESM) to predict the family that the protein sequence window belongs to. The dataset includes the following fields: - `id`: A unique identifier composed of the family label, UniProt accession number, and window index; - `family`: The category label of the protein family; - `accession`: The UniProt accession number of the source protein; - `window`: The index position of this window within the source protein sequence; - `sequence`: An amino acid sequence string with a maximum length of 200 residues. The sequence windows are generated according to the following rules: the window length is 200 amino acids, the sliding stride is 150 amino acids, and a maximum of 4 windows are extracted from each source protein. This dataset is suitable for protein sequence classification tasks, particularly machine learning-based research on protein function or family prediction.
数据集概述
名称:Structural-protein families (sequence windows)
许可证:CC-BY-4.0
任务类别:文本分类 (text-classification)
标签:蛋白质、结构蛋白、丝、胶原蛋白、弹性蛋白、生物材料、ESM
配置:
- 配置名:
default - 数据文件:
data/train-*(仅训练集)
数据集描述
该数据集包含来自多个结构/生物材料蛋白质家族(蜘蛛牵引丝、家蚕丝素、胶原蛋白、弹性蛋白、节肢弹性蛋白、角蛋白)以及球状蛋白对照(溶菌酶、肌红蛋白、细胞色素c)的氨基酸序列窗口。序列源自UniProt,被切割成重叠窗口;每一行带有family标签。
数据集专为EvolutionaryScale-protein-mechanics项目中的迁移学习演示构建,可用于在冻结的ESMC嵌入上训练轻量级分类头,以预测蛋白质家族。
数据列
id—<family>_<accession>_w<window>格式的唯一标识符family— 类别标签accession— 来源UniProt登录号window— 在源蛋白质中的窗口索引sequence— 氨基酸窗口序列(长度≤200个氨基酸)
数据来源
通过UniProt REST API按家族搜索获取(参见cli/make_dataset.py)。窗口长度为200个氨基酸,步长为150个氨基酸,每个蛋白质最多取4个窗口。序列版权归各自UniProt条目所有。