SPEEED_s3_words_multi_0-200000
收藏资源简介:
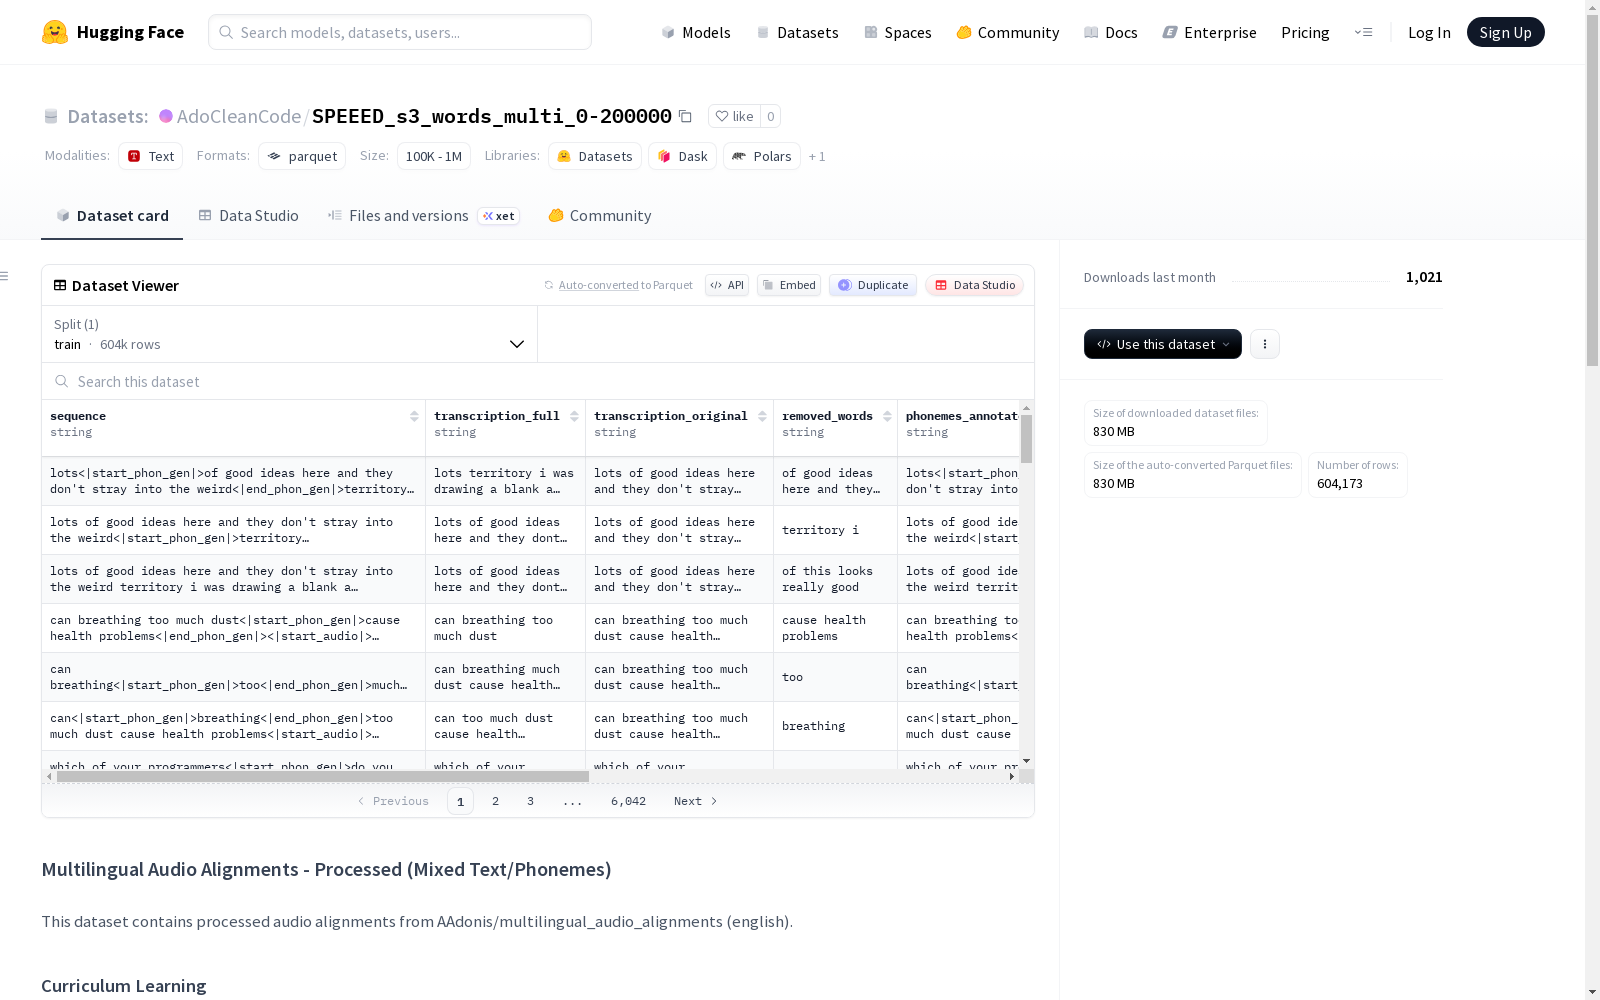
该数据集包含来自AAdonis/multilingual_audio_alignments(英语)的经过处理的音频对齐数据。数据集采用混合文本/音素条件,并结合课程学习计划,早期更多保留文本形式,后期几乎全部转换为音素。此外,20%的样本用于删除训练,旨在教导模型生成自然的词间过渡。数据集包含604,173个训练样本,主要特征包括:完整LLASA训练序列(sequence)、与实际音频匹配的转录(transcription_full)、原始完整转录(transcription_original)、移除的单词(removed_words)、带标记的混合文本/音素标记(phonemes_annotated)等。适用于音频对齐、语音生成等任务。
This dataset comprises processed audio alignment data sourced from the AAdonis/multilingual_audio_alignments (English) repository. It adopts mixed text/phoneme conditioning and integrates a curriculum learning schedule, where text-based forms are retained more in the early training stage, while nearly all are converted to phonemes in the later phase. Additionally, 20% of the samples are utilized for deletion training, with the goal of teaching models to generate natural inter-word transitions. The dataset contains 604,173 training samples, whose core features include: complete LLASA training sequences, full transcriptions matched to actual audio (transcription_full), original full transcriptions (transcription_original), removed words, annotated mixed text/phoneme tags (phonemes_annotated), and other related items. It is suitable for tasks such as audio alignment and speech generation.