slm-synthetic
收藏资源简介:
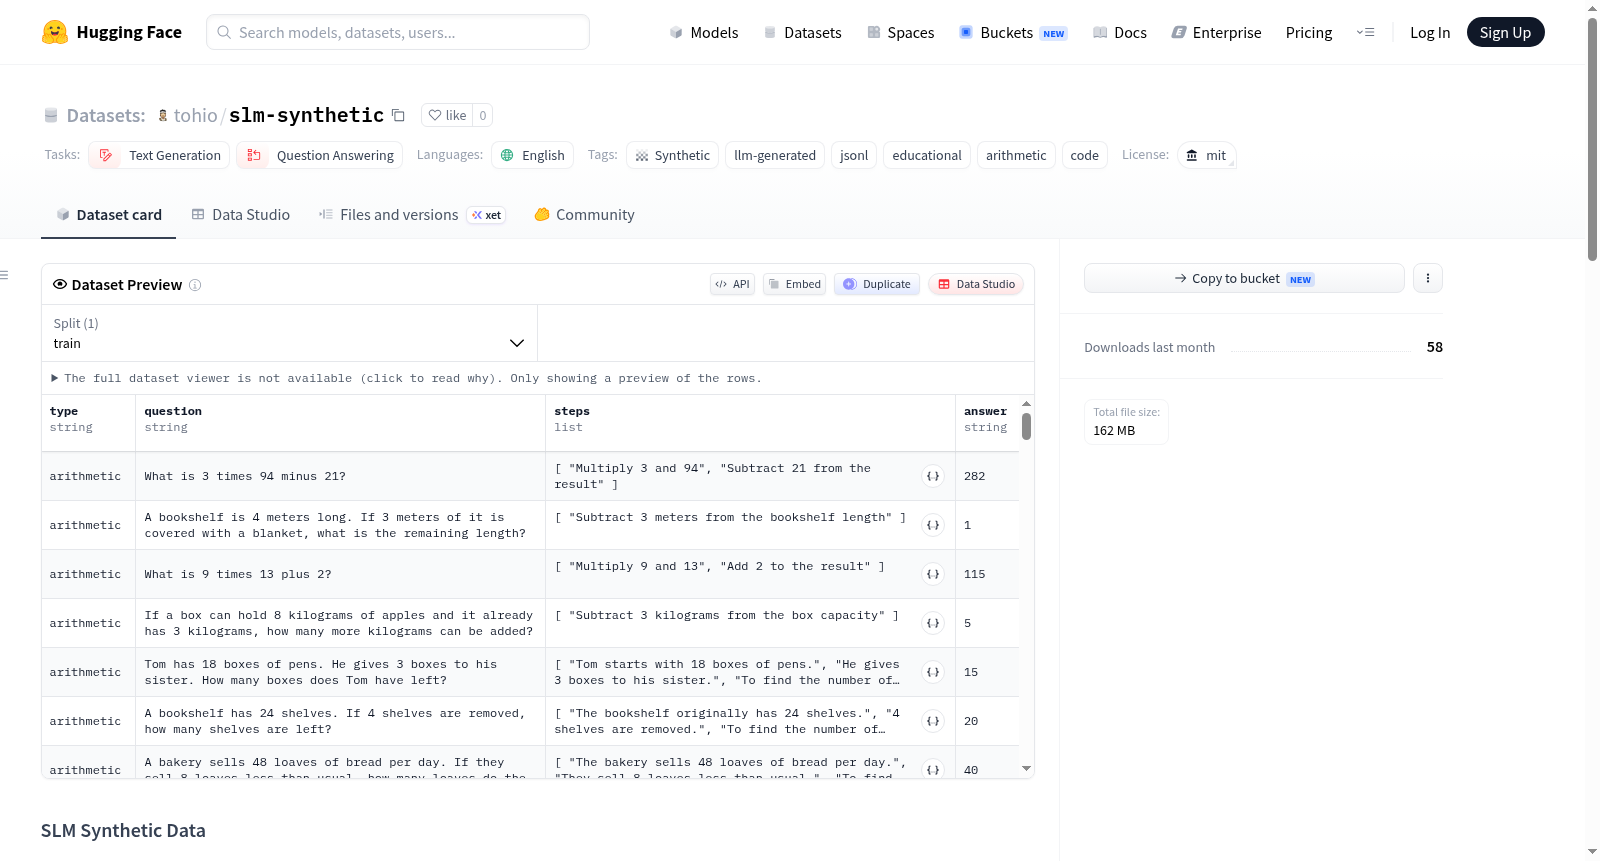
SLM Synthetic Data 是一个专为小型语言模型训练流水线设计的合成数据集,用于支持指令遵循、算术推理、简单编程任务、教育类多项选择题以及事实约束行为等方面的实验。该数据集包含513,064条记录,分为四个JSONL格式文件:算术推理文件(220,291条记录)包含类型、问题、步骤和答案字段;教育类问答文件(149,031条记录)包含类型、问题、选项、正确答案索引和解释字段;事实约束文件(51,523条记录)包含类型、问题和安全回答字段;编程任务文件(92,219条记录)包含类型、任务、计划和代码字段。数据由llama-3.1-8b-instant模型通过批量并行请求生成,并经过原始生成、模式验证和精确去重三个处理阶段。它适用于小型语言模型训练实验、合成数据生成流水线验证、指令遵循和响应格式实验,以及算术、多项选择、事实约束和简单编程行为检查等场景。但需注意,所有记录均为合成数据,可能包含错误或低质量示例,不应作为权威事实知识来源,代码示例较为简单,且合成数据分布可能与真实用户查询存在差异。
SLM Synthetic Data is a synthetic dataset specifically designed for small language model (SLM) training pipelines, supporting experiments on instruction following, arithmetic reasoning, simple programming tasks, educational multiple-choice questions, and fact-constrained behavior. This dataset contains 513,064 records, split into four JSONL-formatted files: the arithmetic reasoning file (220,291 records) with fields including type, question, steps, and answer; the educational question answering file (149,031 records) with fields including type, question, options, correct answer index, and explanation; the fact-constrained file (51,523 records) with fields including type, question, and safe response; and the programming task file (92,219 records) with fields including type, task, plan, and code. The dataset was generated via batch parallel requests using the llama-3.1-8b-instant model, and processed through three stages: raw generation, schema validation, and exact deduplication. It is applicable to small language model training experiments, validation of synthetic data generation pipelines, experiments on instruction following and response formats, as well as scenarios such as arithmetic, multiple-choice, fact-constrained, and simple programming behavior checks. However, it should be noted that all records are synthetic data, which may contain errors or low-quality examples, and should not be treated as an authoritative source of factual knowledge. The code examples are relatively simple, and the distribution of the synthetic data may differ from that of real user queries.