openpecha/tibetan-metadata-llm-sft-full
收藏资源简介:
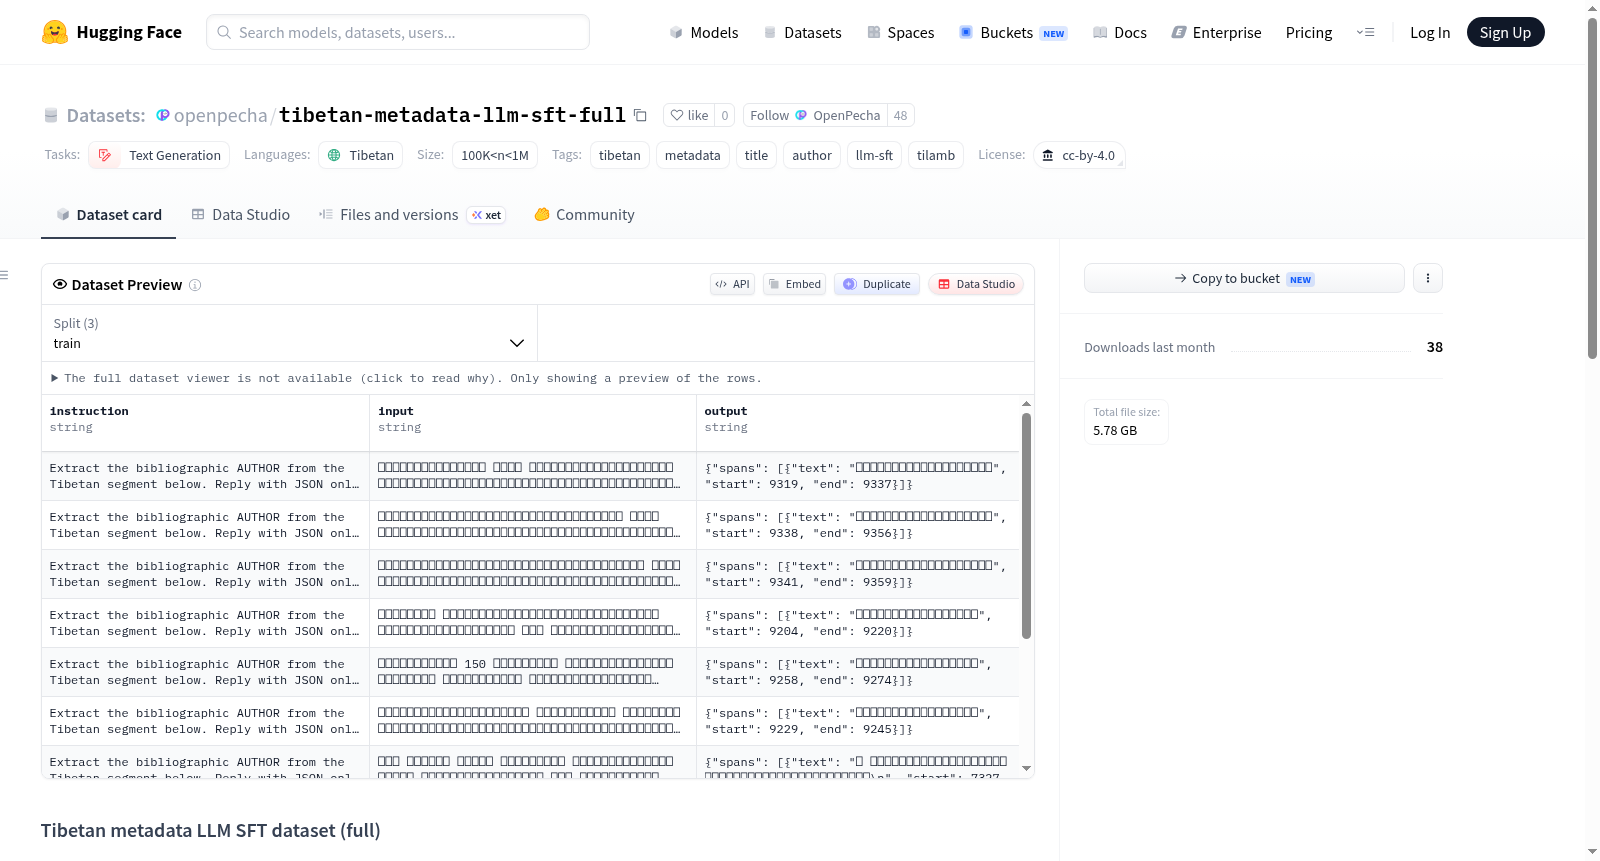
这是一个完整的监督微调(SFT)JSONL数据集,专门用于从BDRC大纲片段中提取标题和作者跨度,旨在支持TiLamb-7B模型。数据集包含两个主要任务:标题提取和作者提取,每个任务都有训练、验证和测试文件,采用Alpaca格式以便与LLaMA-Factory兼容。数据行包括指令(固定任务提示)、输入(裁剪后的片段文本,通过TiLamb分词器限制在≤3584个token内)和输出(JSON格式的跨度信息,包含文本、起始和结束位置,使用裁剪相对偏移)。裁剪策略分为三种:完整(整个片段符合token预算)、正向(随机窗口包含黄金跨度,以减少位置偏差)和负向(随机窗口,该任务无跨度)。数据集来源于ganga4364/tibetan-metadata-extracted(共3794个文档),并使用OpenPecha/tibetan-text-meta-detection的llm_sft包构建。数据集语言为藏语(bo),标签包括藏语、元数据、标题、作者、llm-sft和tilamb,规模在10万到1百万之间,适用于文本生成任务。
This is a comprehensive Supervised Fine-Tuning (SFT) JSONL dataset dedicated to extracting title and author spans from BDRC outline fragments, tailored to support the TiLamb-7B model. The dataset encompasses two primary tasks: title extraction and author extraction. Each task has corresponding training, validation, and test files, formatted in Alpaca style for compatibility with LLaMA-Factory. Each data entry comprises three components: an instruction (fixed task prompt), input (cropped fragment text, restricted to ≤3584 tokens using the TiLamb tokenizer), and output (JSON-formatted span information including text, start and end positions, with cropped relative offsets). Three cropping strategies are employed: 1. Full: the entire fragment falls within the token budget 2. Forward: a random window that includes the gold span to mitigate positional bias 3. Negative: a random window with no target span for the given task The dataset is derived from ganga4364/tibetan-metadata-extracted (totaling 3794 documents) and constructed using the llm_sft package from OpenPecha/tibetan-text-meta-detection. The dataset is in Tibetan (bo), with tags including Tibetan, metadata, title, author, llm-sft, and tilamb. Its scale ranges from 100,000 to 1,000,000, and it is applicable to text generation tasks.