thliang01/tw-legal-synthetic-qa
收藏资源简介:
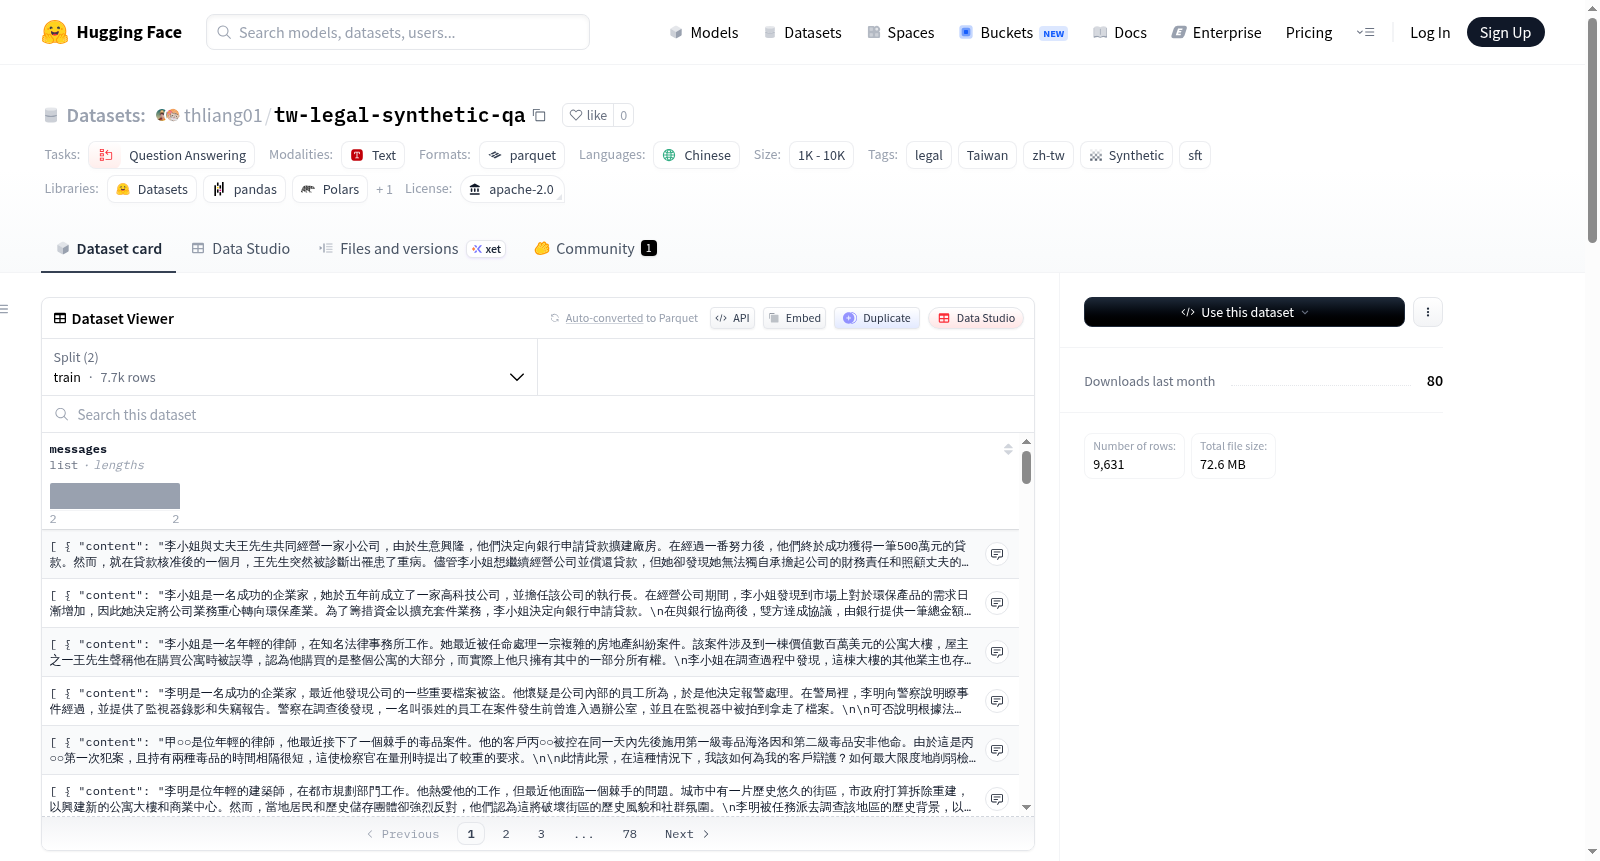
本合成对话数据集(下称本数据集)由THUDM/chatglm3-6b-32k和lianghsun/tw-processed-judgments生成,通过实验后的prompt生成繁体中文法律对话合成集。数据集可以用于SFT,让模型学会如何回答法律问题。数据集包含9,631笔数据,分为训练集(7,704笔)、评估集(963笔)和测试集(964笔)。数据集的生成过程中使用了正则表示法和人工审阅来纠正错误格式,但可能仍存在少量不符合要求的文本。数据集的语言为繁体中文,许可证为apache-2.0。
This synthetic dialogue dataset (hereinafter referred to as this dataset) is generated by THUDM/chatglm3-6b-32k and lianghsun/tw-processed-judgments, producing a traditional Chinese legal dialogue synthetic set through experimental prompts. The dataset can be used for SFT to train models on how to answer legal questions. It contains 9,631 data points, divided into training set (7,704), evaluation set (963), and test set (964). During the generation process, regular expressions and manual review were used to correct formatting errors, but there may still be a small number of texts that do not meet the requirements. The dataset is in traditional Chinese and licensed under apache-2.0.