DONG19/TACO
收藏资源简介:
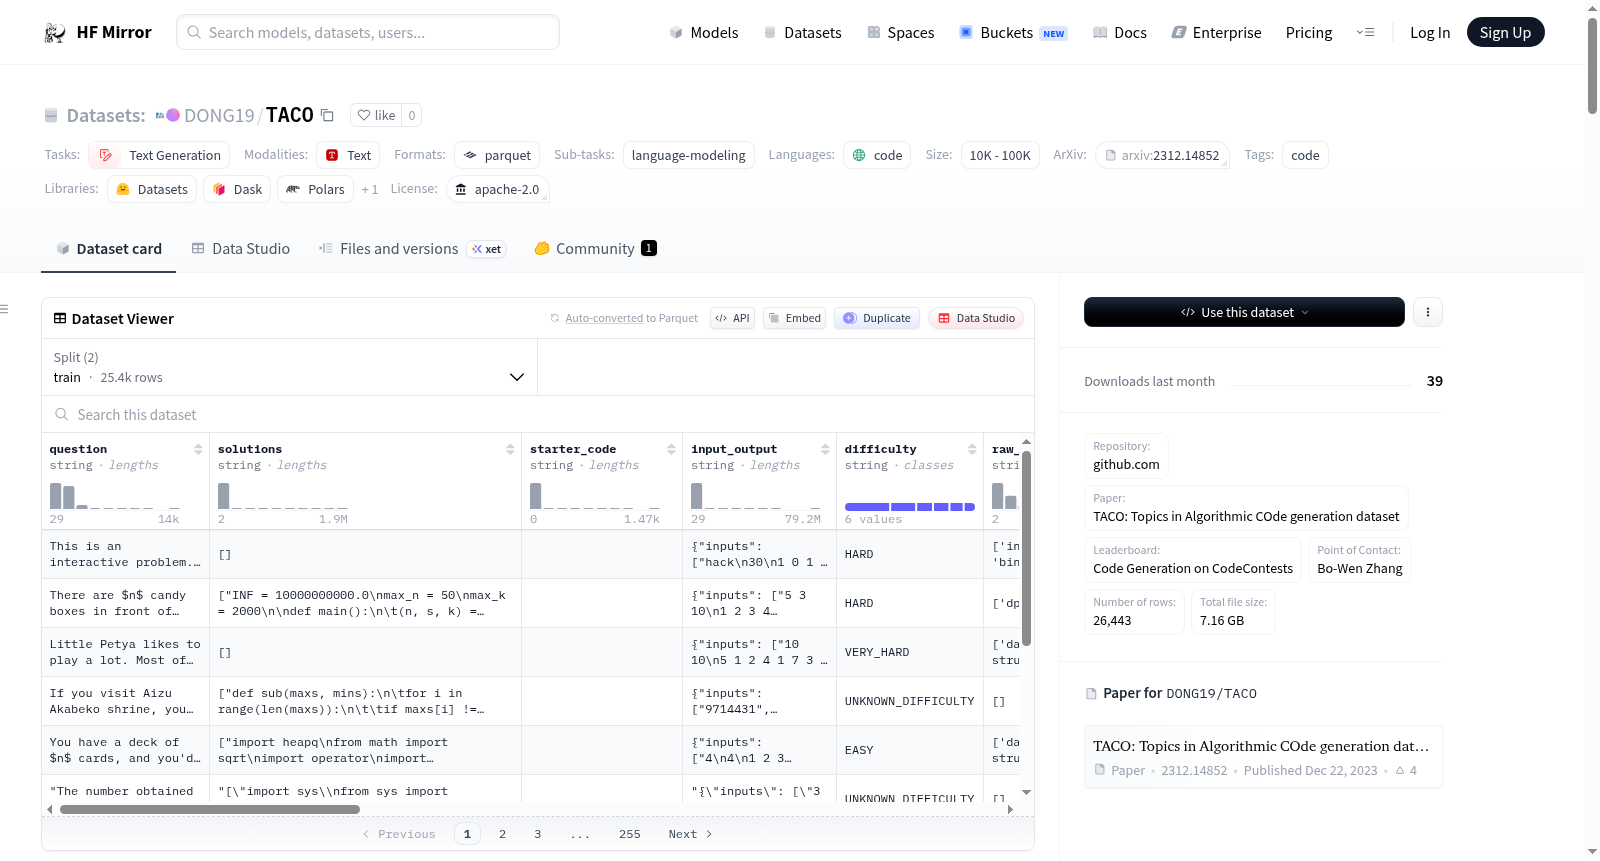
TACO数据集是一个用于代码生成的基准数据集,包含26443个编程问题。它可用于评估语言模型根据自然语言规范生成代码的能力。数据集包含英文问题描述、Python解决方案、测试用例及其输入输出、难度级别、问题主题、所需算法和编程技能类型等元数据。数据集结构包括训练集(25443个样本)和测试集(1000个样本)。数据来源于多个开放访问的编程问题分享网站,如Codeforces、CodeChef、LeetCode等,并遵循Apache 2.0许可证。
The TACO dataset is a benchmark for code generation with 26,443 programming problems. It can be used to evaluate the ability of language models to generate code from natural language specifications. The dataset includes problem descriptions in English, Python solutions, test cases with inputs and outputs, and metadata such as difficulty level, problem topics, required algorithms, and programming skill types. The dataset is structured into a training set (25,443 samples) and a test set (1,000 samples). It is sourced from various open-access programming problem-sharing sites like Codeforces, CodeChef, LeetCode, etc., and is available under an Apache 2.0 License.