HKUSTAudio/ISCSLP2026-CoT-TTS
收藏资源简介:
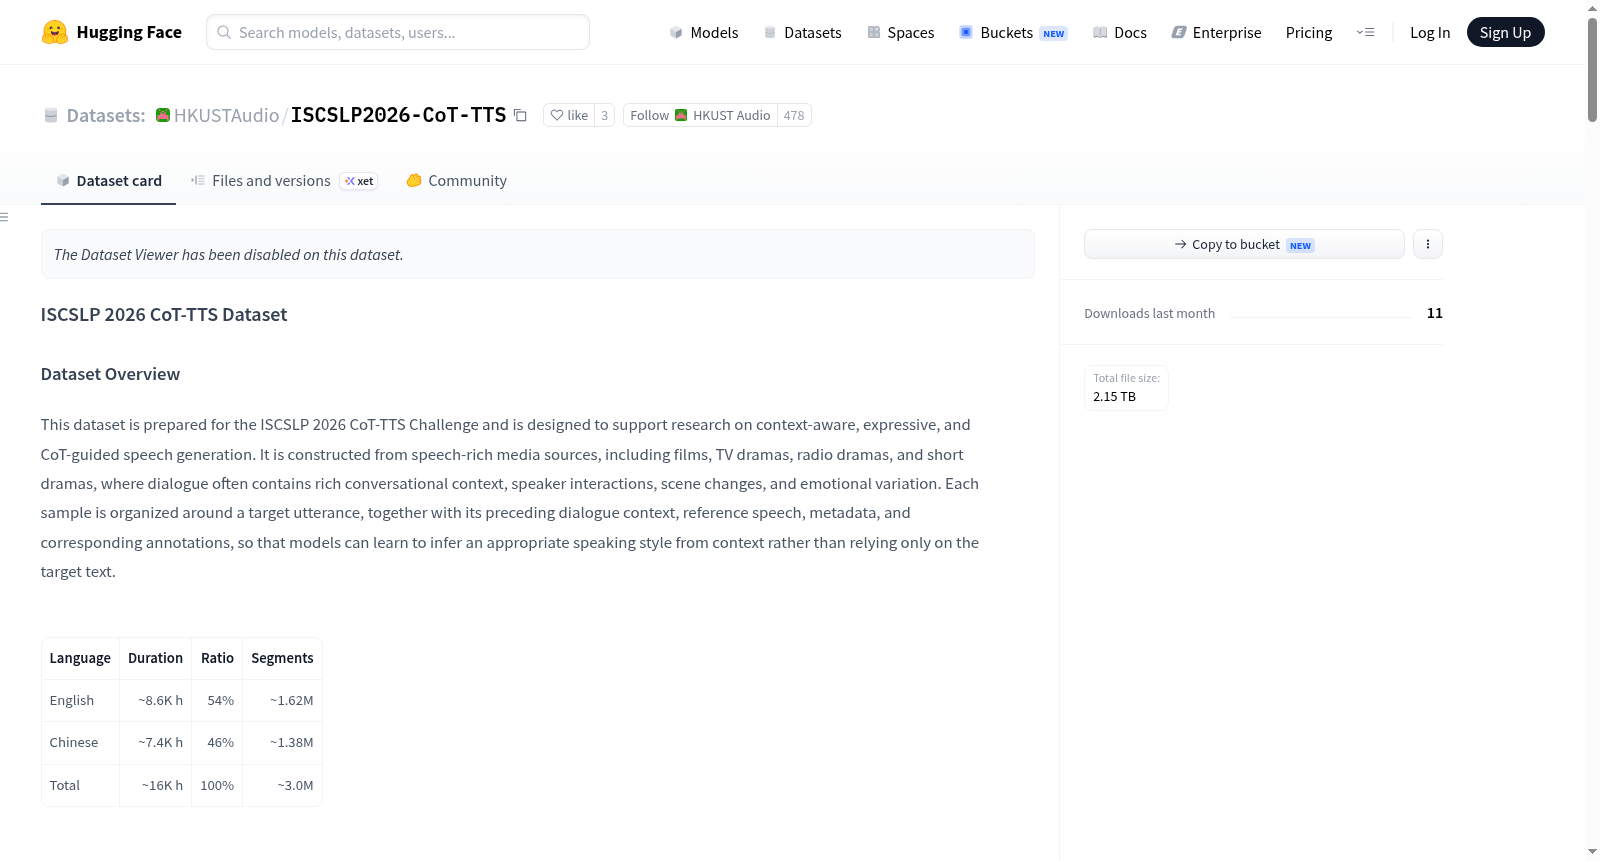
该数据集是为ISCSLP 2026 CoT-TTS挑战赛准备的,旨在支持上下文感知、表达性和思维链(CoT)引导的语音生成研究。数据来源于富含对话的媒体资源,包括电影、电视剧、广播剧和短剧,这些资源通常包含丰富的对话上下文、说话者互动、场景变化和情感变化。每个样本围绕一个目标话语组织,包括其前文对话上下文、参考语音、元数据和相应注释,使模型能够学习从上下文中推断合适的说话风格,而不仅仅依赖目标文本。数据集包含英语(约8.6K小时,54%,约1.62M片段)和中文(约7.4K小时,46%,约1.38M片段),总时长约16K小时,共约3.0M片段。音频文件以FLAC格式标准化,但保留了原始声学特性(如不同采样率、声道配置、响度水平、背景声音或环境噪声),以模拟真实声学条件,避免过度预处理假设。元数据和注释基于归一化和去噪的音频版本生成,以提高可靠性和准确性。
This dataset is prepared for the ISCSLP 2026 CoT-TTS Challenge, aiming to support research on context-aware, expressive, and Chain-of-Thought (CoT) guided speech generation. The data is sourced from dialogue-rich media resources including movies, TV series, radio dramas and short dramas, which typically contain abundant conversational context, speaker interactions, scene transitions and emotional shifts. Each sample is organized around a target utterance, comprising its preceding conversational context, reference speech, metadata and corresponding annotations, allowing models to learn to infer appropriate speaking styles from context rather than relying solely on the target text. The dataset includes English (approximately 8.6K hours, 54%, ~1.62M segments) and Chinese (approximately 7.4K hours, 46%, ~1.38M segments), with a total duration of around 16K hours and approximately 3.0M segments in total. Audio files are standardized in FLAC format, while original acoustic characteristics such as varying sampling rates, channel configurations, loudness levels, background sounds or ambient noise are retained to simulate real-world acoustic conditions and avoid over-preprocessing assumptions. Metadata and annotations are generated based on normalized and denoised audio versions to enhance reliability and accuracy.