jamalinu/maghreb-nlp-bridge
收藏资源简介:
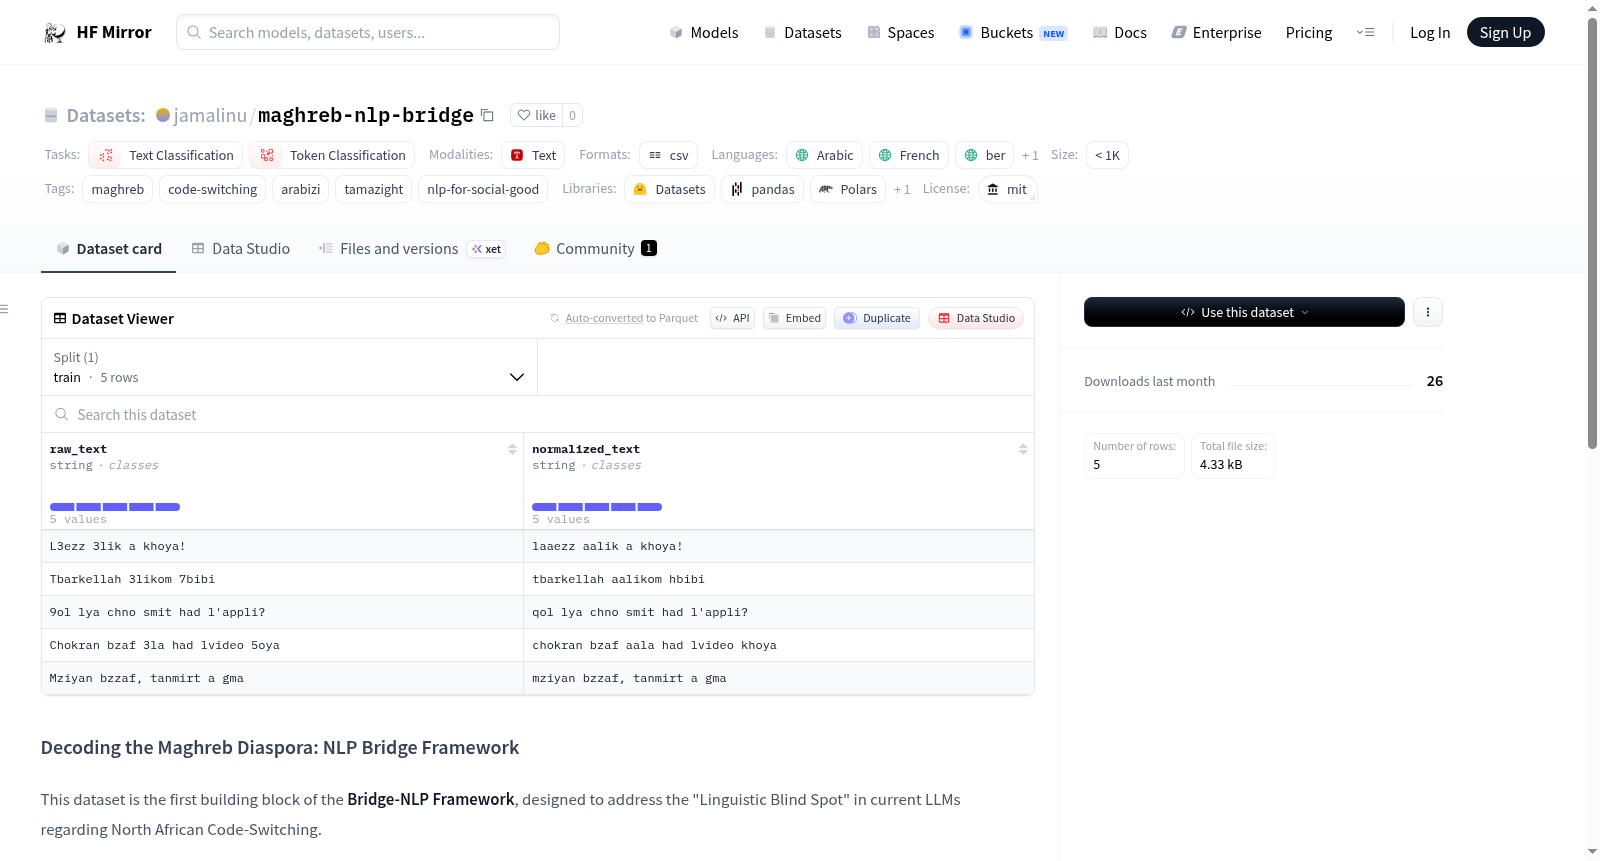
--- language: - ar - fr - ber - es license: mit task_categories: - text-classification - token-classification tags: - maghreb - code-switching - arabizi - tamazight - nlp-for-social-good pretty_name: Maghreb Diaspora NLP Bridge size_categories: - n<1K --- # Decoding the Maghreb Diaspora: NLP Bridge Framework This dataset is the first building block of the **Bridge-NLP Framework**, designed to address the "Linguistic Blind Spot" in current LLMs regarding North African Code-Switching. ## 📌 Project Context As described in my [Medium White Paper](https://medium.com/@jamalia/decoding-the-maghreb-diaspora-a-multilingual-nlp-framework-for-social-integration-66d9cf00b94d), this project aims to build empathetic educational tools for the Maghreb diaspora in Europe (Spain, France, Catalonia). ## 🛠 Features - **Raw Text**: Authentic samples of Maghreb Arabic (Darija), Tamazight, French, and Spanish mixed in Arabizi and Latin scripts. - **Normalized Text**: Processed text using my custom phonetic mapping to reduce tokenization inefficiency. ## 🚀 Vision The goal is to expand this into a robust corpus for: 1. **Linguistic Normalization**: Converting Arabizi to standard representations. 2. **Social Integration Tools**: Helping students and families navigate host-country languages through their native hybrid speech. ## 📬 Contact & Collaboration Developed by **Jamal** – Linguistic Engineer & NLP Specialist. I am looking for collaborators and datasets to scale this "Moonshot" for inclusive AI.
--- 语言: - 阿拉伯语(ar) - 法语(fr) - 柏柏尔语(ber) - 西班牙语(es) 许可证:MIT许可证 任务类别: - 文本分类 - Token分类 标签: - 马格里布(Maghreb) - 语码转换(Code-switching) - 阿拉伯拉丁化拼写(Arabizi) - 塔马齐格特语(Tamazight) - 面向社会公益的自然语言处理(NLP for Social Good) 美观名称:马格里布侨民NLP桥梁(Maghreb Diaspora NLP Bridge) 样本规模类别:n<1K --- # 解码马格里布侨民:NLP桥梁框架 本数据集是**Bridge-NLP框架**的首个核心组成模块,旨在解决当前大语言模型在北非语码转换场景下存在的“语言盲区”问题。 ## 📌 项目背景 正如我在Medium白皮书中所述(链接:https://medium.com/@jamalia/decoding-the-maghreb-diaspora-a-multilingual-nlp-framework-for-social-integration-66d9cf00b94d),本项目旨在为欧洲马格里布侨民(涵盖西班牙、法国与加泰罗尼亚地区)打造兼具共情性的教育辅助工具。 ## 🛠 数据集特性 - **原始文本**:包含马格里布阿拉伯语(达里贾方言,Darija)、塔马齐格特语、法语及西班牙语的真实语料,文本采用阿拉伯拉丁化拼写与拉丁字母混合书写形式。 - **标准化文本**:通过自定义语音映射规则处理后的文本,用于降低Token分词的效率损耗。 ## 🚀 项目愿景 本项目的最终目标是将其拓展为适用于以下场景的高质量语料库: 1. **语言标准化**:将阿拉伯拉丁化拼写转换为标准书面表达形式。 2. **社会融合工具**:帮助侨民学生与家庭依托自身的混合式母语体系,快速适配居住国的语言环境。 ## 📬 联系与合作 本数据集由**贾马尔(Jamal)**——语言工程师与自然语言处理专家——开发。 目前我正在寻求合作者与相关数据集,以推进这项面向包容性人工智能的“登月计划”。