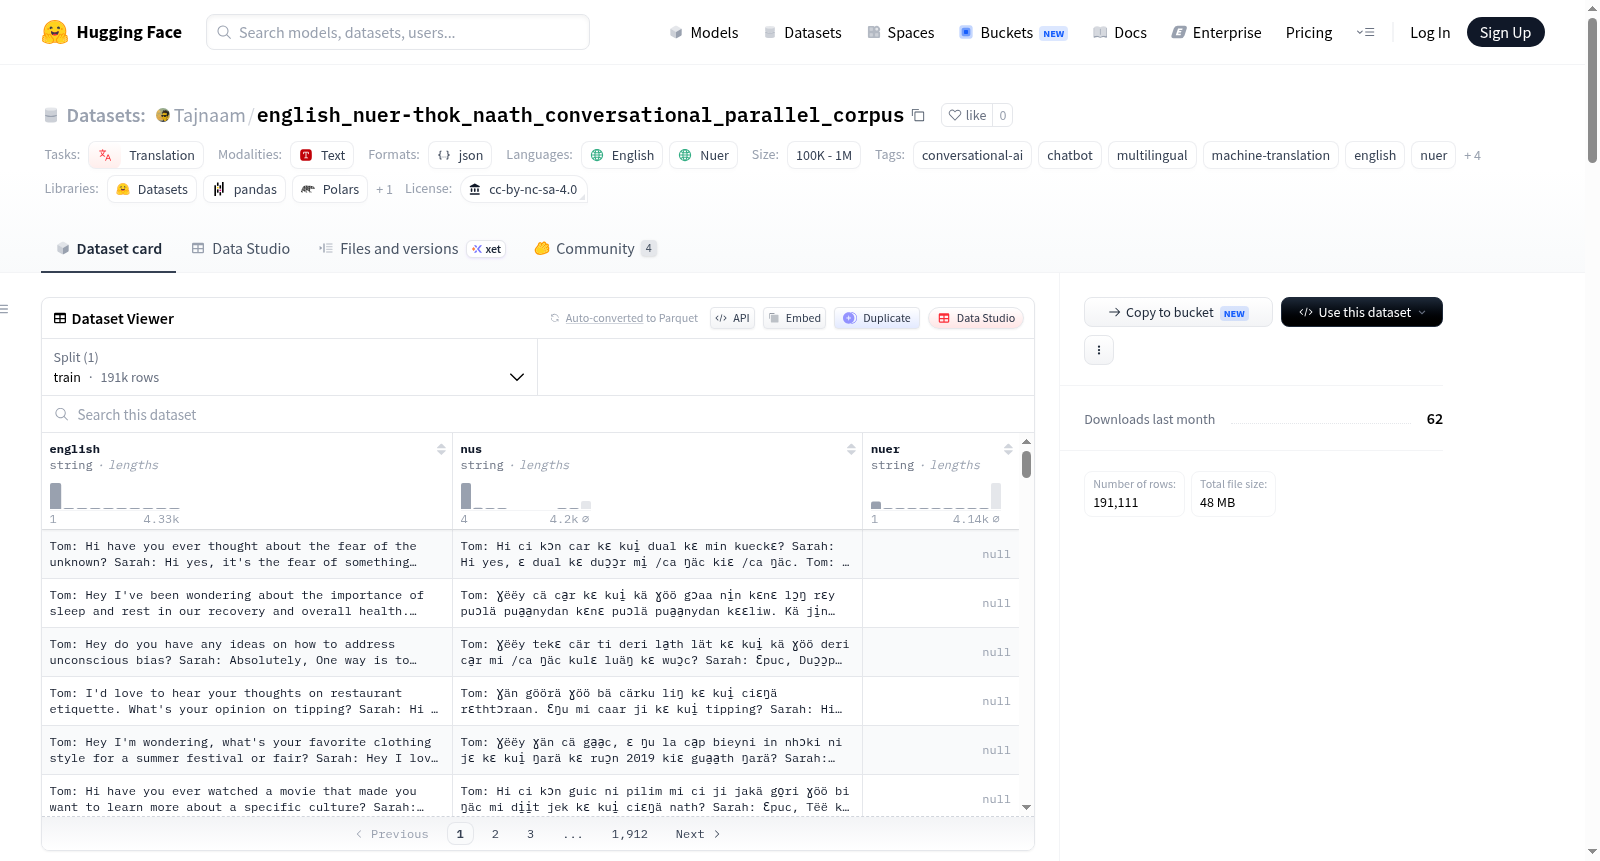
english_nuer-thok_naath_conversational_parallel_corpus
收藏资源简介:
English–Nuer (Thok Naath) Conversational Parallel Corpus 是一个双语平行语料库,包含英语和努尔语(Thok Naath)的对话句子对。该数据集旨在支持低资源非洲语言的研究,特别关注对话人工智能、机器翻译、多语言大语言模型和语言保护。作为为数不多的公开可用的努尔语对话数据集,它鼓励为代表性不足的语言开发包容性人工智能技术。语料库包含涵盖日常交流的对话文本对,例如问候、问答、日常对话、常见表达、非正式对话和社交互动。每条记录都包含对齐的英语和努尔语句子,适用于有监督的自然语言处理任务。该数据集适用于学术研究、教育目的、机器翻译、对话人工智能、聊天机器人开发(仅限研究)、大语言模型研究、低资源自然语言处理、语言保护和语言分析。但不得用于商业人工智能产品、商业聊天机器人服务、付费API、专有语言模型、商业翻译系统、以营利为目的出售或重新分发数据集,或任何未经作者书面许可的商业用途。数据集采用知识共享署名-非商业性使用-相同方式共享 4.0 国际许可协议。
English–Nuer (Thok Naath) Conversational Parallel Corpus is a bilingual parallel corpus containing conversational sentence pairs in English and Nuer (Thok Naath). This dataset aims to support research on low-resource African languages, with a particular focus on conversational artificial intelligence, machine translation, multilingual large language models, and language preservation. As one of the few publicly available Nuer conversational datasets, it encourages the development of inclusive artificial intelligence technologies for underrepresented languages. The corpus includes conversational text pairs covering daily communication scenarios such as greetings, question-and-answer exchanges, daily dialogues, common expressions, informal conversations, and social interactions. Each entry contains aligned English and Nuer sentences, which is suitable for supervised natural language processing tasks. This dataset can be used for academic research, educational purposes, machine translation, conversational AI, chatbot development (for research only), large language model research, low-resource natural language processing, language preservation, and linguistic analysis. However, it is prohibited to use the dataset for commercial AI products, commercial chatbot services, paid APIs, proprietary language models, commercial translation systems, selling or redistributing the dataset for profit, or any commercial use without the written permission of the authors. The dataset is licensed under the Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International Public License.
数据集概述
English–Nuer (Thok Naath) Conversational Parallel Corpus 是一个英-努尔语(Thok Naath)双语对话平行语料库,包含对齐的对话句子对。该数据集旨在支持低资源非洲语言的研究,重点关注对话式AI、机器翻译、多语言语言模型和语言保护。
语言
- 英语 (
en) - 努尔语 / Thok Naath (
nus)
数据集内容
该语料库涵盖日常交流中的对话文本对,包括:
- 问候语
- 问答
- 日常对话
- 常用表达
- 非正式对话
- 社交互动
每条记录包含对齐的英语和努尔语句子,适用于监督式自然语言处理任务。
预期用途
该数据集预期用于:
- 学术研究
- 教育用途
- 机器翻译
- 对话式AI
- 聊天机器人开发(仅限研究)
- 大型语言模型研究
- 低资源自然语言处理
- 语言保护
- 语言学分析
禁止用途
该数据集不得用于:
- 商业AI产品
- 商业聊天机器人服务
- 付费API
- 专有语言模型
- 商业翻译系统
- 出售或转售数据集以营利
- 未经作者书面许可的任何商业用途
如需商业使用,请通过Hugging Face仓库联系作者获取单独的商业许可。
许可协议
该数据集采用 Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International (CC BY-NC-SA 4.0) 协议。
- 允许:分享、复制、重新分发、改编、修改
- 条件:必须注明出处;禁止商业使用;衍生作品必须以相同协议分发
许可协议链接:https://creativecommons.org/licenses/by-nc-sa/4.0/
引用
若在研究中使用该数据集,请引用:
bibtex @dataset{tajnaam2026english_nuer_conversation, author = {Tajnaam}, title = {English–Nuer (Thok Naath) Conversational Parallel Corpus}, year = {2026}, publisher = {Hugging Face}, url = {https://huggingface.co/datasets/Tajnaam/english_nuer-thok_naath_conversational_parallel_corpus} }
伦理考量
该数据集旨在促进努尔语(Thok Naath)的数字保存和发展。鼓励用户以负责任和尊重努尔语社区的方式使用数据。
免责声明
该数据集按“原样”提供,不附任何形式的保证。作者不对数据集的误用承担责任。
联系
如有问题、合作、更正或商业许可查询,请通过Hugging Face仓库联系作者。