Hariprasad30/hdfs-logs-encoded-blocks
收藏资源简介:
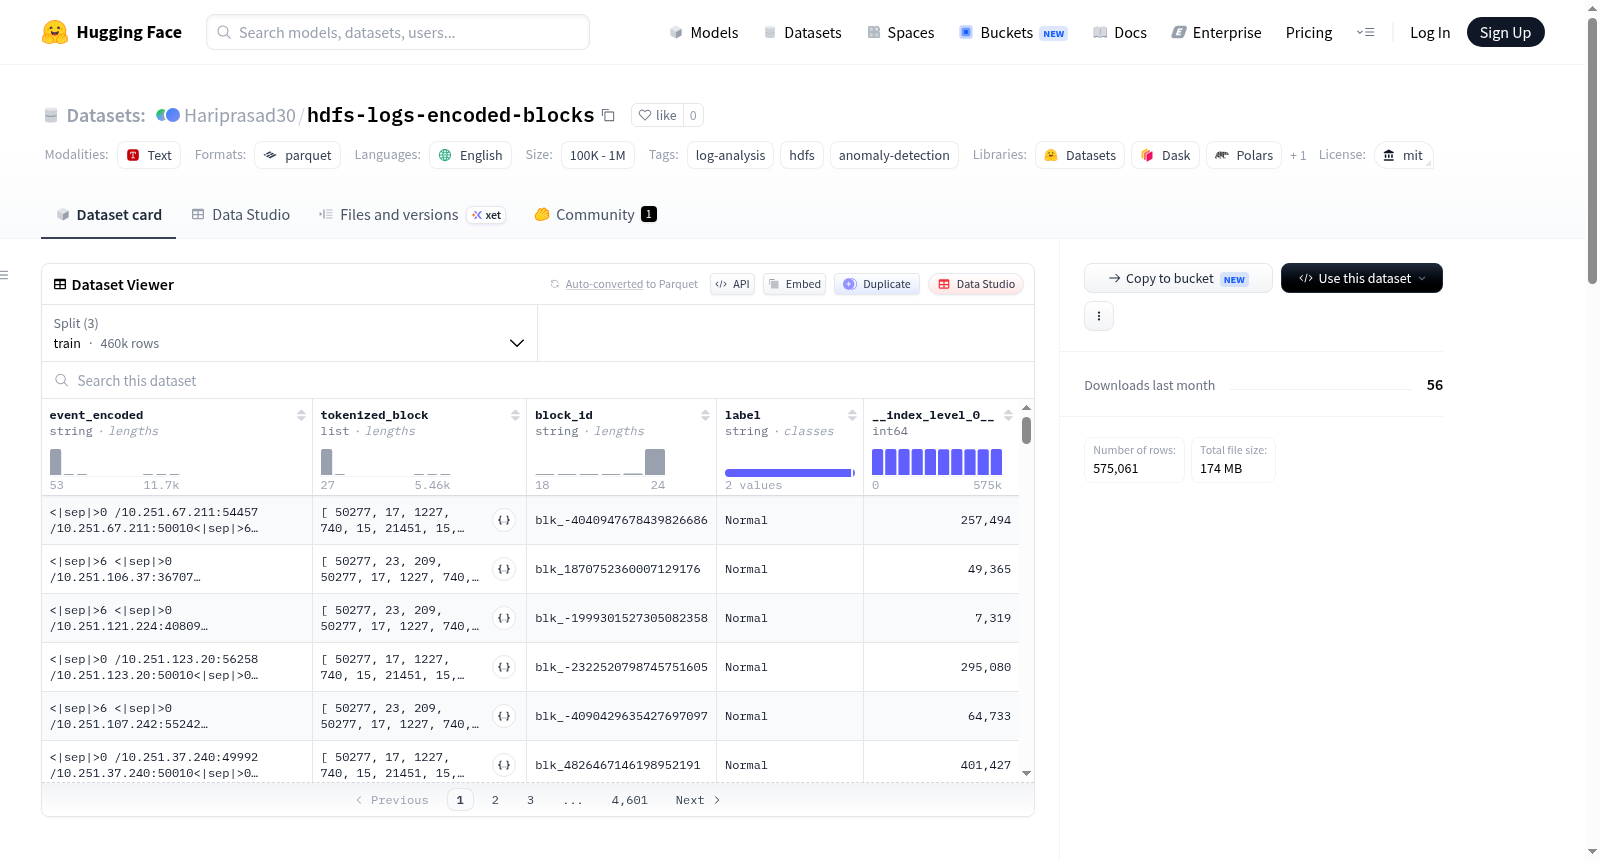
该数据集包含预处理过的HDFS日志序列,分为训练集、验证集和测试集,用于异常检测任务。数据集来源于Hadoop分布式文件系统(HDFS)的系统日志,每个序列代表一个日志消息块,标记为正常或异常。数据集使用Drain算法进行预处理,提取结构化字段并识别事件类型。数据字段包括block_id(唯一标识符)、event_encoded(预处理后的日志序列)、tokenized_block(用于训练的标记化日志序列)和label(分类标签,Normal或Anomaly)。数据分割为训练集(460,049序列,80%)、验证集(57,506序列,10%)和测试集(57,506序列,10%),并按标签字段进行了分层。数据集适用于训练日志异常检测模型、评估日志序列预测模型以及基准测试不同的日志异常检测方法。
This dataset contains preprocessed HDFS log sequences split into train, validation, and test sets for anomaly detection tasks. The dataset is derived from the HDFS log dataset, which contains system logs from a Hadoop Distributed File System (HDFS). Each sequence represents a block of log messages, labeled as either normal or anomalous. The dataset has been preprocessed using the Drain algorithm to extract structured fields and identify event types. Data fields include block_id (unique identifier), event_encoded (preprocessed log sequence), tokenized_block (tokenized log sequence for training), and label (classification label, Normal or Anomaly). The data splits are training set (460,049 sequences, 80%), validation set (57,506 sequences, 10%), and test set (57,506 sequences, 10%), stratified by the Label field. The dataset is designed for training log anomaly detection models, evaluating log sequence prediction models, and benchmarking different approaches to log-based anomaly detection.