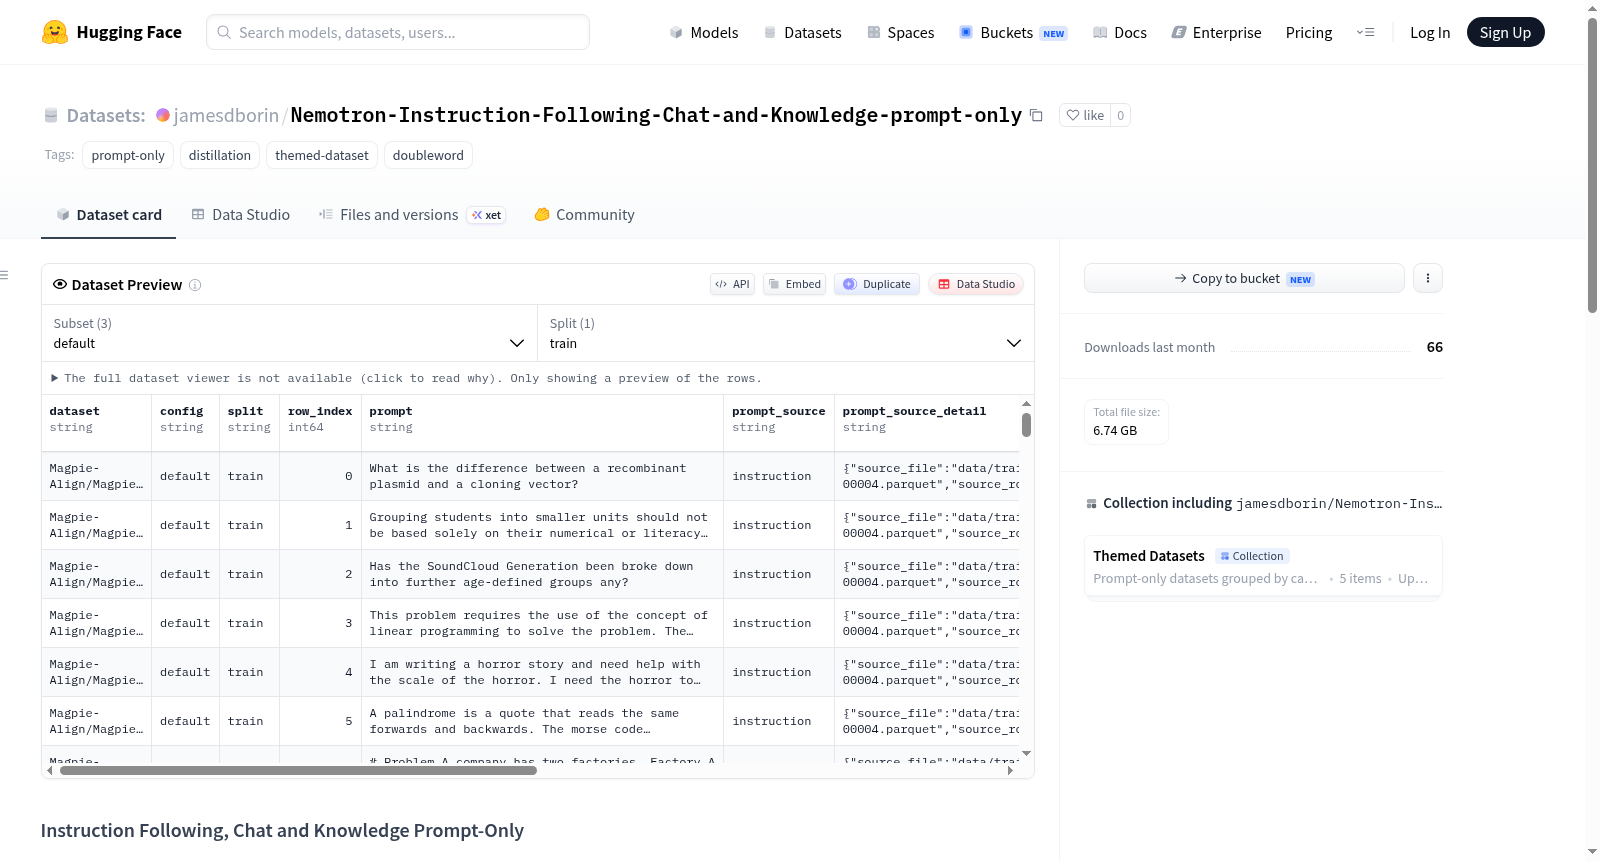
Nemotron-Instruction-Following-Chat-and-Knowledge-prompt-only
收藏资源简介:
该数据集名为 Instruction Following, Chat and Knowledge Prompt-Only,是一个专门为知识蒸馏实验设计的提示词(prompt-only)集合。它按照能力主题整合了来自多个开源数据集的提示词,旨在提供高质量的指令遵循、对话和知识相关的提示用于模型训练。数据集包含 2,235,051 个唯一的提示词,这些提示词是从总计 3,344,905 个原始数据行中经过严格去重后得到的(移除了 1,109,854 个完全重复项)。去重过程基于规范化处理的 `system_prompt`、`prompt`、`tools` 和 `schema_str` 字段,并保留了首次出现的数据行。数据集保留了来源数据集的规范列结构,并新增了 `source_repo_id` 字段以追溯数据来源。所有原始数据集的许可证和使用条款在此数据集中继续适用。数据集包含三个配置:1) default 配置包含压缩的 CSV 格式训练数据。2) doubleword 配置提供了模型无关的 JSONL 格式请求数据,分为 small (10万)、medium (50万) 和 large (100万) 三个规模,可直接用于相关工具的准备流程。3) deepseek-v4 配置包含了由 DeepSeek-V4-Flash 模型生成的完整对话数据,并已转换为适用于 TorchSpec 训练的格式,分为 small (10万) 和 medium (50万) 两个规模的对话集合,每条数据包含 `id` 和 `conversations` 列表。该数据集主要适用于大语言模型的指令微调、对话生成能力蒸馏以及相关研究任务。
The dataset named Instruction Following, Chat and Knowledge Prompt-Only is a prompt-only collection specifically designed for knowledge distillation experiments. It integrates prompts from multiple open-source datasets according to capability themes, aiming to provide high-quality instruction following, chat, and knowledge-related prompts for model training. The dataset contains 2,235,051 unique prompts, obtained after rigorous deduplication from a total of 3,344,905 original data rows (removing 1,109,854 exact duplicates). The deduplication process is based on the normalized fields of `system_prompt`, `prompt`, `tools`, and `schema_str`, and retains the first occurrence of each data row. The dataset preserves the canonical column structure of the source datasets and adds a new `source_repo_id` field to trace data provenance. All licenses and terms of use from the original datasets continue to apply. The dataset includes three configurations: 1) default configuration contains compressed CSV format training data. 2) doubleword configuration provides model-agnostic JSONL format request data in three sizes: small (100k), medium (500k), and large (1M), which can be directly used in the preparation pipeline of related tools. 3) deepseek-v4 configuration contains complete conversation data generated by the DeepSeek-V4-Flash model, converted to a format suitable for TorchSpec training, with two sizes: small (100k) and medium (500k) conversation sets, each containing `id` and `conversations` lists. This dataset is mainly applicable to instruction fine-tuning, dialogue generation capability distillation, and related research tasks for large language models.
数据集概述:Instruction Following, Chat and Knowledge Prompt-Only
该数据集是一个用于蒸馏实验的“仅提示词”数据集,整合了来自多个来源、按能力主题分类的提示词数据。
基本信息
- 名称: Instruction Following, Chat and Knowledge Prompt-Only
- 规模: 包含 2,235,051 个独特提示词(原始数据共 3,344,905 行,去除了 1,109,854 个精确的规范重复项)。
- 去重逻辑: 基于规范化后的
system_prompt、prompt、tools和schema_str字段进行去重,保留清单顺序中的第一行。 - 许可: 原始来源数据的许可证和使用条件继续适用。
数据内容
- 每一行保留了原始数据中的规范提示词提取列,并增加了
source_repo_id字段以标识数据来源。 - 数据集包含多个配置(config):
default: 包含去重后的全部提示词数据,文件格式为 CSV.GZ。doubleword: 模型无关的 JSONL 格式请求,用于 Doubleword 平台。分为 small(100,000)、medium(500,000)和 large(1,000,000)三个子集。deepseek-v4: 包含由deepseek-ai/DeepSeek-V4-Flash模型生成的完整对话,已转换为适用于 TorchSpec 训练的格式。分为 small(100,000)和 medium(500,000)两个子集。每条数据包含id和conversations列表(包含原始请求和助手回复)。
数据来源
该数据集由以下 14 个“仅提示词”子数据集合并而成:
- jamesdborin/Magpie-Llama-3.1-Pro-300K-Filtered-prompt-only (300,000 原始提示词)
- jamesdborin/UltraChat-200K-prompt-only (207,865 原始提示词)
- jamesdborin/Nemotron-SFT-Instruction-Following-Chat-v2-prompt-only (1,997,441 原始提示词)
- jamesdborin/Nemotron-SFT-Instruction-Following-Chat-v3-prompt-only (787,952 原始提示词)
- jamesdborin/Nemotron-RL-Instruction-Following-Adversarial-v1-prompt-only (1,000 原始提示词)
- jamesdborin/Nemotron-RL-Instruction-Following-Free-Form-Formatting-v1-prompt-only (9,037 原始提示词)
- jamesdborin/Nemotron-RL-Instruction-Following-Citation-Formatting-v1-prompt-only (9,540 原始提示词)
- jamesdborin/Nemotron-RL-Instruction-Following-MultiTurnChat-v1-prompt-only (2,011 原始提示词)
- jamesdborin/Nemotron-RL-Identity-Following-v1-prompt-only (21,660 原始提示词)
- jamesdborin/Nemotron-RL-CFBench-v1-prompt-only (1,121 原始提示词)
- jamesdborin/Nemotron-RL-SysBench-v1-prompt-only (1,010 原始提示词)
- jamesdborin/Nemotron-RL-Multichallenge-v1-prompt-only (2,118 原始提示词)
- jamesdborin/Nemotron-RL-InverseIFEval-v1-prompt-only (1,000 原始提示词)
- jamesdborin/Nemotron-RL-QA-Abstention-v1-prompt-only (3,150 原始提示词)
注意: 数据集中包含一份 merge_report.json 文件,可查看每个来源的解析、保留、重复和输出大小的详细计数。