Jzuluaga/atco2_corpus_1h
收藏资源简介:
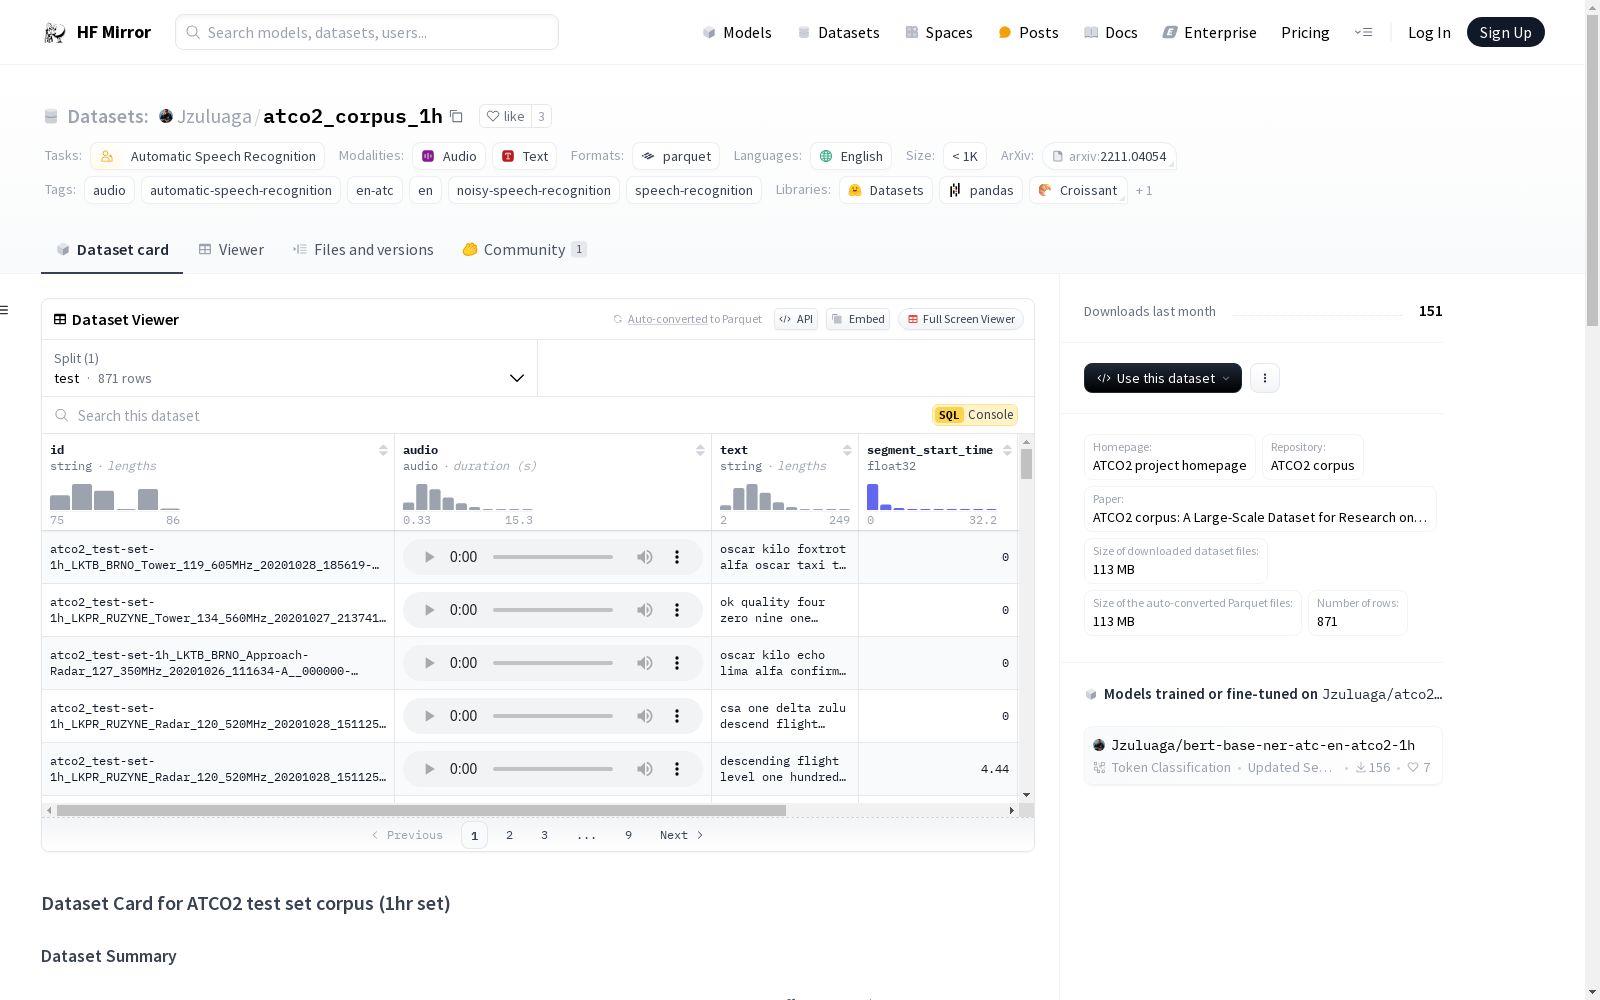
ATCO2测试集语料库(1小时集)是一个用于自动语音识别任务的数据集,包含音频和文本数据。数据集的结构包括id、audio、text、segment_start_time、segment_end_time和duration等字段。数据集的语言为英语,且为单语种。数据集来源于ATCO2项目,该项目旨在收集、组织和预处理来自空域的空中交通控制(语音通信)数据。数据集包含5000+小时的伪转录语音数据和4小时的转录语音数据,其中4小时的数据是免费样本。数据集还提供了相关的论文和模型链接。
The ATCO2 test set corpus (1-hour subset) is a dataset for automatic speech recognition (ASR) tasks, containing both audio and text data. Its structure includes fields such as id, audio, text, segment_start_time, segment_end_time, and duration. This is a monolingual English dataset. It is derived from the ATCO2 project, which aims to collect, organize and preprocess air traffic control (voice communication) data from airspace. The overall dataset of the ATCO2 project includes over 5,000 hours of pseudo-transcribed speech data and 4 hours of manually transcribed speech data, among which the 4-hour subset is the free sample. Relevant research papers and model links are also provided for this dataset.
数据集概述
数据集名称
- ATCO2 test set corpus (1hr set)
数据集特征
- id: 字符串类型,录音标识符。
- audio: 音频类型,采样率为16000。
- text: 字符串类型,文件的转录文本。
- segment_start_time: 浮点数类型,段开始时间。
- segment_end_time: 浮点数类型,段结束时间。
- duration: 浮点数类型,录音时长,计算方式为segment_end_time - segment_start_time。
数据集结构
- 测试集: 包含871个样本,总大小为113872168.0字节。
语言和标签
- 语言: 英语
- 标签: 音频、自动语音识别、英语、噪声语音识别、语音识别
任务支持
- 自动语音识别
许可证信息
- 许可证详情请参阅文件ATCO2-ASRdataset-v1_beta - End-User Data Agreement。
引用信息
- 引用该数据集的文献包括:
- Zuluaga-Gomez, Juan et al. "How Does Pre-trained Wav2Vec2. 0 Perform on Domain Shifted ASR? An Extensive Benchmark on Air Traffic Control Communications."
- Zuluaga-Gomez, Juan et al. "BERTraffic: BERT-based Joint Speaker Role and Speaker Change Detection for Air Traffic Control Communications."
- Zuluaga-Gomez, Juan et al. "ATCO2 corpus: A Large-Scale Dataset for Research on Automatic Speech Recognition and Natural Language Understanding of Air Traffic Control Communications."