reap-calibration-data-v1
收藏资源简介:
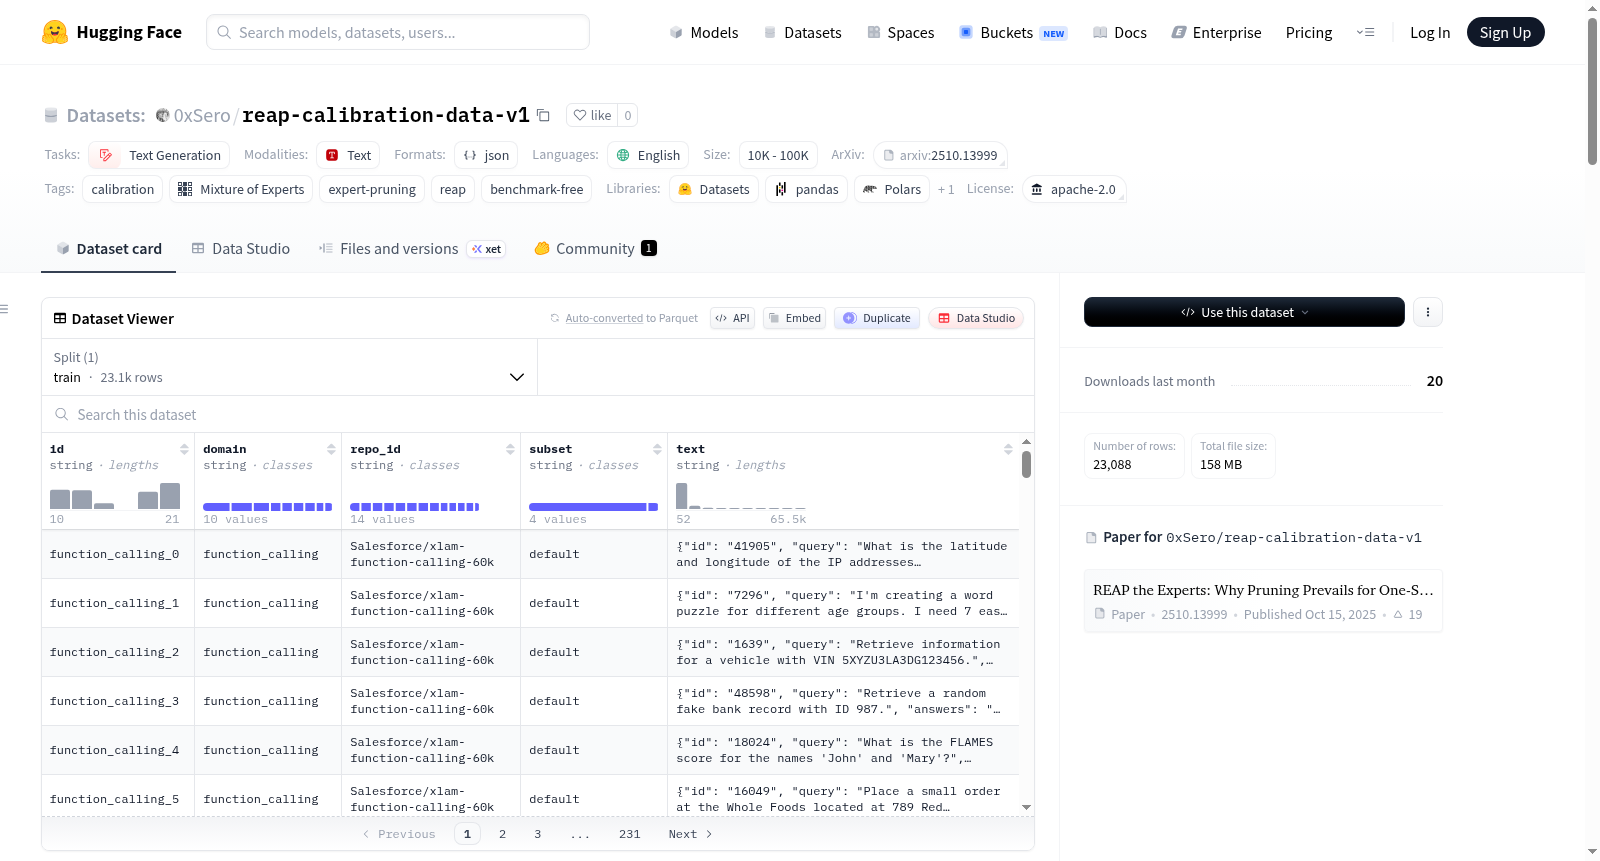
REAP校准数据集v1是一个专为REAP(路由增强激活剪枝)设计的无基准校准数据集,用于混合专家(Mixture-of-Experts)语言模型的剪枝决策。该数据集通过提供多样化的输入,观察专家路由统计信息,从而确定哪些专家可以安全移除。数据集包含23,088个样本,覆盖10个领域,主要集中在编码和工具使用工作负载上。为确保剪枝决策不受基准特定模式的影响,数据集排除了所有常见评估基准。数据集采用JSONL格式,包含id、domain、repo_id、subset和text等字段。适用于≥110B参数的模型时,每个样本作为独立序列处理,最大序列长度为16,384个标记;对于<110B参数的模型,建议将多个样本打包以填充2,048个标记的序列。数据集已用于多个模型的校准,如Qwen3.5-122B-A10B-REAP系列。
REAP Calibration Dataset v1 is a benchmark-free calibration dataset specifically designed for REAP (Route-Augmented Activation Pruning), used for pruning decisions of Mixture-of-Experts (MoE) language models. This dataset provides diverse inputs to observe expert routing statistics, thereby identifying which experts can be safely pruned. The dataset contains 23,088 samples covering 10 domains, with a primary focus on coding and tool-use workloads. To ensure pruning decisions are not biased by benchmark-specific patterns, this dataset excludes all common evaluation benchmarks. The dataset is stored in JSONL format, with fields including id, domain, repo_id, subset, and text. For models with ≥110B parameters, each sample is processed as an independent sequence, with a maximum sequence length of 16,384 tokens; for models with <110B parameters, it is recommended to pack multiple samples to fill sequences of 2,048 tokens. This dataset has been used for calibration of multiple models, such as the Qwen3.5-122B-A10B-REAP series.