repair-sbn
收藏资源简介:
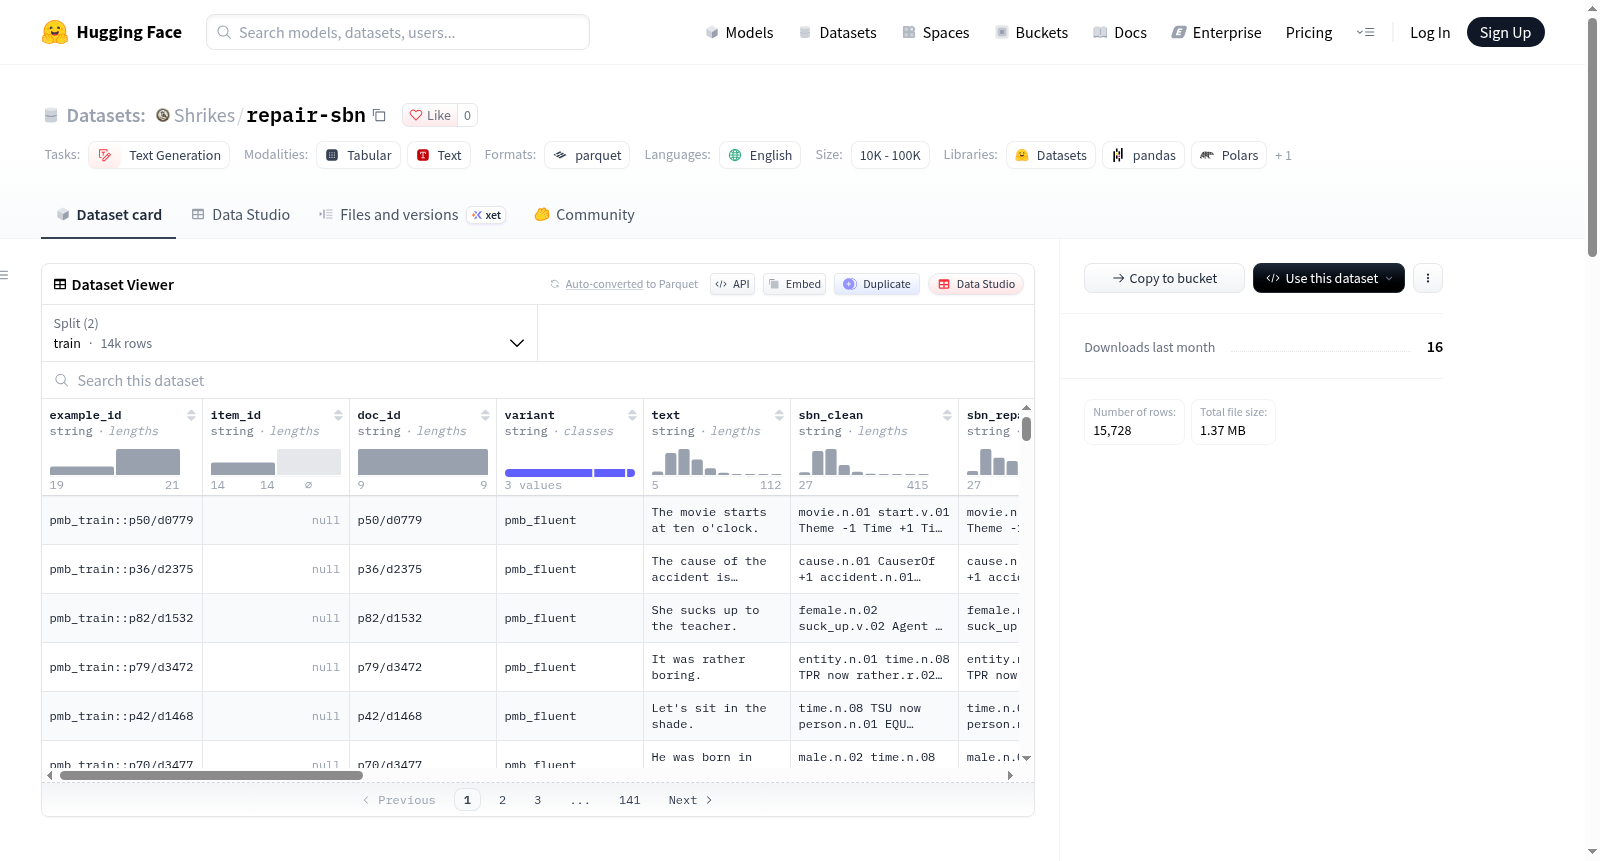
RepairSBN 是一个英文文本生成数据集,任务类别为 text-generation,语言为 en,默认配置为 default,包含 train 和 validation 两个 split,对应数据文件 data/train.parquet 与 data/validation.parquet。数据集包含项目使用的英文 PMB 5.1.0 train-gold 和 standard-dev 数据,以及合成的 replacement self-repair (RSR) 变体。为 hard-negative evaluation 保留的 66 篇文档不在任何组件中。 数据规模与变体:train 共 14,022 行,validation 共 1,706 行。变体包括:pmb_fluent,train 9,486、validation 1,194,C2 目标为 sbn_clean,C3 目标为 sbn_repair(= clean);rsr_base,train 3,489、validation 390,C2 目标为 sbn_clean,C3 目标为 sbn_repair;rsr_editing_expression,train 1,047、validation 122,C2 目标为 sbn_clean,C3 目标为 sbn_repair。validation 是项目 dev split,遵循 PMB 源划分;测试数据将在构建并接受后单独添加。C1 选择 fluent rows 和 sbn_clean;C2 选择所有行和 sbn_clean;C3 选择所有行和 sbn_repair。组装时行顺序为 PMB 源顺序后接增强 RSR 源顺序,不进行 shuffle,也不引入条件特定副本。 字段与标识:Parquet 使用与 train 相同的 20 列 schema 和空值约定。editing_expression 在 marked variants 中包含 I mean、no、no wait 或 actually,其他位置为 null。interregnum 不是数据集字段。example_id 标识 surface variant;item_id 链接同一 RSR item 的 base 与 marked 版本。marked variants 是 additive 的,所有 base RSR 行保留。train 中追加 1,047 个 marked 版本且 SBN 目标不变,其中包括 482 个无标记时被标记为文本歧义的行,以及从剩余 repair-type pools 按比例抽样的 565 行。dev 的 1,706 行由 1,194 个 fluent PMB standard-dev documents、390 个 base RSR 行和 122 个额外 marked 行构成;marked dev 行覆盖 122 个已识别的 multiple-reading items,没有随机补充。 构建与验收:train Parquet 和 manifest.json 由 build.py 本地生成。validation.manifest.json 记录 development assembly stage;validation.acceptance.json 记录同一 Parquet checksum 后续通过的 acceptance。未上传 TSV 源或人工标签。本地开发构建需在 repository root 的 repairsbn 环境中运行 python -m repair_data_gen.training_dataset.build_dev,写入 data/validation.parquet 和 validation.manifest.json,并保留现有 train build。该开发构建已通过本地验收;建议使用 Hub commit revision 固定已发布快照用于实验。开发验收需运行 python -m repair_data_gen.training_dataset.validate_dev --tokenizer-root PATH;PATH 包含 2B/、9B/、27B/ 的 tokenizer-only 下载,使用 model/smoke_test/revisions.json 中的模型 revision;使用 hf download 的 --revision 和重复 --include 获取 tokenizer*、chat_template*、vocab.json、merges.txt,并保留 .cache/huggingface/ 元数据。验证器离线加载这些文件并检查记录的 commit。结果位于 ../splits/dev/analysis/unified_validation/,包括 summary.json、逐行 graph checks 和逐例 token lengths。build manifest 记录 assembly;acceptance report 记录后续检查。所有 1,706 行通过 source、schema、identity 和 graph 检查;所有 512 个 RSR 行通过 withdrawal、untouched-content 和 new-WordNet-concept 检查;与 train 的 document 和 exact-input 重叠为零;122 个 marked pair 精确恢复其 base。早期批准的 surface warning 保留;context near-duplicate 检查按现有政策暂缓。对三个固定 tokenizer,最大完整序列长度为 219;没有样本超过设计中的 1,024-token 训练限制或 512-token 生成预算。审计使用设计中的共享 neutral instruction、pilot 的 instruction/newline/text 格式、Qwen 的 chat template 和 enable_thinking=False;检查 assistant boundaries 和 supervised EOS。正式 trainer 必须使用该审计格式;smoke-test instruction 是条件特定的,不是正式 instruction。 限制:RSR 输入是合成的,基于短篇书面 PMB 文本。train 歧义标签为启发式;dev 标签还记录已确认的 alternative readings。大多数 train repair types 通过抽样审计;train edge-label repairs 和所有选定的 dev base repairs 经过逐项复核。同一 item 的 marked 与 base variants 是同一语义示例的 surface variants,不是独立观测。
RepairSBN is an English text-generation dataset. Its task category is text-generation, language is en, default configuration is default, and it contains train and validation splits with files data/train.parquet and data/validation.parquet. It includes the English PMB 5.1.0 train-gold and standard-dev data used by the project, plus synthetic replacement self-repair (RSR) variants. The 66 documents reserved for hard-negative evaluation are not included in any component. Data size and variants: train has 14,022 rows and validation has 1,706 rows. Variants include: pmb_fluent, with 9,486 train and 1,194 validation rows, C2 target sbn_clean, C3 target sbn_repair (= clean); rsr_base, with 3,489 train and 390 validation rows, C2 target sbn_clean, C3 target sbn_repair; rsr_editing_expression, with 1,047 train and 122 validation rows, C2 target sbn_clean, C3 target sbn_repair. Validation is the project dev split, following the PMB source split; test data will be added separately after construction and acceptance. C1 selects fluent rows and sbn_clean; C2 selects all rows and sbn_clean; C3 selects all rows and sbn_repair. During assembly, row order is PMB source order followed by augmented RSR source order, without shuffle and without condition-specific duplicates. Fields and identifiers: Parquet uses the same 20-column schema and null conventions as train. editing_expression in marked variants contains I mean, no, no wait, or actually, and is null elsewhere. interregnum is not a dataset field. example_id identifies the surface variant; item_id links base and marked versions of the same RSR item. Marked variants are additive, and all base RSR rows are retained. In train, 1,047 marked versions are appended with unchanged SBN targets, including 482 rows marked as text ambiguity when unmarked, and 565 rows sampled proportionally from remaining repair-type pools. Devs 1,706 rows consist of 1,194 fluent PMB standard-dev documents, 390 base RSR rows, and 122 additional marked rows; marked dev rows cover 122 identified multiple-reading items with no random supplementation. Construction and acceptance: train Parquet and manifest.json are locally generated by build.py. validation.manifest.json records the development assembly stage; validation.acceptance.json records later acceptance of the same Parquet checksum. No TSV sources or human labels are uploaded. The local development build should be run in the repairsbn environment at repository root with python -m repair_data_gen.training_dataset.build_dev, writing data/validation.parquet and validation.manifest.json while preserving the existing train build. This development build has passed local acceptance; using a Hub commit revision to pin the released snapshot for experiments is recommended. Development acceptance requires running python -m repair_data_gen.training_dataset.validate_dev --tokenizer-root PATH; PATH contains tokenizer-only downloads for 2B/, 9B/, 27B/ using model revisions in model/smoke_test/revisions.json; use hf download --revision and repeated --include to fetch tokenizer*, chat_template*, vocab.json, merges.txt, and retain .cache/huggingface/ metadata. The validator loads these files offline and checks the recorded commit. Results are in ../splits/dev/analysis/unified_validation/, including summary.json, per-row graph checks, and per-example token lengths. The build manifest records assembly; the acceptance report records subsequent checks. All 1,706 rows passed source, schema, identity, and graph checks; all 512 RSR rows passed withdrawal, untouched-content, and new-WordNet-concept checks; document and exact-input overlap with train is zero; 122 marked pairs exactly restore their bases. Previously approved surface warnings are retained; context near-duplicate checks are deferred according to existing policy. For the three fixed tokenizers, the maximum full sequence length is 219; no sample exceeds the designed 1,024-token training limit or 512-token generation budget. Auditing uses the designed shared neutral instruction, the pilots instruction/newline/text format, Qwens chat template, and enable_thinking=False; assistant boundaries and supervised EOS are checked. The formal trainer must use this audit format; the smoke-test instruction is condition-specific and is not the formal instruction. Limitations: RSR inputs are synthetic and based on short written PMB text. Train ambiguity labels are heuristic; dev labels also record confirmed alternative readings. Most train repair types are audited by sampling; train edge-label repairs and all selected dev base repairs were reviewed item by item. Marked and base variants of the same item are surface variants of the same semantic example, not independent observations.
RepairSBN 数据集总结
数据集概览
- 名称:RepairSBN
- 语言:英语
- 任务类别:文本生成
- 配置:default,默认配置
- 训练集文件绝对地址:https://huggingface.co/datasets/Shrikes/repair-sbn/blob/main/data/train.parquet
- 验证集文件绝对地址:https://huggingface.co/datasets/Shrikes/repair-sbn/blob/main/data/validation.parquet
- 内容:英语 PMB 5.1.0 train-gold 与 standard-dev 数据,以及项目使用的 synthetic replacement self-repair(RSR)变体。
- 用于 hard-negative evaluation 的 66 篇文档保留但不包含在任何组件中。
数据规模与变体
| variant | train | validation | C2 目标 | C3 目标 |
|---|---|---|---|---|
pmb_fluent |
9,486 | 1,194 | sbn_clean |
sbn_repair(= clean) |
rsr_base |
3,489 | 390 | sbn_clean |
sbn_repair |
rsr_editing_expression |
1,047 | 122 | sbn_clean |
sbn_repair |
| total | 14,022 | 1,706 |
validation是项目的 dev split,遵循 PMB 的源分区。- 测试数据将在构建并接受后单独添加。
字段与标识
editing_expression:在 marked variants 中包含I mean、no、no wait或actually,其他位置为空。interregnum:不是数据集字段。example_id:标识 surface variant。item_id:链接一个 RSR item 的 base 版本与 marked 版本。
构建与拆分规则
- marked variants 是 additive;所有 base RSR 行均保留。
- 在 train 中,1,047 个 marked 版本被追加,且 SBN targets 不变。
- 上述 1,047 个 marked 版本包含 482 个被标记为无标记时文本歧义的行,以及 565 个从剩余 repair-type pools 中按比例采样的行。
- Train Parquet 与
manifest.json由build.py本地生成。 validation.manifest.json记录开发装配阶段;validation.acceptance.json记录同一 Parquet checksum 的后续通过 acceptance。- 没有上传 TSV 来源或人工标签。
- C1 选择 fluent rows 与
sbn_clean。 - C2 选择所有 rows 与
sbn_clean。 - C3 选择所有 rows 与
sbn_repair。 - 行顺序为 PMB source order 后接 augmented RSR source order。
- 装配期间不引入 shuffle 或 condition-specific copies。
本地开发构建
- 在
repairsbn环境从仓库根运行:
bash python -m repair_data_gen.training_dataset.build_dev
- 该命令写入验证 Parquet 文件与
validation.manifest.json,并保留现有训练构建。 - 1,706 个开发行包含 1,194 个 fluent PMB standard-dev 文档、390 个 base RSR 行与 122 个附加 marked 行。
- 该 Parquet 使用与 train 相同的 20 列 schema 和 null 约定。
- marked dev rows 覆盖 122 个已识别的 multiple-reading items,没有 random top-up。
- 开发构建已通过本地 acceptance。
- 使用 Hub commit revision 固定实验所用的精确已发布快照。
开发验收
- 在
repairsbn环境从仓库根运行:
bash python -m repair_data_gen.training_dataset.validate_dev --tokenizer-root PATH
PATH包含2B、9B、27B的 tokenizer-only 下载,并使用模型修订记录文件中的模型 revisions。- 使用
hf download的--revision与重复--include选项获取tokenizer*、chat_template*、vocab.json和merges.txt;保留 Hugging Face 缓存元数据。 - validator 离线加载这些文件并检查其记录的 commits。
- 验收结果包括
summary.json、逐行 graph checks 与逐示例 token lengths。 - build manifest 记录 assembly;acceptance report 记录后续检查。
- 所有 1,706 行通过 source、schema、identity 与 graph checks。
- 所有 512 个 RSR 行通过 withdrawal、untouched-content 与 new-WordNet-concept checks。
- 与 train 的文档重叠和精确输入重叠均为零。
- 122 个 marked pairs 精确恢复其 bases。
- 保留先前批准的 surface warning;context near-duplicate checks 按现有政策继续推迟。
- 对三个 pinned tokenizers,最大完整序列长度为 219;没有示例超过设计的 1,024-token 训练限制或 512-token 生成预算。
- 审计使用 design 的 shared neutral instruction、pilot 的 instruction/newline/text formatting、Qwen 的 chat template 和
enable_thinking=False。 - 检查 assistant boundaries 与 supervised EOS。
- 正式 trainer 必须使用该审计格式;smoke-test instruction 是 condition-specific,不是 formal instruction。
限制
- RSR 输入是 synthetic,并基于短书面 PMB 文本。
- Train ambiguity labels 是 heuristic;dev labels 也记录 confirmed alternative readings。
- 大多数 train repair types 通过采样审计;train edge-label repairs 与所有 selected dev base repairs 被单独审查。
- 一个 item 的 marked 与 base variants 是同一 semantic example 的 surface variants,不是独立观察。