saillab/alpaca_chinesetraditional_taco
收藏资源简介:
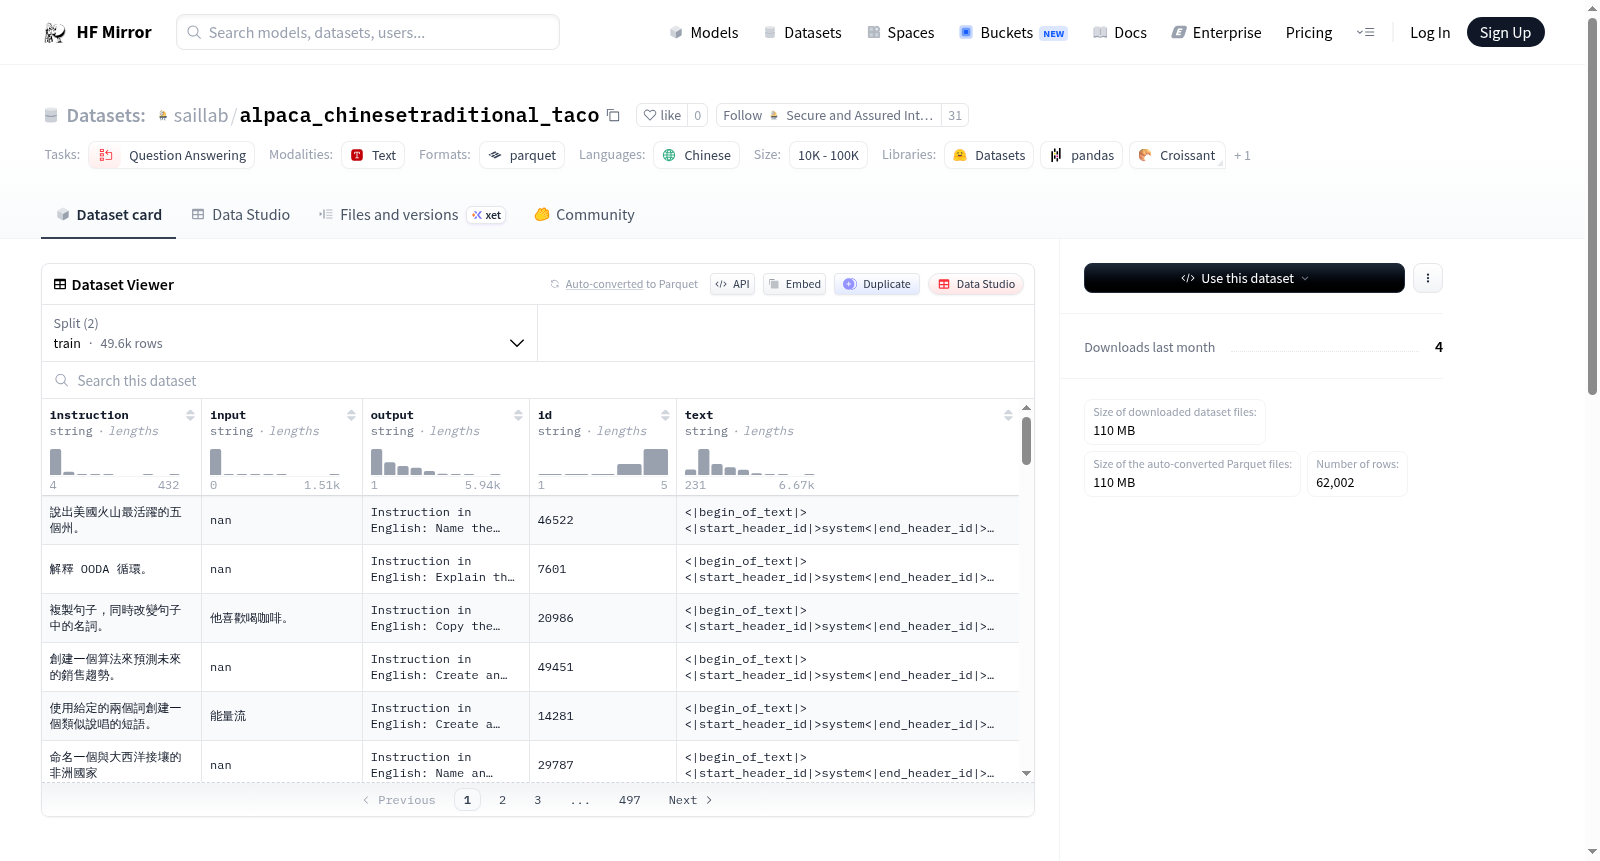
--- language: - zh pretty_name: Chinese Traditional alpaca-52k size_categories: - 100K<n<1M task_categories: - question-answering --- This repository contains the dataset used for the TaCo paper. The dataset follows the style outlined in the TaCo paper, as follows: ``` { "instruction": "instruction in xx", "input": "input in xx", "output": "Instruction in English: instruction in en , Response in English: response in en , Response in xx: response in xx " } ``` Please refer to the paper for more details: [OpenReview](https://openreview.net/forum?id=02MLWBj8HP) If you have used our dataset, please cite it as follows: **Citation** ``` @inproceedings{upadhayay2024taco, title={TaCo: Enhancing Cross-Lingual Transfer for Low-Resource Languages in {LLM}s through Translation-Assisted Chain-of-Thought Processes}, author={Bibek Upadhayay and Vahid Behzadan}, booktitle={5th Workshop on practical ML for limited/low resource settings, ICLR}, year={2024}, url={https://openreview.net/forum?id=02MLWBj8HP} } ``` The original dataset [(Alpaca-52K)](https://github.com/tatsu-lab/stanford_alpaca?tab=readme-ov-file#data-release) was translated using Google Translate. **Copyright and Intended Use** This dataset has been released under CC BY-NC, intended for academic and research purposes only. Please review the licenses and terms and conditions of Alpaca-52K, Dolly-15K, and Google Cloud Translation before using this dataset for any purpose other than research.
语言: - 简体中文(zh) 数据集名称:繁体中文Alpaca-52K 数据规模分类: - 10万<样本量<100万 任务分类: - 问答任务 --- 本仓库包含TaCo论文所使用的数据集。 该数据集遵循TaCo论文中规定的格式,示例如下: { "instruction": "xx语言的指令", "input": "xx语言的输入", "output": "英文指令:英文原指令, 英文回复:英文原回复, xx语言回复:xx语言原文回复" } 如需了解更多细节,请参阅该论文:[OpenReview](https://openreview.net/forum?id=02MLWBj8HP) 若您使用了本数据集,请按以下方式引用: **引用** @inproceedings{upadhayay2024taco, title={TaCo:借助翻译辅助思维链(Chain-of-Thought)流程提升大语言模型(LLM)中低资源语言的跨语言迁移能力}, author={Bibek Upadhayay and Vahid Behzadan}, booktitle={第五届有限/低资源场景下的实用机器学习研讨会,国际学习表征会议(ICLR)}, year={2024}, url={https://openreview.net/forum?id=02MLWBj8HP} } 原始数据集[(Alpaca-52K)](https://github.com/tatsu-lab/stanford_alpaca?tab=readme-ov-file#data-release)通过谷歌翻译(Google Translate)完成翻译。 **版权与使用意图** 本数据集采用CC BY-NC协议发布,仅可用于学术与研究用途。在将本数据集用于研究以外的任何用途前,请务必查阅Alpaca-52K、Dolly-15K以及谷歌云翻译(Google Cloud Translation)的许可协议与条款细则。
数据集概述
数据集特征
- instruction:数据类型为字符串。
- input:数据类型为字符串。
- output:数据类型为字符串。
- id:数据类型为字符串。
- text:数据类型为字符串。
数据集分割
- 训练集:包含49601个样本,总大小为169440247.96090448字节。
- 测试集:包含12401个样本,总大小为42362624.03909551字节。
数据集大小
- 下载大小:110206046字节。
- 数据集总大小:211802872.0字节。
数据文件配置
- 默认配置:
- 训练集路径:
data/train-* - 测试集路径:
data/test-*
- 训练集路径: