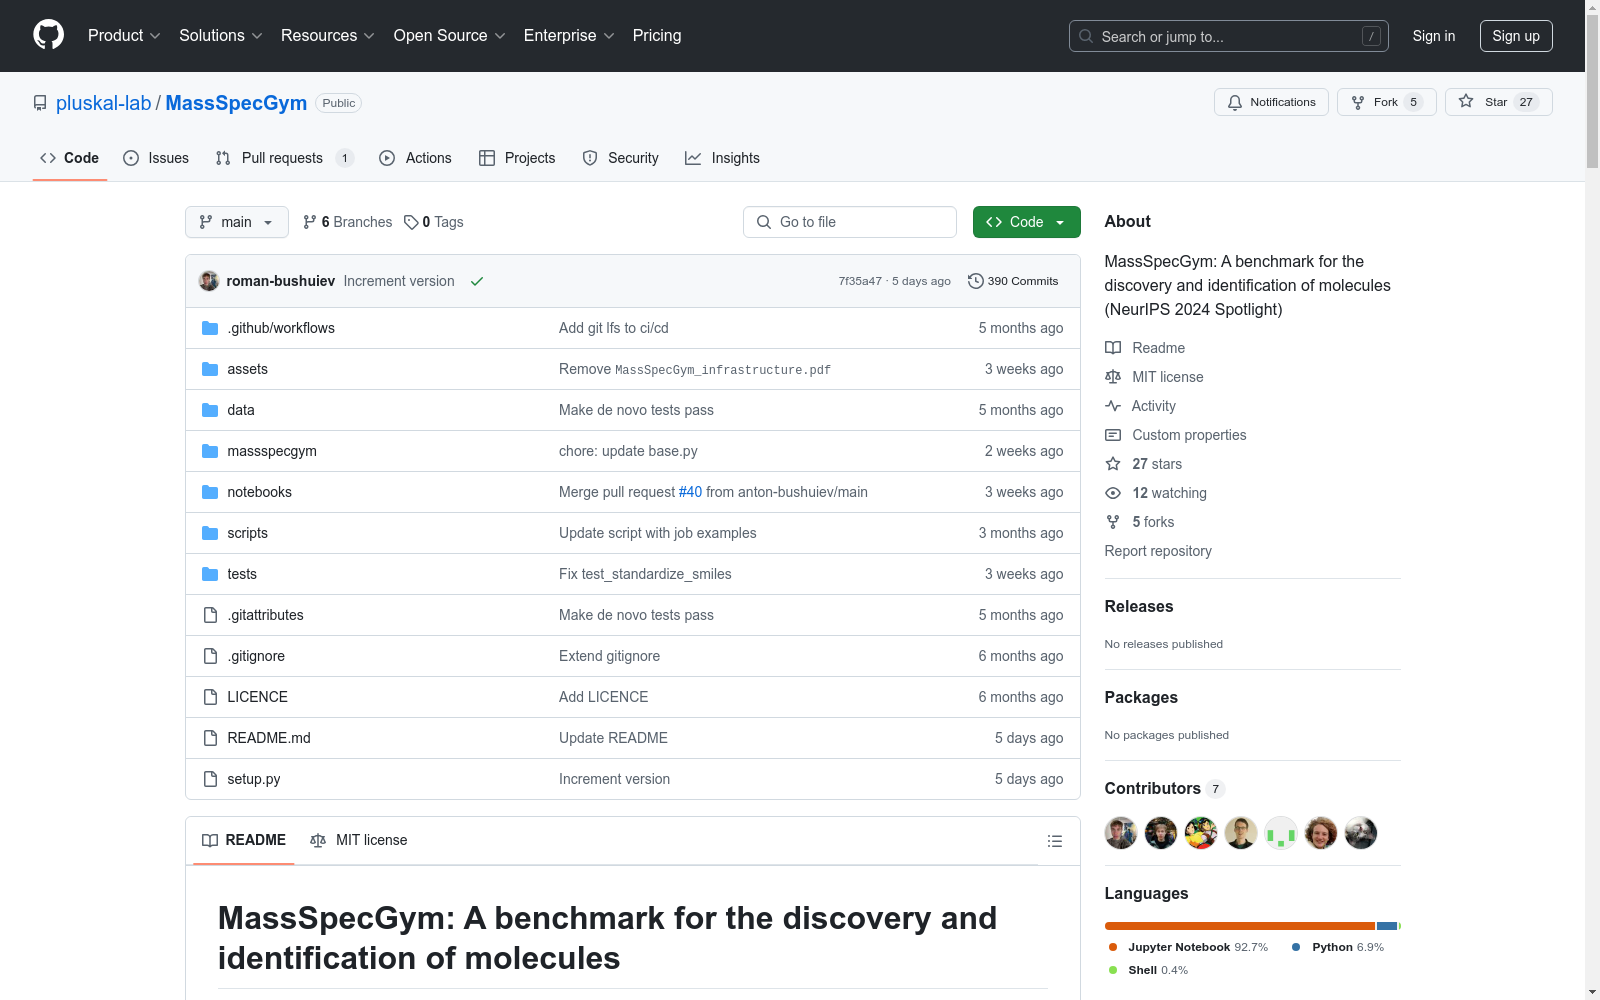
MassSpecGym
收藏资源简介:
MassSpecGym是由捷克科学院有机化学与生物化学研究所等机构创建的一个综合基准数据集,旨在解决从MS/MS数据中发现和识别分子的问题。该数据集包含231,000个高质量的MS/MS光谱,代表了29,000个独特的分子结构,是目前公开的最大数据集。数据集的创建过程包括严格的质量评估和数据分割,确保数据的高质量和无泄漏。MassSpecGym的应用领域广泛,包括生物医学、化学科学、药物开发和环境分析等,旨在通过标准化数据集和评估协议,推动MS/MS光谱注释方法的发展。
MassSpecGym is a comprehensive benchmark dataset created by the Institute of Organic Chemistry and Biochemistry of the Czech Academy of Sciences and other institutions, aiming to address the challenge of discovering and identifying molecules from MS/MS data. This dataset contains 231,000 high-quality MS/MS spectra, representing 29,000 unique molecular structures, making it the largest publicly available dataset to date. The construction of MassSpecGym incorporates strict quality assessment and data splitting procedures to ensure high data quality and eliminate data leakage. MassSpecGym covers a wide range of application scenarios including biomedicine, chemical sciences, drug development and environmental analysis, and it aims to promote the development of MS/MS spectrum annotation methods via standardized datasets and evaluation protocols.
MassSpecGym: A benchmark for the discovery and identification of molecules
数据集概述
MassSpecGym 提供三个挑战,用于基准测试从 MS/MS 光谱中发现和识别新分子的能力:
- De novo 分子生成 (MS/MS 光谱 → 分子结构)
- 化学式挑战 (MS/MS 光谱 + 化学式 → 分子结构)
- 分子检索 (MS/MS 光谱 → 候选分子结构排名列表)
- 化学式挑战 (MS/MS 光谱 + 化学式 → 候选分子结构排名列表)
- 光谱模拟 (分子结构 → MS/MS 光谱)
数据集组件
- MassSpecGym 数据集:可作为 Hugging Face 数据集使用,可通过代码下载到 pandas DataFrame。
- 数据转换:提供光谱和分子的转换工具,用于预处理机器学习模型的数据。
- MassSpecDataModule:PyTorch Lightning 的 LightningDataModule,自动处理数据分割和批量加载。
模型实现
- DeNovoMassSpecGymModel
- RetrievalMassSpecGymModel
- SimulationMassSpecGymModel
使用示例
数据加载
python from massspecgym.utils import load_massspecgym df = load_massspecgym()
数据集和转换
python from massspecgym.data import MassSpecDataset from massspecgym.transforms import SpecTokenizer, MolFingerprinter
dataset = MassSpecDataset( spec_transform=SpecTokenizer(n_peaks=60), mol_transform=MolFingerprinter(), )
数据模块
python from massspecgym.data import MassSpecDataModule
data_module = MassSpecDataModule( dataset=dataset, batch_size=32 )
模型训练与评估
python import torch import torch.nn as nn import pytorch_lightning as pl from pytorch_lightning import Trainer
from massspecgym.data import RetrievalDataset, MassSpecDataModule from massspecgym.data.transforms import SpecTokenizer, MolFingerprinter from massspecgym.models.base import Stage from massspecgym.models.retrieval.base import RetrievalMassSpecGymModel
class MyDeepSetsRetrievalModel(RetrievalMassSpecGymModel): def init( self, hidden_channels: int = 128, out_channels: int = 4096, # fingerprint size *args, **kwargs ): super().init(*args, **kwargs)
    self.phi = nn.Sequential(
        nn.Linear(2, hidden_channels),
        nn.ReLU(),
        nn.Linear(hidden_channels, hidden_channels),
        nn.ReLU(),
    )
    self.rho = nn.Sequential(
        nn.Linear(hidden_channels, hidden_channels),
        nn.ReLU(),
        nn.Linear(hidden_channels, out_channels),
        nn.Sigmoid()
    )

def forward(self, x: torch.Tensor) -> torch.Tensor:
    x = self.phi(x)
    x = x.sum(dim=-2)  # sum over peaks
    x = self.rho(x)
    return x

def step(
    self, batch: dict, stage: Stage
) -> tuple[torch.Tensor, torch.Tensor]:
    x = batch["spec"]  # input spectra
    fp_true = batch["mol"]  # true fingerprints
    cands = batch["candidates"]  # candidate fingerprints concatenated for a batch
    batch_ptr = batch["batch_ptr"]  # number of candidates per sample in a batch

    fp_pred = self.forward(x)
    loss = nn.functional.mse_loss(fp_true, fp_pred)
    fp_pred_repeated = fp_pred.repeat_interleave(batch_ptr, dim=0)
    scores = nn.functional.cosine_similarity(fp_pred_repeated, cands)

    return dict(loss=loss, scores=scores)
Init hyperparameters
n_peaks = 60 fp_size = 4096 batch_size = 32
Load dataset
dataset = RetrievalDataset( spec_transform=SpecTokenizer(n_peaks=n_peaks), mol_transform=MolFingerprinter(fp_size=fp_size), )
Init data module
data_module = MassSpecDataModule( dataset=dataset, batch_size=batch_size, num_workers=4 )
Init model
model = MyDeepSetsRetrievalModel(out_channels=fp_size)
Init trainer
trainer = Trainer(accelerator="cpu", devices=1, max_epochs=5)
Train
trainer.fit(model, datamodule=data_module)
Test
trainer.test(model, datamodule=data_module)
引用
bibtex @article{bushuiev2024massspecgym, title={MassSpecGym: A benchmark for the discovery and identification of molecules}, author={Roman Bushuiev and Anton Bushuiev and Niek F. de Jonge and Adamo Young and Fleming Kretschmer and Raman Samusevich and Janne Heirman and Fei Wang and Luke Zhang and Kai Dührkop and Marcus Ludwig and Nils A. Haupt and Apurva Kalia and Corinna Brungs and Robin Schmid and Russell Greiner and Bo Wang and David S. Wishart and Li-Ping Liu and Juho Rousu and Wout Bittremieux and Hannes Rost and Tytus D. Mak and Soha Hassoun and Florian Huber and Justin J. J. van der Hooft and Michael A. Stravs and Sebastian Böcker and Josef Sivic and Tomáš Pluskal}, year={2024}, eprint={2410.23326}, url={https://arxiv.org/abs/2410.23326}, doi={10.48550/arXiv.2410.23326} }