autophagycode_D_mercury_Qwen3-4B_lr0.0001_c142_trust_t1_g3_run2
收藏资源简介:
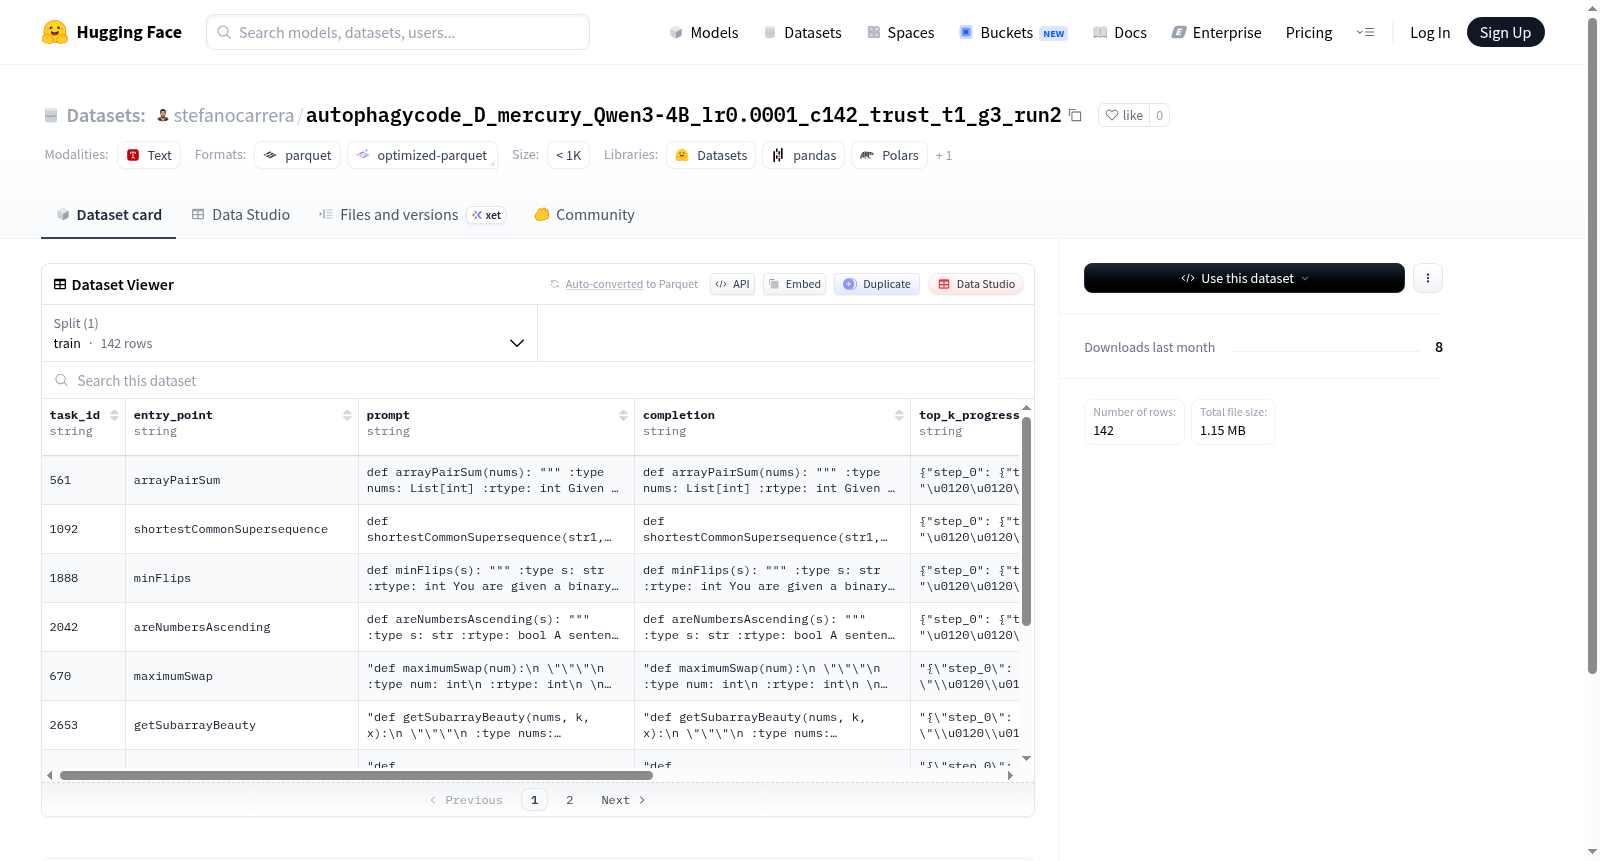
该数据集包含142个训练样本,总大小约5.86MB,仅包含训练集。每个样本包含6个字段:task_id(可能表示任务标识符)、entry_point(可能表示程序入口)、prompt(可能表示输入提示)、completion(可能表示完成文本)、top_k_progression(可能表示某种进度指标)以及test(可能表示测试相关数据)。数据文件存储在data/train-*路径中。
This dataset contains 142 training samples with a total size of approximately 5.86 MB. Each sample includes 6 fields: task_id (string type, potentially representing a task identifier), entry_point (string type, potentially denoting the program entry point), prompt (string type, potentially referring to the input prompt), completion (string type, potentially representing the completed text), top_k_progression (string type, potentially indicating a type of progress metric), and test (string type, potentially containing test-related data). This dataset only includes the training split, with the data files stored at the path data/train-*.
好的,根据您提供的数据集详情页面地址和README文件内容,以下是为您总结的数据集概述:
数据集概述
基本信息
- 数据集名称:
autophagycode_D_mercury_Qwen3-4B_lr0.0001_c142_trust_t1_g3_run2 - 托管平台: Hugging Face
- 数据集大小: 约5.86 MB
- 下载大小: 约1.15 MB
数据规模
- 总样本数: 142 条
- 数据划分: 仅包含
train训练集,共 142 个样本
数据特征
数据集包含以下 6 个字段,均为字符串类型:
| 字段名 | 类型 | 描述 |
|---|---|---|
task_id |
string | 任务标识符 |
entry_point |
string | 入口点 |
prompt |
string | 提示 |
completion |
string | 补全结果 |
top_k_progression |
string | 前K个进展 |
test |
string | 测试数据 |
配置与文件结构
- 配置名称:
default - 数据文件路径:
data/train-* - 数据格式: 可通过 Hugging Face
datasets库加载使用