rebase_gemma-4-E4B-it_rg_cognition_ns8_md4_bt0_1_seed42_rg_cognition__v0
收藏资源简介:
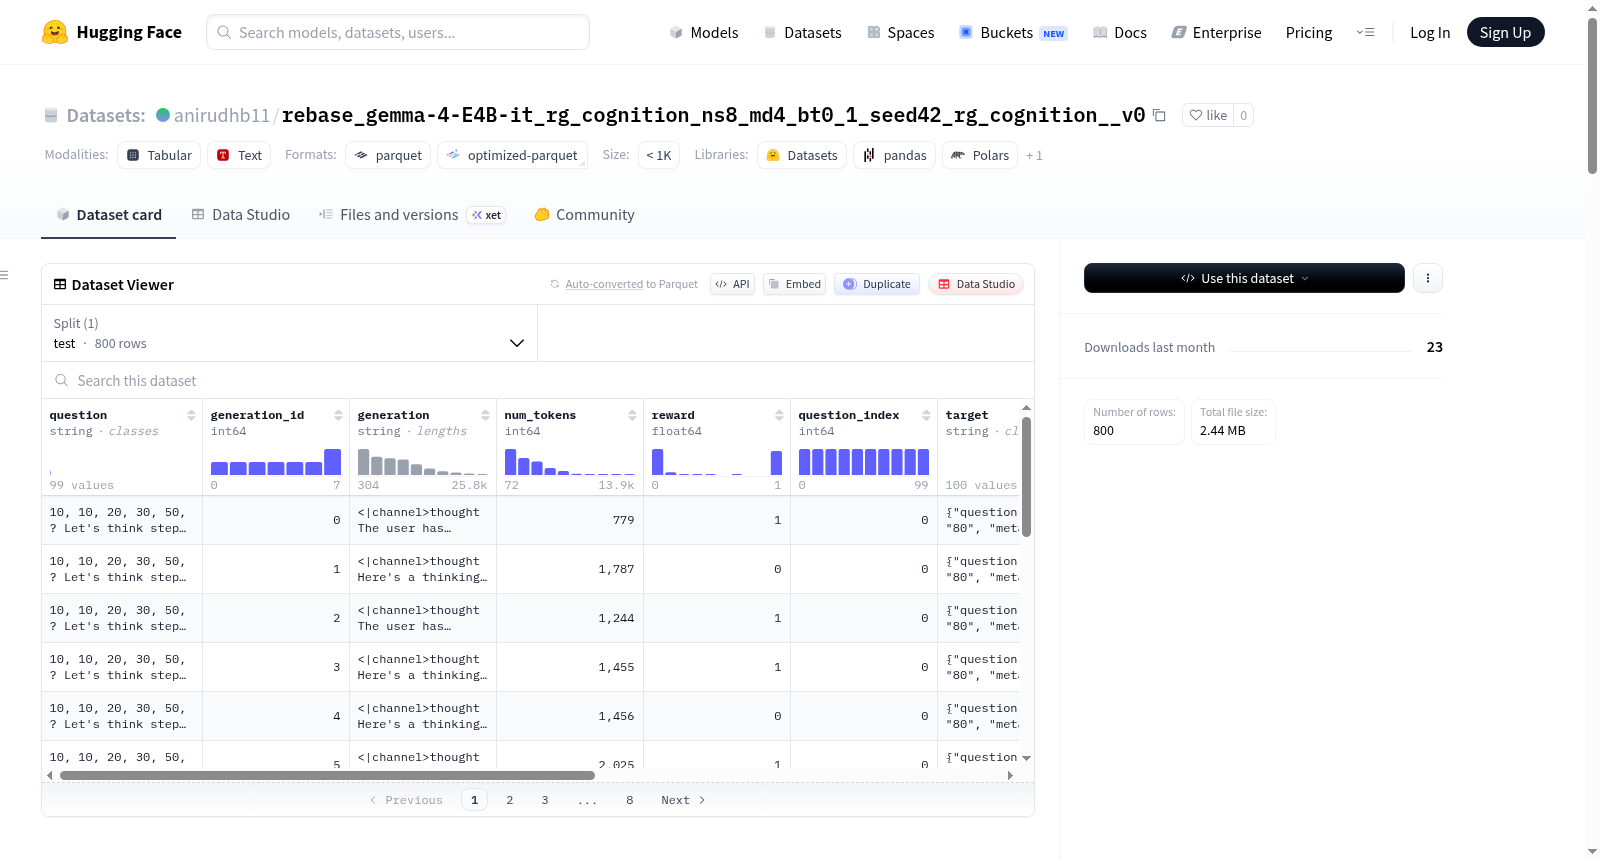
该数据集包含800个测试样本,每个样本包含多个字段,如问题(question)、生成ID(generation_id)、生成内容(generation)、令牌数量(num_tokens)、奖励(reward)、问题索引(question_index)、目标(target)、任务(task)、价值函数预测(vf_prediction)和级别(level)。数据集的主要目的是评估生成内容的质量和性能,这从奖励、预测字段以及丰富的聚合指标中可以看出。这些指标涵盖了不同级别的法官和政策输出令牌数量、通过率、唯一答案数量等,表明数据集适用于生成模型的评估和优化任务。
This dataset contains 800 test samples, each with multiple fields including question, generation_id, generation, num_tokens, reward, question_index, target, task, vf_prediction, and level. The primary objective of this dataset is to evaluate the quality and performance of generated content, as evidenced by the reward and vf_prediction fields as well as a rich collection of aggregated metrics. These metrics cover judge-level and policy-level output token counts, pass rates, the number of unique answers, and other relevant indicators, demonstrating that the dataset is applicable to the evaluation and optimization tasks of generative models.
数据集概述
该数据集名为 rebase_gemma-4-E4B-it_rg_cognition_ns8_md4_bt0_1_seed42_rg_cognition__v0,由 anirudhb11 在 Hugging Face 上发布。
数据集结构
数据集包含一个默认配置(default),仅有 测试集(test) 一个划分,共 800 个样本。数据集大小为 8,896,088 字节(约 8.5 MB),下载大小为 2,422,722 字节(约 2.3 MB)。
数据特征
每条数据包含以下 10 个字段:
| 字段名 | 类型 | 说明 |
|---|---|---|
question |
string | 问题文本 |
generation_id |
int64 | 生成 ID |
generation |
string | 生成的回答内容 |
num_tokens |
int64 | 回答的 token 数量 |
reward |
float64 | 奖励值 |
question_index |
int64 | 问题索引 |
target |
string | 目标答案 |
task |
string | 任务名称 |
vf_prediction |
float64 | 价值函数预测值 |
level |
int64 | 层级 |
关键性能指标
数据集基于 10 个分片(shards) 的加权平均聚合指标如下:
-
正确率相关:
pass@1: 0.43125pass@8: 0.56maj@1: 0.458467maj@8: 0.487949
-
回答多样性:
num_unique_answers@1: 0.95num_unique_answers@8: 3.461
-
Token 统计:
- 平均响应 tokens(
avg_response_tokens): 2732 - 中位响应 tokens(
median_response_tokens): 2070.7 - 总生成输出 tokens(
total_generated_output_tokens): 279,548 - 总策略输出 tokens(
total_policy_output_tokens): 218,566 - 总裁判输出 tokens(
total_judge_output_tokens): 60,981.9
- 平均响应 tokens(
-
时间统计:
- 生成阶段时间(
generation_phase_time_s): 282.359 秒 - 总时间(
total_time_s): 333.574 秒
- 生成阶段时间(
-
截断率:所有层级的截断率均为 0。
-
裁判输出 tokens(按层级):
- 层级 1: 平均 token 数量 3220,输出 tokens 21,727.5
- 层级 2: 平均 token 数量 1478.57,输出 tokens 3,196.3
- 层级 3: 平均 token 数量 1800,输出 tokens 508
- 层级 4: 平均 token 数量 0,输出 tokens 0
-
裁判跳过已完成次数:
- 层级 1: 60.6
- 层级 2: 16.7
- 层级 3: 3.28571
- 层级 4: 4