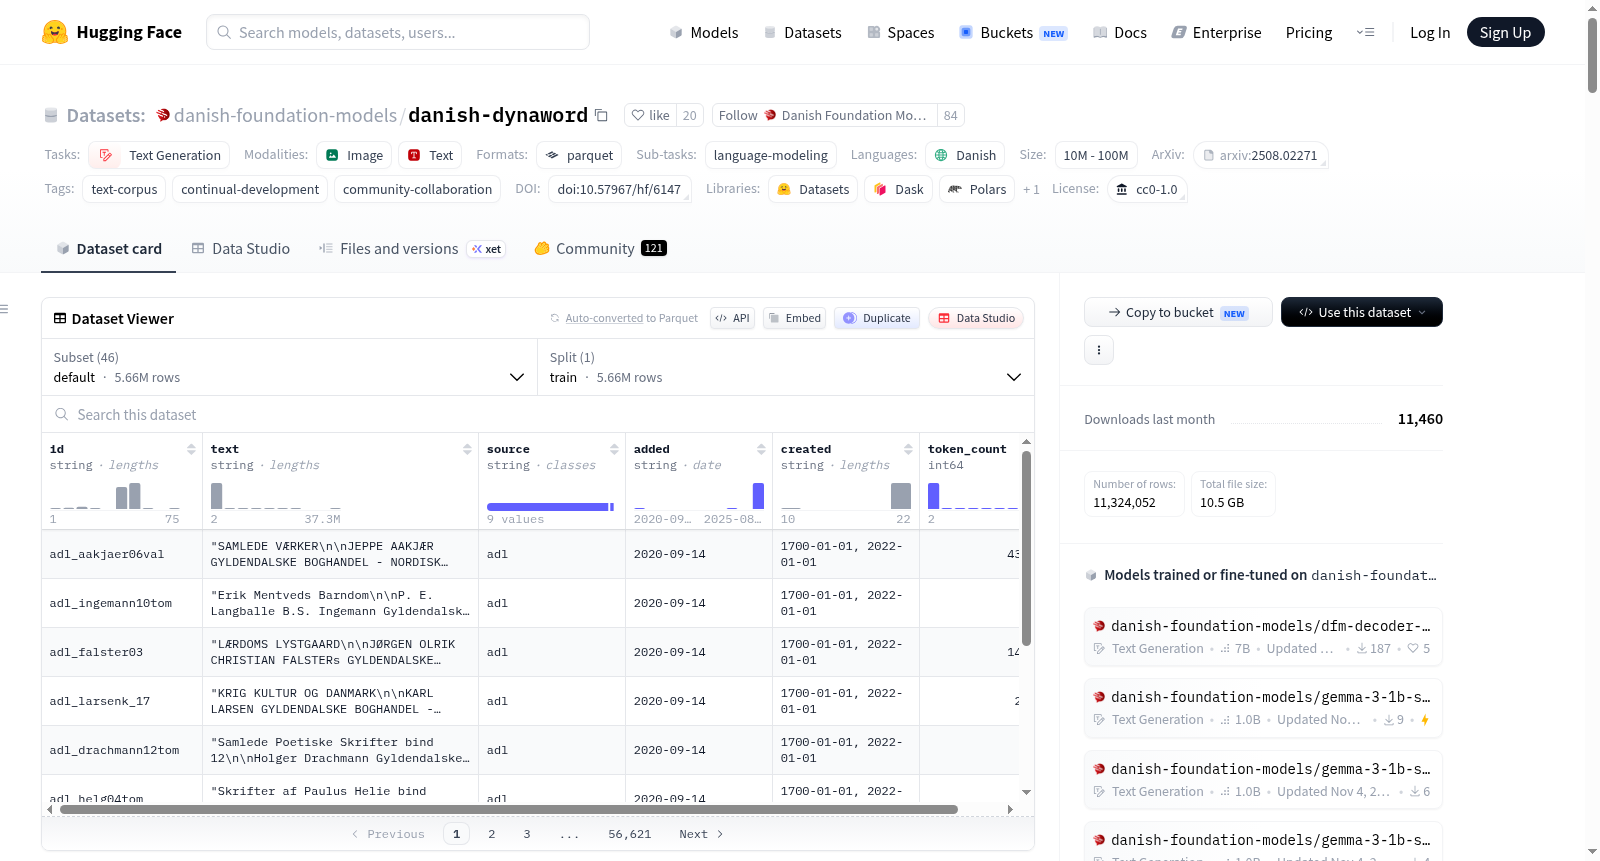
danish-foundation-models/danish-dynaword
收藏资源简介:
Danish Dynaword是一个不断更新的丹麦自由文本数据集集合,涵盖多个领域。该数据集旨在持续更新新的数据源,主要用于语言模型的开发,但也适用于其他用途,如语言发展和跨领域差异的研究。数据集包含来自不同来源的文本,每个条目都包含一个文本及其相关元数据。
The Danish dynaword is a continually developed collection of Danish free-form text datasets from various domains. It is intended to be continually updated with new data sources. If you would like to contribute a dataset see the [contribute section](#contributing-to-the-dataset). The dataset includes multiple configurations (subsets) each with its own data files in Parquet format. The dataset is monolingual, containing text in Danish, and is curated with the intention of making large quantities of Danish text data available for various NLP tasks such as language modeling. Each data instance includes metadata such as source, unique identifier, date added, date range of creation, license, and domain. The dataset is provided in a single train split. The README also mentions the languages included in the dataset, which are denoted using BCP-47 language tags.