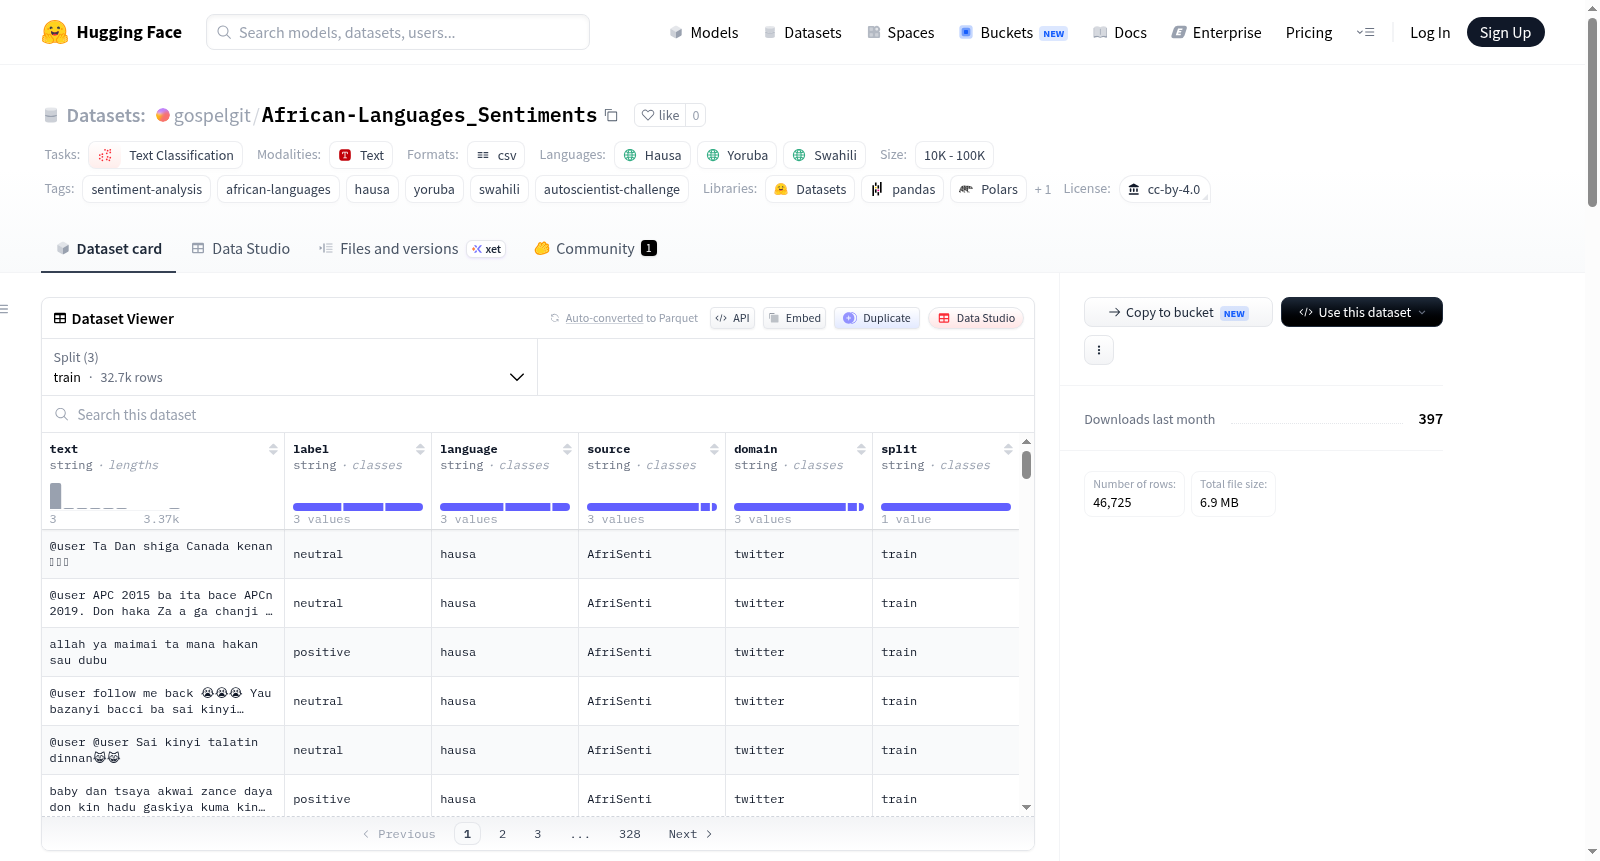
African-Languages_Sentiments
收藏资源简介:
非洲语言情感数据集(豪萨语、约鲁巴语、斯瓦希里语)是一个多源缝合的情感分类数据集,专为Adaption Labs AutoScientist Challenge(语言类别)构建。该数据集整合了三个独立收集的情感语料库,涵盖豪萨语、约鲁巴语和斯瓦希里语三种非洲语言,旨在通过结合三个不同领域的数据源来减少领域过拟合,提供更稳健的情感分析信号。数据集包含46,725行数据,采用70/15/15的训练/验证/测试分割,并按标签进行分层。具体语言分布为:豪萨语23,162行,约鲁巴语16,627行,斯瓦希里语6,936行。数据来源于三个不同领域:AfriSenti(Twitter领域,40,290行)、NollySenti(诺莱坞电影评论领域,2,510行)和Neurotech-HQ Swahili(社交媒体/产品评论领域,3,925行)。数据集结构包含六个字段:text(原始文本,包括推文、电影评论或社交媒体评论)、label(情感标签,取值为positive、negative或neutral)、language(语言标识,hausa、yoruba或swahili)、source(原始数据集来源)、domain(领域标识,twitter、movie_review或social_media_reviews)以及split(数据分割,train、validation或test)。该数据集适用于训练和评估豪萨语、约鲁巴语和斯瓦希里语的情感分类模型,特别适合用于基准测试多语言协同优化的训练方法。需要注意的是,数据集存在一些局限性:不同来源的标签分布不平衡(neutral标签仅来自AfriSenti);数据分割是重新计算的,并非原始分割;斯瓦希里语的领域构成与其他语言不同(约一半Twitter数据,一半社交媒体/产品评论数据)。
African Language Sentiment Dataset (Hausa, Yoruba, Swahili) is a multi-source fused sentiment classification dataset built specifically for the Adaption Labs AutoScientist Challenge (Language Track). This dataset integrates three independently collected sentiment corpora covering three African languages: Hausa, Yoruba, and Swahili, aiming to reduce domain overfitting and provide more robust sentiment analysis signals by combining data sources from three distinct domains. The dataset contains 46,725 rows of data, with a 70/15/15 train/validation/test split and is stratified by label. The specific language distribution is as follows: 23,162 rows for Hausa, 16,627 rows for Yoruba, and 6,936 rows for Swahili. The data is sourced from three distinct domains: AfriSenti (Twitter domain, 40,290 rows), NollySenti (Nollywood movie review domain, 2,510 rows), and Neurotech-HQ Swahili (social media/product review domain, 3,925 rows). The dataset structure includes six fields: text (raw text including tweets, movie reviews, or social media comments), label (sentiment label with values of positive, negative, or neutral), language (language identifier: hausa, yoruba, or swahili), source (original dataset source), domain (domain identifier: twitter, movie_review, or social_media_reviews), and split (data partition: train, validation, or test). This dataset is suitable for training and evaluating sentiment classification models for Hausa, Yoruba, and Swahili, and is particularly ideal for benchmarking training methods for multilingual collaborative optimization. It is worth noting that the dataset has several limitations: the label distribution is imbalanced across different sources (the neutral label only originates from AfriSenti); the data split is recalculated rather than the original split; the domain composition of Swahili data differs from the other languages, with approximately half being Twitter data and the other half being social media/product review data.
数据集概述
数据集名称:African Languages Sentiment Dataset (Hausa, Yorùbá, Swahili)
许可证:CC-BY-4.0
任务类别:文本分类
标签:情感分析、非洲语言(豪萨语、约鲁巴语、斯瓦希里语)
数据集规模:10K < 样本数 < 100K
数据集来源与构成
该数据集整合了三个独立收集的情感语料库,涵盖三种非洲语言,旨在减少单一领域(Twitter)的过拟合问题,提供更鲁棒的情感信号。
| 来源 | 领域 | 语言 | 样本数 |
|---|---|---|---|
| AfriSenti | 豪萨语、约鲁巴语、斯瓦希里语 | 40,290 | |
| NollySenti | 诺莱坞电影评论(人工翻译) | 豪萨语、约鲁巴语 | 2,510 |
| Neurotech-HQ Swahili | 社交媒体/产品评论(反向翻译) | 斯瓦希里语 | 3,925 |
总样本数:46,725
数据集结构
每条数据包含以下字段:
- text:原始文本(推文、电影评论或社交媒体评论)
- label:情感标签(
positive、negative、neutral) - language:语言(
hausa、yoruba、swahili) - source:来源数据集名称
- domain:领域(
twitter、movie_review、social_media_reviews) - split:数据划分(
train、validation、test)
数据划分
所有语言均采用 70 / 15 / 15 的 train/validation/test 比例,并按标签进行分层抽样。
| 语言 | 总计 | 训练集 | 验证集 | 测试集 |
|---|---|---|---|---|
| 豪萨语 | 23,162 | 16,213 | 3,474 | 3,475 |
| 约鲁巴语 | 16,627 | 11,639 | 2,494 | 2,494 |
| 斯瓦希里语 | 6,936 | 4,855 | 1,040 | 1,041 |
预期用途
- 用于训练和评估豪萨语、约鲁巴语、斯瓦希里语的情感分类模型。
- 特别适用于对比多语言联合优化训练方法(如 AutoScientist)与单源基线模型(如
Davlan/afrisenti-twitter-sentiment-afroxlmr-large)的性能。
局限性
- 标签分布不平衡:NollySenti 和 Neurotech Swahili 数据集仅包含正面和负面标签,
neutral标签仅来自 AfriSenti,因此中性样本覆盖较弱。 - 非原始划分:数据划分是重新计算后的结果,并非直接沿用原始数据集的划分方式,因此不能直接与原始数据集的基准结果进行逐行对比。
- Neurotech Swahili 无官方原始划分:该数据集被重新分配为 80/10/10 的比例(固定种子 42),之后才进行合并和重划分。
- 斯瓦希里语的领域构成不同:斯瓦希里语的数据约一半来自 Twitter,另一半来自社交媒体/产品评论;而豪萨语和约鲁巴语以 Twitter 数据为主,辅以少量电影评论。
参考信息
文件说明:仓库中包含 train.csv、validation.csv、test.csv 三个文件,为原始、干净、人工标注的数据集(46,725 行,70/15/15 划分),可直接用于训练流程。
上下文:该数据集为 Adaption Labs AutoScientist 挑战赛(语言类别)而构建,目标语言为豪萨语、约鲁巴语和斯瓦希里语。