ai4bharat/IndicContextEval
收藏资源简介:
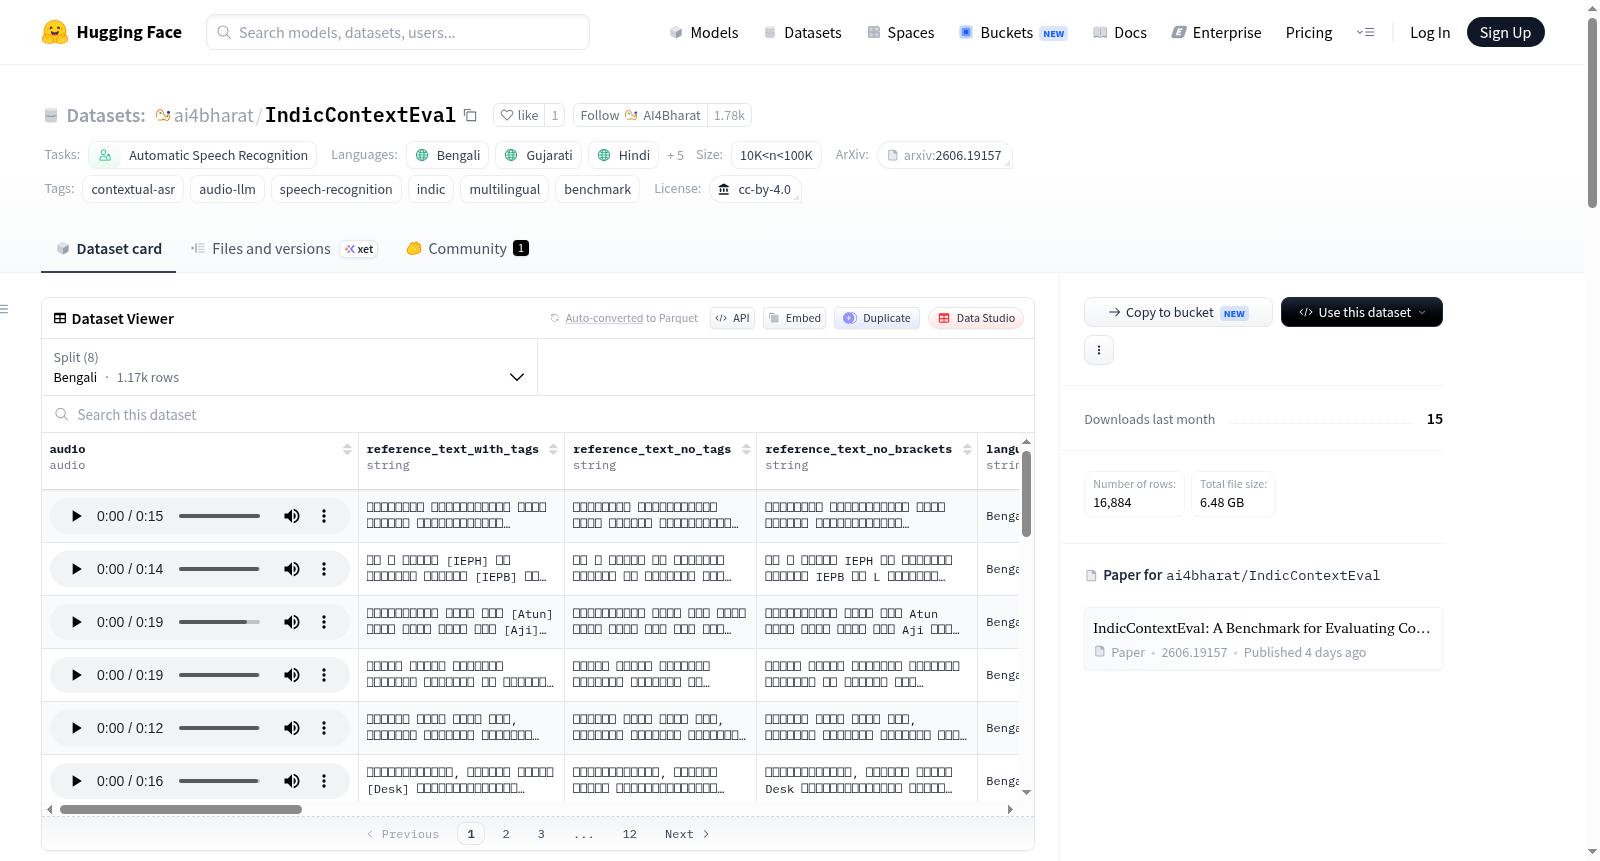
IndicContextEval是一个用于评估音频大语言模型在8种印度语言中上下文利用能力的基准数据集。该数据集包含印地语、孟加拉语、泰卢固语、马拉地语、古吉拉特语、马拉雅拉姆语、奥里亚语和乌尔都语8种语言,总共有555名说话者,55.93小时的音频,16,884个话语,覆盖23个专业领域和两种语音风格(朗读和即兴)。数据集提供了从L0到L6的7个提示级别,每个级别逐步增加上下文信号,以测试模型在不同上下文条件下的表现。数据集特征包括音频、参考文本(带标签和不带标签)、语言、时长、任务名称、领域描述、位置、语音风格、代码混合、音频块描述、各级提示、音频路径、说话者ID、性别、年龄和文件名等。
IndicContextEval is a benchmark dataset for evaluating the context utilization capabilities of audio large language models across 8 Indian languages. It includes 8 specific Indian languages: Hindi, Bengali, Telugu, Marathi, Gujarati, Malayalam, Odia and Urdu, with a total of 555 speakers, 55.93 hours of audio content, and 16,884 utterances, spanning 23 professional domains and two speech styles: read speech and extemporaneous speech. The dataset provides 7 prompt levels ranging from L0 to L6, where each level gradually increases contextual signals to test the model's performance under varying contextual conditions. Its features cover audio, reference text (both labeled and unlabeled), language, duration, task name, domain description, location, speech style, code-switching, audio chunk description, prompts at each level, audio path, speaker ID, gender, age and file name, among other relevant attributes.