nemotron-gym-instruction-following-structured-qwen3.5-122b-131k-opencode-sft-serveparity
收藏资源简介:
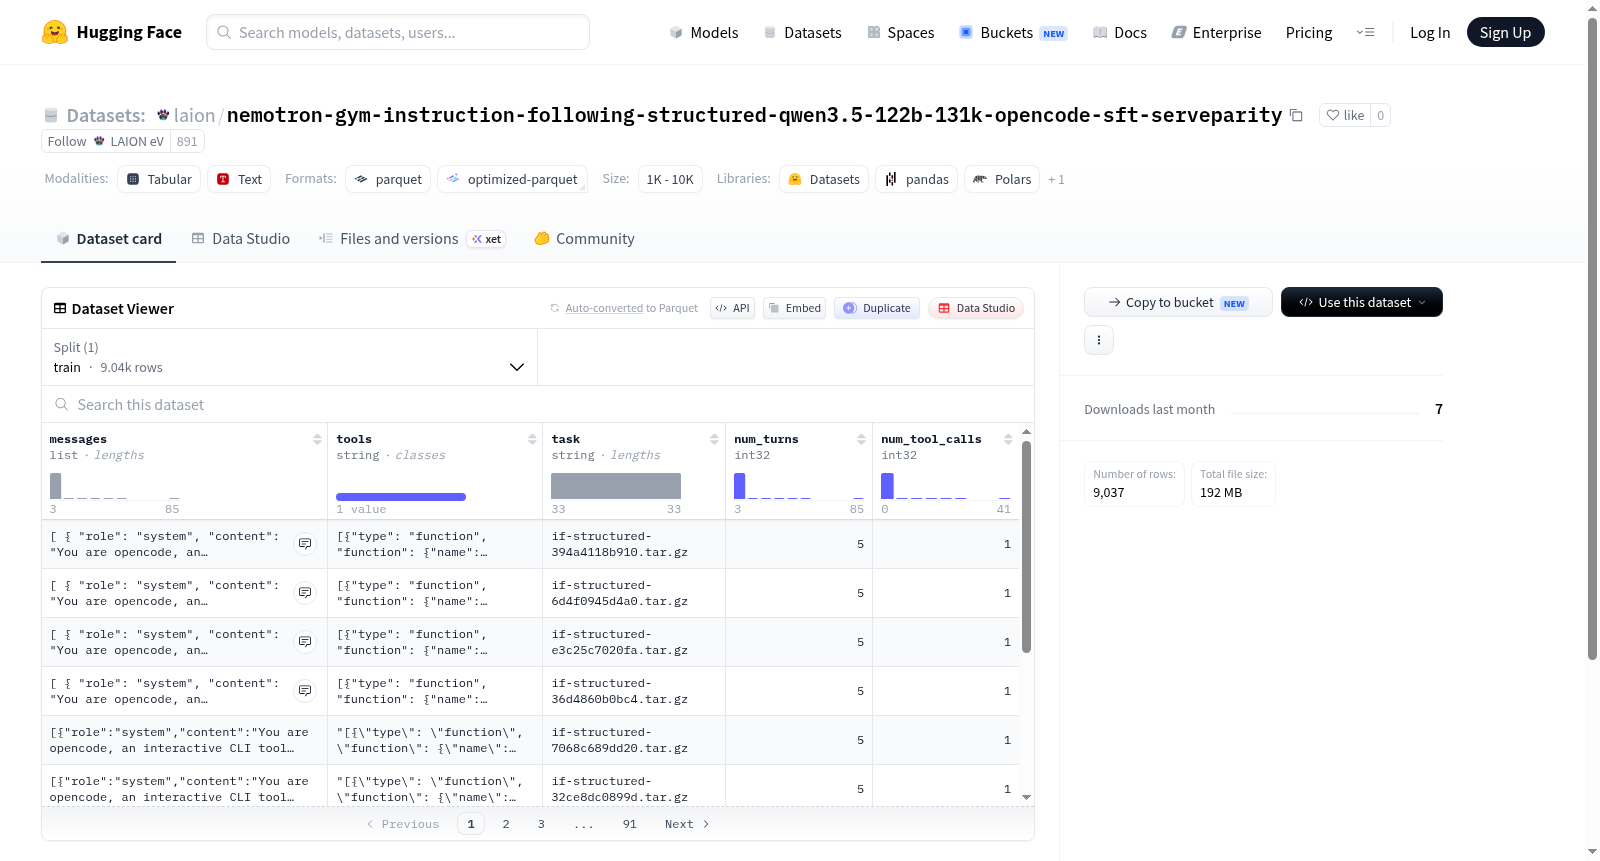
该数据集是一个结构化对话数据集,专门设计用于支持多轮对话和工具调用相关的研究与应用。数据集包含9037个训练样本,总数据量约383MB。每个样本包含以下核心字段:messages字段记录对话消息序列,每条消息包含角色(role)、内容(content)和工具调用(tool_calls)信息;tools字段描述可用工具;task字段指明任务类型;num_turns和num_tool_calls分别记录对话轮次和工具调用次数。其中工具调用采用结构化表示,包含类型(type)和函数(function)细节,函数进一步定义名称(name)和参数(arguments)。该数据集适用于对话系统开发、工具调用能力评估、智能助手训练等自然语言处理任务。
This is a structured dialogue dataset specifically developed to support research and applications pertaining to multi-turn dialogue and tool calling. The dataset comprises 9037 training samples, with an overall data size of approximately 383 MB. Each sample contains the following core fields: the `messages` field records a sequence of dialogue messages, where each message includes role, content, and `tool_calls` information; the `tools` field describes the available tools; the `task` field specifies the task type; and `num_turns` and `num_tool_calls` respectively record the number of dialogue turns and the number of tool calls. Notably, tool calls adopt a structured representation, encompassing type and function details, with the function further defining the `name` and `arguments`. This dataset is suitable for natural language processing tasks such as dialogue system development, tool calling capability evaluation, and intelligent assistant training.