
LTLBench
收藏资源简介:
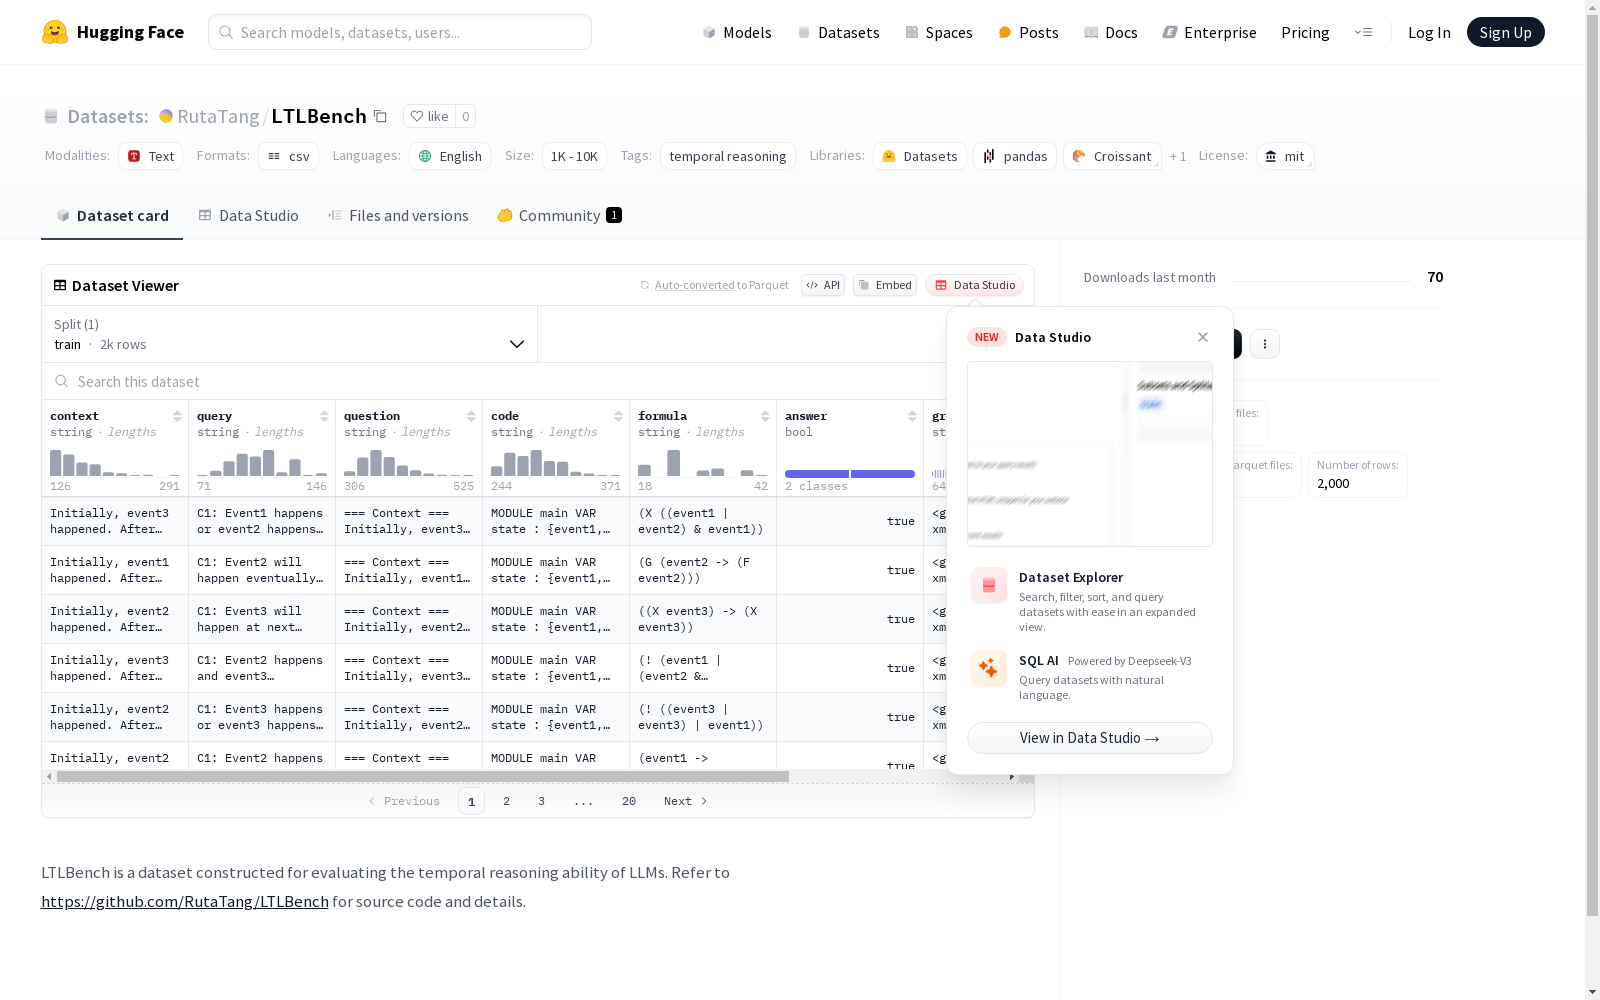
LTLBench是由爱丁堡大学开发的用于评估大型语言模型(LLMs)时间逻辑推理能力的数据集。该数据集包含2000个时间逻辑推理挑战,涉及随机生成的有向图、线性时间逻辑(LTL)公式和NuSMV模型检查器。数据集的创建过程包括四个阶段:随机有向图生成、LTL公式生成、NuSMV代码生成和自然语言生成。LTLBench旨在通过控制和可扩展的数据生成过程,评估LLMs在处理复杂时间逻辑问题上的表现,特别是在理解和处理时间信息及事件关系方面。
LTLBench is a dataset developed by the University of Edinburgh for evaluating the temporal logic reasoning capabilities of Large Language Models (LLMs). This dataset contains 2000 temporal logic reasoning challenges involving randomly generated directed graphs, Linear Temporal Logic (LTL) formulas, and the NuSMV model checker. The dataset creation process consists of four stages: random directed graph generation, LTL formula generation, NuSMV code generation, and natural language generation. LTLBench aims to evaluate the performance of LLMs in handling complex temporal logic problems, particularly in understanding and processing temporal information and event relationships, through a controlled and scalable data generation pipeline.
数据集概述
数据集名称
- LTLBench
许可
- MIT
语言
- 英语
标签
- 时间推理
数据规模
- 1K<n<10K
- 1LTLBench: Towards Benchmarks for Evaluating Temporal Logic Reasoning in Large Language Models爱丁堡大学 · 2024年


