arxiver
收藏资源简介:
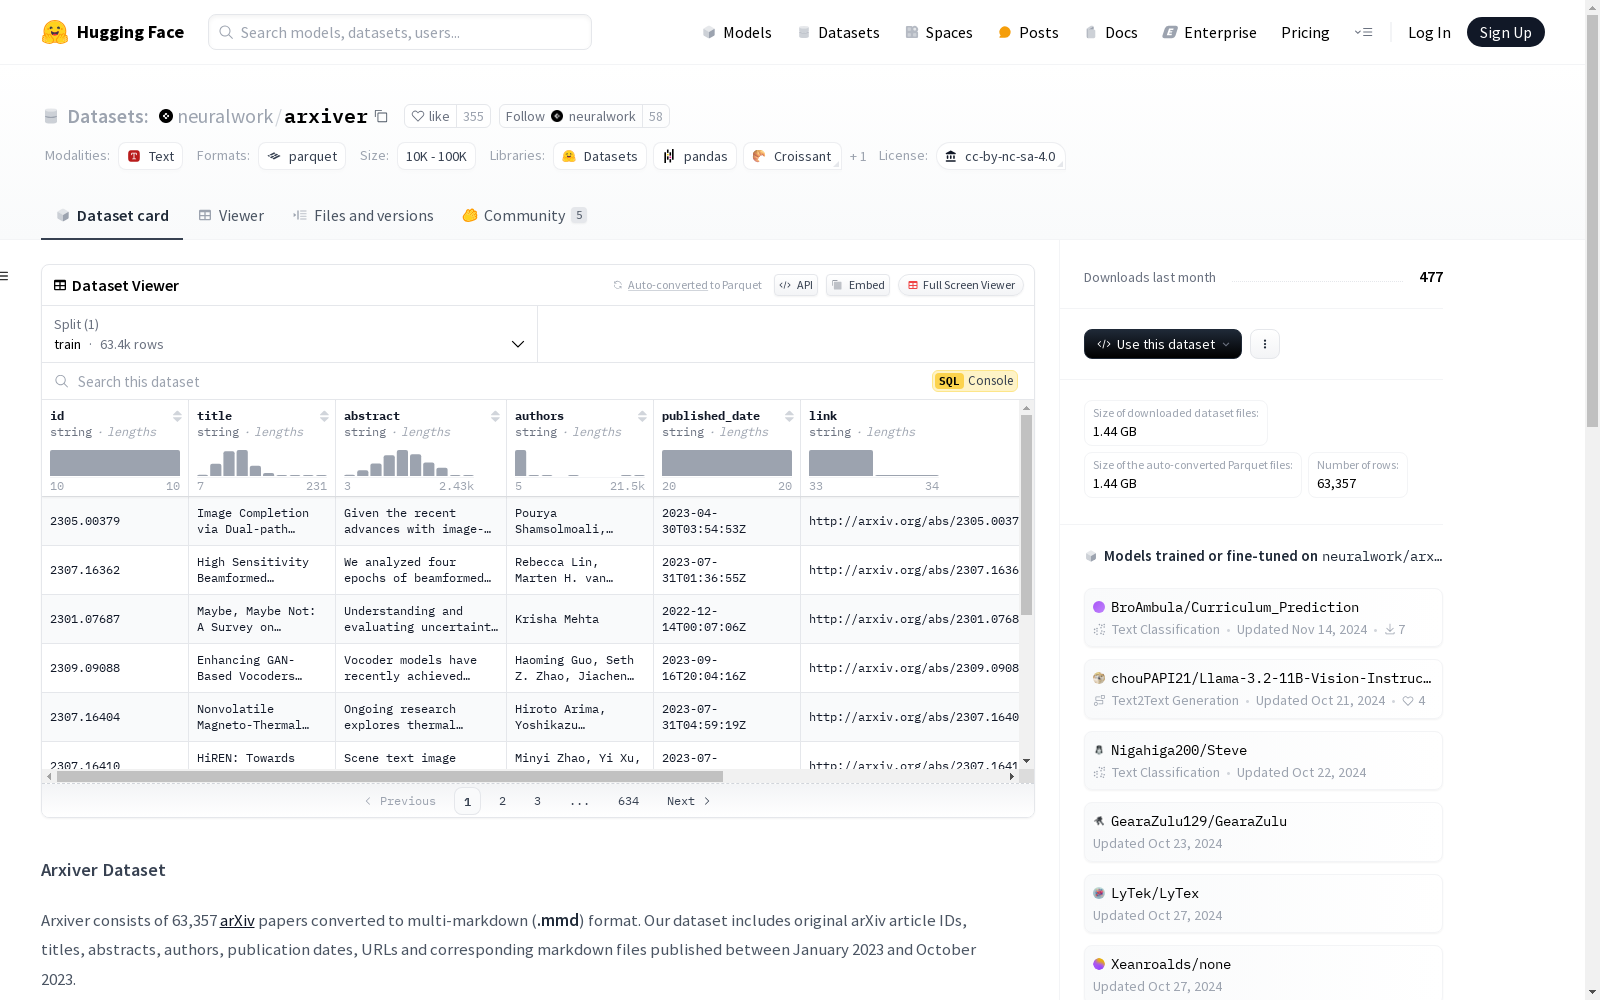
Arxiver数据集包含63,357篇从arXiv转换为多标记格式(.mmd)的论文。数据集包括原始的arXiv文章ID、标题、摘要、作者、出版日期、URL以及相应的markdown文件,这些文件是在2023年1月至2023年10月期间发布的。数据集的创建使用了神经OCR技术Nougat,并经过自定义的文本处理步骤进行数据精炼,包括提取作者信息、移除参考部分以及进行额外的清理和格式化。该数据集适用于语义搜索、特定领域语言建模、问答和摘要等多种应用。
The Arxiver dataset contains 63,357 papers converted from arXiv into multi-label format (.mmd). The dataset includes the original arXiv article IDs, titles, abstracts, authors, publication dates, URLs, and corresponding markdown files, which were published between January 2023 and October 2023. The dataset was created using the neural OCR technology Nougat, and refined through custom text processing steps including extracting author information, removing reference sections, and performing additional cleaning and formatting. This dataset is applicable to a wide range of scenarios such as semantic search, domain-specific language modeling, question answering and text summarization.
Arxiver 数据集
概述
Arxiver 数据集包含 138,830 篇从 arXiv 获取的论文,这些论文被转换为多重 Markdown (.mmd) 格式。数据集包括原始 arXiv 文章 ID、标题、摘要、作者、发布日期、URL 以及相应的 Markdown 文件,这些文件发布于 2023 年 1 月至 2023 年 10 月之间。
数据集结构
特征
- id: 字符串类型,文章的唯一标识符。
- title: 字符串类型,文章的标题。
- abstract: 字符串类型,文章的摘要。
- authors: 字符串类型,文章的作者列表。
- published_date: 字符串类型,文章的发布日期。
- link: 字符串类型,文章的 URL 链接。
- markdown: 字符串类型,文章的 Markdown 格式内容。
分割
- train: 包含 138,380 个样本,总大小为 6.95 GB。
大小
- 下载大小: 3.23 GB
- 数据集大小: 6.95 GB
使用方法
可以通过 Hugging Face 的 datasets 库下载和使用 Arxiver 数据集。
完整下载
python from datasets import load_dataset
dataset = load_dataset("neuralwork/arxiver") print(dataset)
流式下载
python from datasets import load_dataset
dataset = load_dataset("neuralwork/arxiver", streaming=True) print(dataset) print(next(iter(dataset[train])))
许可证
数据集以 Creative Commons Attribution-Noncommercial-ShareAlike (CC BY-NC-SA 4.0) 许可证发布。
引用
如果使用此数据集,请引用如下:
@misc{acar_arxiver2024, author = {Alican Acar, Alara Dirik, Muhammet Hatipoglu}, title = {ArXiver}, year = {2024}, publisher = {Hugging Face}, howpublished = {url{https://huggingface.co/datasets/neuralwork/arxiver}} }