karanverma19/india-reasoning-health-agri
收藏资源简介:
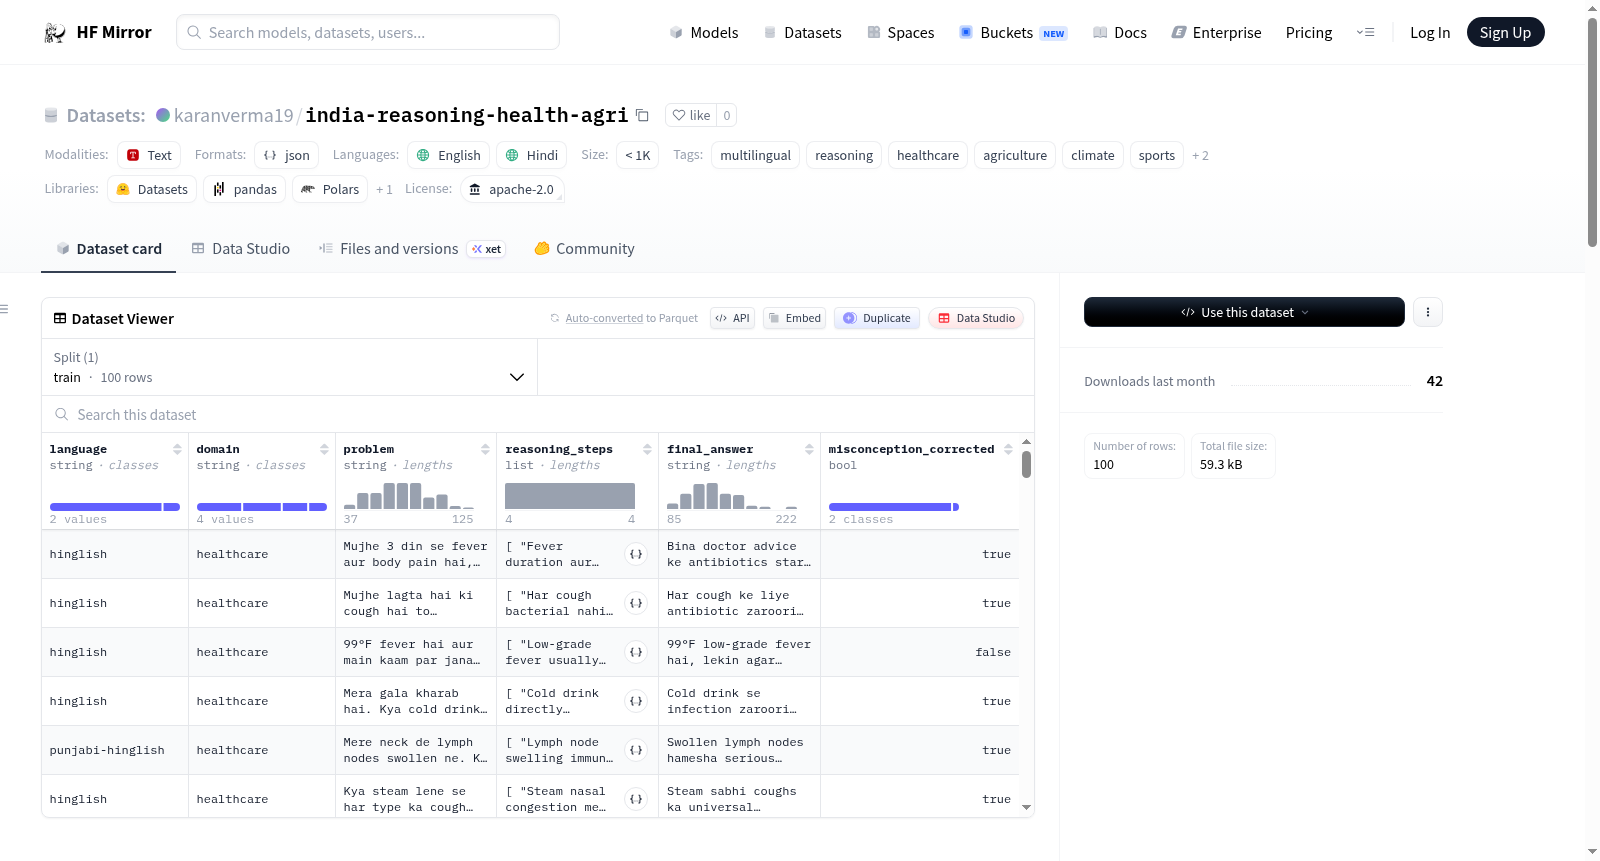
--- license: apache-2.0 tags: - multilingual - reasoning - healthcare - agriculture - climate - sports - hinglish - punjabi language: - en - hi --- # India Reasoning Dataset A multilingual reasoning dataset designed to improve real-world decision-making and correct common misconceptions. Built to improve how AI thinks, not just what it answers, using real-world, multilingual problems and practical reasoning. This dataset focuses on real-world problems people actually face in daily life, especially in multilingual Indian contexts. It helps models go beyond giving answers by improving how they reason, understand intent, and correct common misconceptions. The goal is to make AI responses more practical, reliable, and closer to how humans think and decide. --- ## Overview This is a multilingual, reasoning-based dataset designed to help models: - Understand real-world problems - Follow step-by-step reasoning - Correct common misconceptions - Respond in natural Hinglish and Punjabi-style language --- ## Domains The dataset covers practical scenarios from: - Healthcare (symptoms, treatment decisions) - Agriculture (crop issues, irrigation, pests) - Climate (heat, weather decisions) - Sports (cricket strategy and decision-making) --- ## Languages - Hinglish (Hindi + English) - Punjabi-Hinglish - English --- ## Data Format Each example contains: - `language` - `domain` - `problem` - `reasoning_steps` - `final_answer` - `misconception_corrected` --- ## Example ```json { "language": "hinglish", "domain": "healthcare", "problem": "Mujhe 3 din se fever hai, kya antibiotics leni chahiye?", "reasoning_steps": [ "Check duration of fever", "Differentiate viral vs bacterial infection", "Antibiotics only work for bacterial infections" ], "final_answer": "Mild fever me antibiotics zaroori nahi hoti. Doctor advice lena better hai.", "misconception_corrected": true }
--- 许可证:Apache-2.0 标签: - 多语言 - 推理 - 医疗健康 - 农业 - 气候 - 体育 - 印地语英语混合语(Hinglish) - 旁遮普语 支持语言: - 英语 - 印地语 --- # 印度推理数据集 本数据集为多语言推理类数据集,旨在优化现实场景下的决策能力,并纠正大众常见的认知误区。 本数据集依托真实世界中的多语言问题与实用推理逻辑,核心目标是优化AI的思维模式,而非仅提升其答案输出质量。 本数据集聚焦于人们日常生活中实际遭遇的现实问题,尤其针对多语言环境下的印度本土场景。 该数据集可帮助模型跳出仅输出答案的局限,全面提升其推理能力、意图理解能力,并纠正常见认知误区。 其最终目标是让AI的回复更具实用性与可靠性,更贴合人类的思考与决策逻辑。 ## 数据集概述 本数据集为基于推理的多语言数据集,旨在助力模型达成以下目标: - 理解现实场景中的问题 - 遵循分步推理逻辑 - 纠正常见认知误区 - 以自然的印地语英语混合语(Hinglish)与旁遮普语风格语言进行回复 ## 覆盖领域 本数据集涵盖以下领域的实用场景: - 医疗健康(症状识别、治疗决策) - 农业(作物问题、灌溉管理、虫害防治) - 气候(高温应对、天气相关决策) - 体育(板球战术与决策制定) ## 支持语言 - 印地语英语混合语(Hinglish) - 旁遮普语-印地语英语混合语 - 英语 ## 数据格式 每条数据样本包含以下字段: - `language`:语言类型 - `domain`:所属领域 - `problem`:问题描述 - `reasoning_steps`:推理步骤序列 - `final_answer`:最终答案 - `misconception_corrected`:是否已纠正认知误区的标记 ## 示例 json { "language": "hinglish", "domain": "healthcare", "problem": "Mujhe 3 din se fever hai, kya antibiotics leni chahiye?", "reasoning_steps": [ "Check duration of fever", "Differentiate viral vs bacterial infection", "Antibiotics only work for bacterial infections" ], "final_answer": "Mild fever me antibiotics zaroori nahi hoti. Doctor advice lena better hai.", "misconception_corrected": true }