CG-Bench
收藏资源简介:
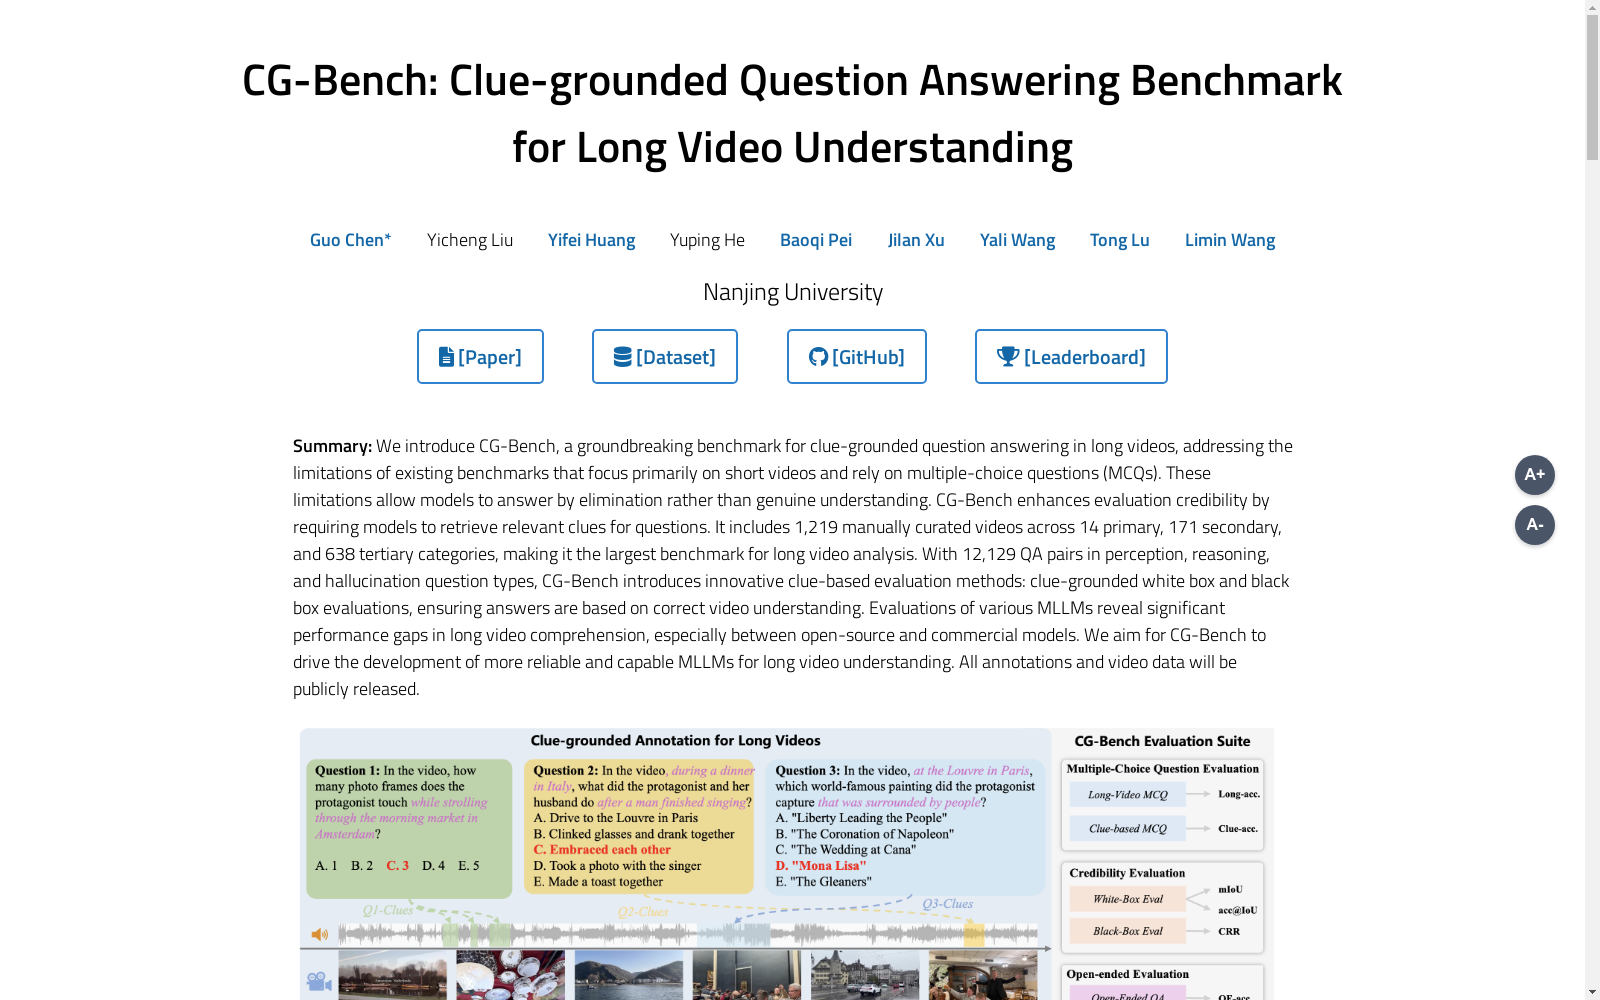
CG-Bench是一个专门为长视频理解设计的线索导向问答基准数据集,由南京大学、上海人工智能实验室等机构创建。该数据集包含1219个精心筛选的长视频,分为14个主要类别、171个次级类别和638个三级类别,共有12,129个问答对,涵盖感知、推理和幻觉三种主要问题类型。数据集的创建过程包括视频收集、问答线索标注和质量审查迭代,确保了数据集的高质量和多样性。CG-Bench旨在评估多模态大语言模型在长视频理解中的表现,特别是模型是否能够基于视频中的线索生成正确答案,从而推动更可靠和高效的多模态模型的发展。
CG-Bench is a clue-oriented question answering benchmark dataset specifically designed for long-form video understanding, developed by institutions including Nanjing University and Shanghai AI Laboratory. This dataset comprises 1219 carefully curated long videos, which are classified into 14 primary categories, 171 secondary categories and 638 tertiary categories, with a total of 12,129 question-answer pairs covering three main question types: perception, reasoning and hallucination. The dataset construction process includes video collection, question-answering clue annotation and iterative quality review, which ensures the high quality and diversity of the dataset. CG-Bench aims to evaluate the performance of multimodal large language models in long-form video understanding, particularly whether the models can generate accurate answers based on the clues in the videos, thereby advancing the development of more reliable and efficient multimodal models.