WHODUNIT
收藏资源简介:
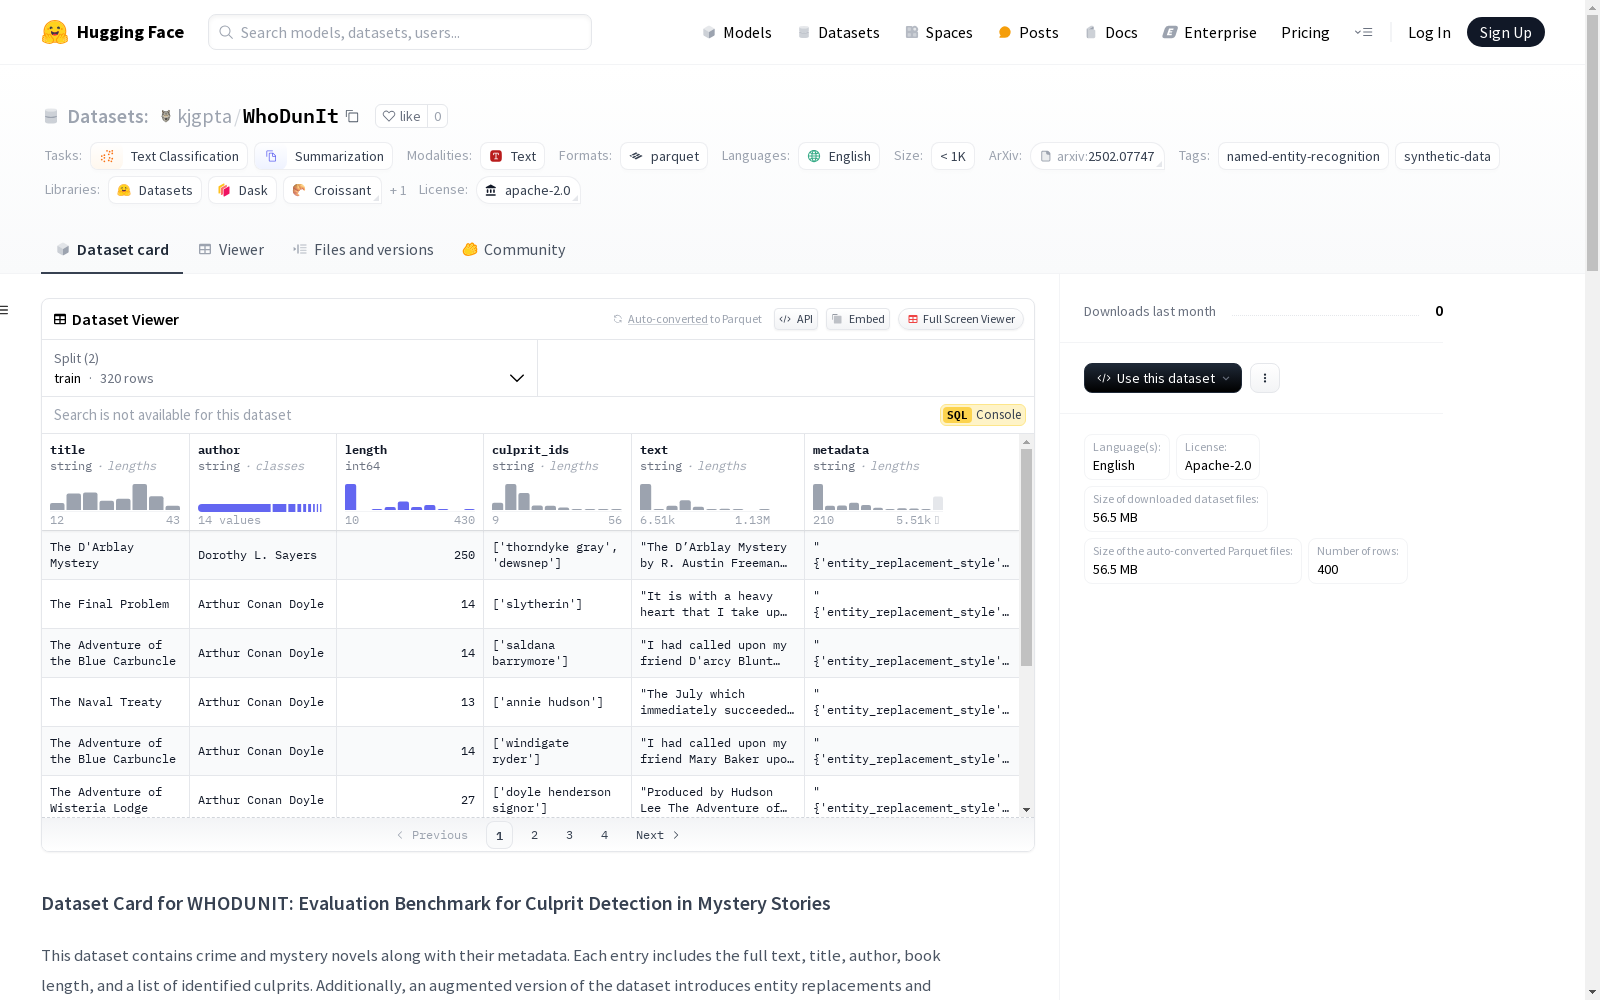
WHODUNIT数据集由BITS Pilani的研究人员构建,旨在评估大型语言模型在叙事背景下的推理能力。该数据集由公开领域的侦探和悬疑小说组成,挑战模型在阅读故事后识别犯罪者。数据集通过不同的角色命名增广,如原名、名字交换、以及替换为知名实体等,来评估模型的鲁棒性。数据集涵盖了不同作者和叙事风格的作品,保证了叙事结构和推理风格的多样性,适用于推理和长篇叙事理解的任务。
The WHODUNIT dataset was constructed by researchers from BITS Pilani, with the aim of evaluating the reasoning capabilities of large language models in narrative contexts. This dataset consists of detective and mystery novels from the public domain, challenging models to identify the perpetrator after reading the full story. The dataset is augmented via multiple character naming strategies, including original names, name swaps, and replacement with well-known entities, to assess model robustness. It covers works from different authors with diverse narrative styles, ensuring variety in narrative structures and reasoning patterns, making it applicable to tasks related to reasoning and long-form narrative comprehension.