
OK-VQA
收藏资源简介:
OK-VQA是一个专为视觉问答设计的知识基准数据集,由卡内基梅隆大学等机构创建。该数据集包含超过14,000个问题,这些问题不能仅通过图像内容回答,需要依赖外部知识资源。数据集涵盖多种知识类别,如科学、历史和体育,旨在评估模型在结合视觉识别与外部知识进行推理的能力。OK-VQA是迄今为止最大的专注于知识基础视觉问答的自然图像数据集,为研究者提供了新的研究途径。
OK-VQA is a knowledge-based benchmark dataset specifically designed for visual question answering (VQA), developed by institutions including Carnegie Mellon University. It contains over 14,000 questions that cannot be answered solely based on the content of the input image, and requires leveraging external knowledge resources. The dataset covers a wide range of knowledge categories such as science, history, and sports, aiming to evaluate the capability of models to perform reasoning by combining visual recognition and external knowledge. To date, OK-VQA is the largest natural image dataset focused on knowledge-based visual question answering, providing new research avenues for researchers.
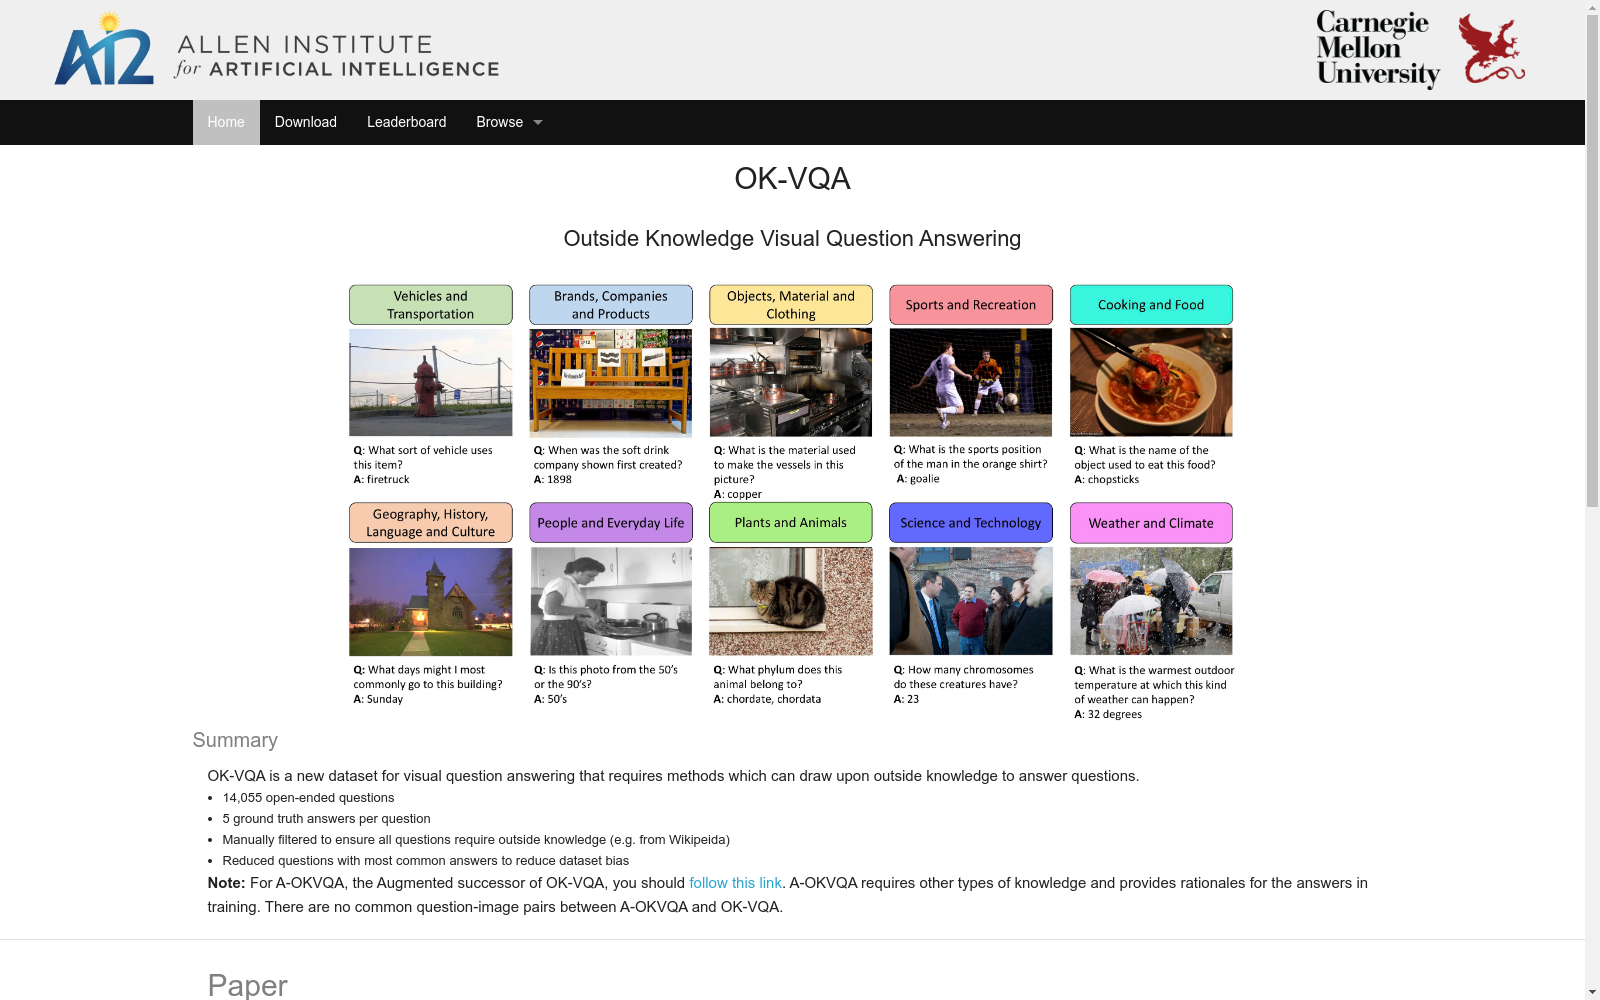
- OK-VQA数据集首次发表,由阿里达摩院和新加坡国立大学联合提出,旨在通过开放域知识增强视觉问答任务。
- OK-VQA数据集首次应用于视觉问答模型的评估,推动了多模态学习领域的发展。
- OK-VQA数据集被广泛用于研究多模态融合技术,特别是在结合图像和文本信息进行复杂推理方面。
- OK-VQA数据集成为视觉问答领域的重要基准,促进了相关算法的创新和性能提升。
- 1OK-VQA: A Visual Question Answering Benchmark Requiring External KnowledgeUniversity of North Carolina at Chapel Hill, University of Michigan, University of Washington · 2019年
- 2OK-VQA: A Benchmark for Open-Knowledge Visual Question AnsweringUniversity of North Carolina at Chapel Hill, University of Michigan, University of Washington · 2020年
- 3Exploring the Limits of Transfer Learning with a Unified Text-to-Text TransformerGoogle Research, Carnegie Mellon University · 2020年
- 4LXMERT: Learning Cross-Modality Encoder Representations from TransformersUniversity of North Carolina at Chapel Hill, University of Washington · 2019年
- 5GQA: A New Dataset for Real-World Visual Reasoning and Compositional Question AnsweringUniversity of California, Berkeley, University of Toronto · 2019年


