
ViLLA-MMBench
收藏资源简介:
ViLLA-MMBench是一个用于下一代大型语言模型增强的多模态电影推荐研究的基准测试套件。该套件利用了广泛使用的MovieLens和MMTF-14K数据集,整合并校准了来自三个模态(音频、视觉和文本)的项级密集嵌入。它还自动使用最先进的LLM(例如OpenAI GPT)增强缺失或稀疏的项元数据,为数千部电影生成高质量的摘要。所有文本(原始或LLM增强)都使用可配置的密集编码器嵌入,生成多个现成的嵌入集(OpenAI Ada、LLaMA-2、Sentence-T5)。此外,ViLLA-MMBench的管道支持可互换的早期、中期和晚期融合运算符(连接、PCA、CCA和排名聚合),并公开了多种骨干推荐器(MF、VAECF、VBPR、AMR、VMF),用于消融研究。所有实验参数(包括数据集分割、模态变体、融合策略和LLM类型)都通过单个YAML文件声明性地指定,以便进行透明、版本控制的实验。评估是全面的,不仅涵盖准确性(召回率、nDCG),还涵盖准确性以外的指标:冷启动率、覆盖率、新颖性、多样性和公平性,支持严格的多指标基准测试。实验表明,基于LLM的文本增强和密集嵌入提取直接提高了冷启动和覆盖性能,特别是当强大的文本表示与视听描述符融合时。系统性的基准测试揭示了哪些嵌入和融合组合是通用的(跨模型表现良好)以及哪些是特定于骨干模型或指标的。总的来说,开源代码、嵌入和配置模板使其成为在多模态推荐系统中进行可重复、可扩展和公平比较的强大基础,并为在大规模电影推荐中原则性地集成生成式AI迈出了明确的一步。所有资源都可在https://recsys-lab.github.io/ViLLA-MMBench 公开获取。
ViLLA-MMBench is a benchmark suite for next-generation large language model-augmented multimodal movie recommendation research. This suite leverages the widely adopted MovieLens and MMTF-14K datasets, integrating and calibrating item-level dense embeddings from three modalities: audio, visual, and text. It also automatically augments missing or sparse item metadata using state-of-the-art LLMs (e.g., OpenAI GPT) to generate high-quality summaries for thousands of movies. All text (either original or LLM-augmented) is embedded using configurable dense encoders, yielding multiple pre-built embedding sets including OpenAI Ada, LLaMA-2, and Sentence-T5. Furthermore, the ViLLA-MMBench pipeline supports interchangeable early, middle, and late fusion operators (concatenation, PCA, CCA, and rank aggregation), and exposes a variety of backbone recommenders (MF, VAECF, VBPR, AMR, VMF) for ablation studies. All experimental parameters, including dataset splits, modality variants, fusion strategies, and LLM types, are declaratively specified via a single YAML file to enable transparent, version-controlled experiments. The evaluation is comprehensive, covering not only accuracy-related metrics (recall, nDCG) but also metrics beyond accuracy: cold start rate, coverage, novelty, diversity, and fairness, supporting rigorous multi-metric benchmarking. Experiments demonstrate that LLM-based text augmentation and dense embedding extraction directly improve cold start and coverage performance, especially when powerful text representations are fused with audio-visual descriptors. Systematic benchmarking reveals which embedding and fusion combinations are generalizable (perform well across models) and which are specific to backbone models or metrics. Overall, the open-source code, embeddings, and configuration templates make it a robust foundation for reproducible, scalable, and fair comparisons in multimodal recommendation systems, taking a clear step towards the principled integration of generative AI in large-scale movie recommendation. All resources are publicly available at https://recsys-lab.github.io/ViLLA-MMBench.
ViLLA-MMBench 数据集概述
数据集简介
- 名称:ViLLA-MMBench
- 类型:多模态电影推荐基准测试套件
- 用途:为LLM增强的多模态电影推荐提供统一基准框架
- 模态支持:视觉、音频和文本模态
项目结构
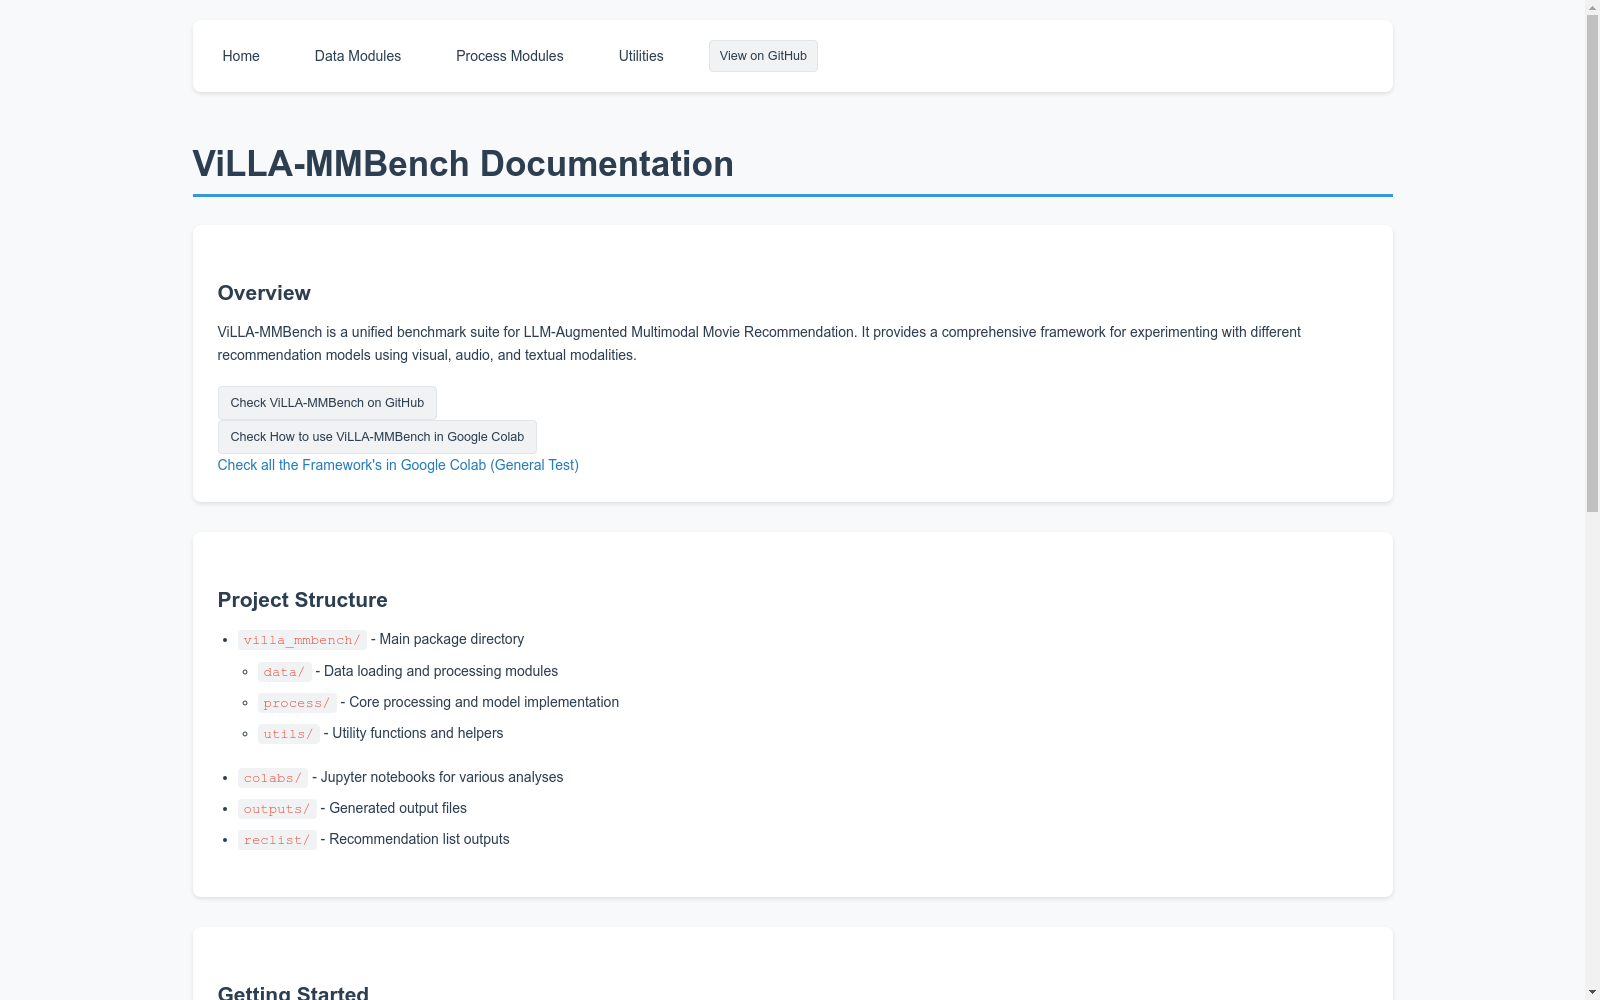
villa_mmbench/- 主包目录data/- 数据加载和处理模块process/- 核心处理和模型实现utils/- 实用函数和辅助工具
colabs/- 各种分析的Jupyter笔记本outputs/- 生成的输出文件reclist/- 推荐列表输出
数据处理模块
- 文本处理(基于LLM)
- 视觉特征(AVF、CNN)
- 音频特征(BLF、i-vector)
支持模型
- 协同过滤(CF)
- 视觉贝叶斯个性化排序(VBPR)
- 对抗性多媒体推荐(AMR)
- 视觉矩阵分解(VMF)
- 变分自编码器CF(VAECF)
快速开始
bash
克隆仓库
git clone git@github.com:RecSys-lab/ViLLA-MMBench.git
创建并激活虚拟环境
python -m venv venv .venvScriptsactivate # Windows source venv/bin/activate # Linux/Mac
安装包
pip install -e .
相关资源
- GitHub地址:https://github.com/RecSys-lab/ViLLA-MMBench
- Google Colab使用指南:https://colab.research.google.com
- 框架通用测试:https://colab.research.google.com
- 1ViLLA-MMBench: A Unified Benchmark Suite for LLM-Augmented Multimodal Movie Recommendation意大利巴里理工大学电子与信息工程学院 & 卢森堡大学跨学科安全、可靠性与信任研究中心 · 2025年


