llama-3.1-tulu-3-405b-preference-mixture-filter-datecutoff
收藏资源简介:
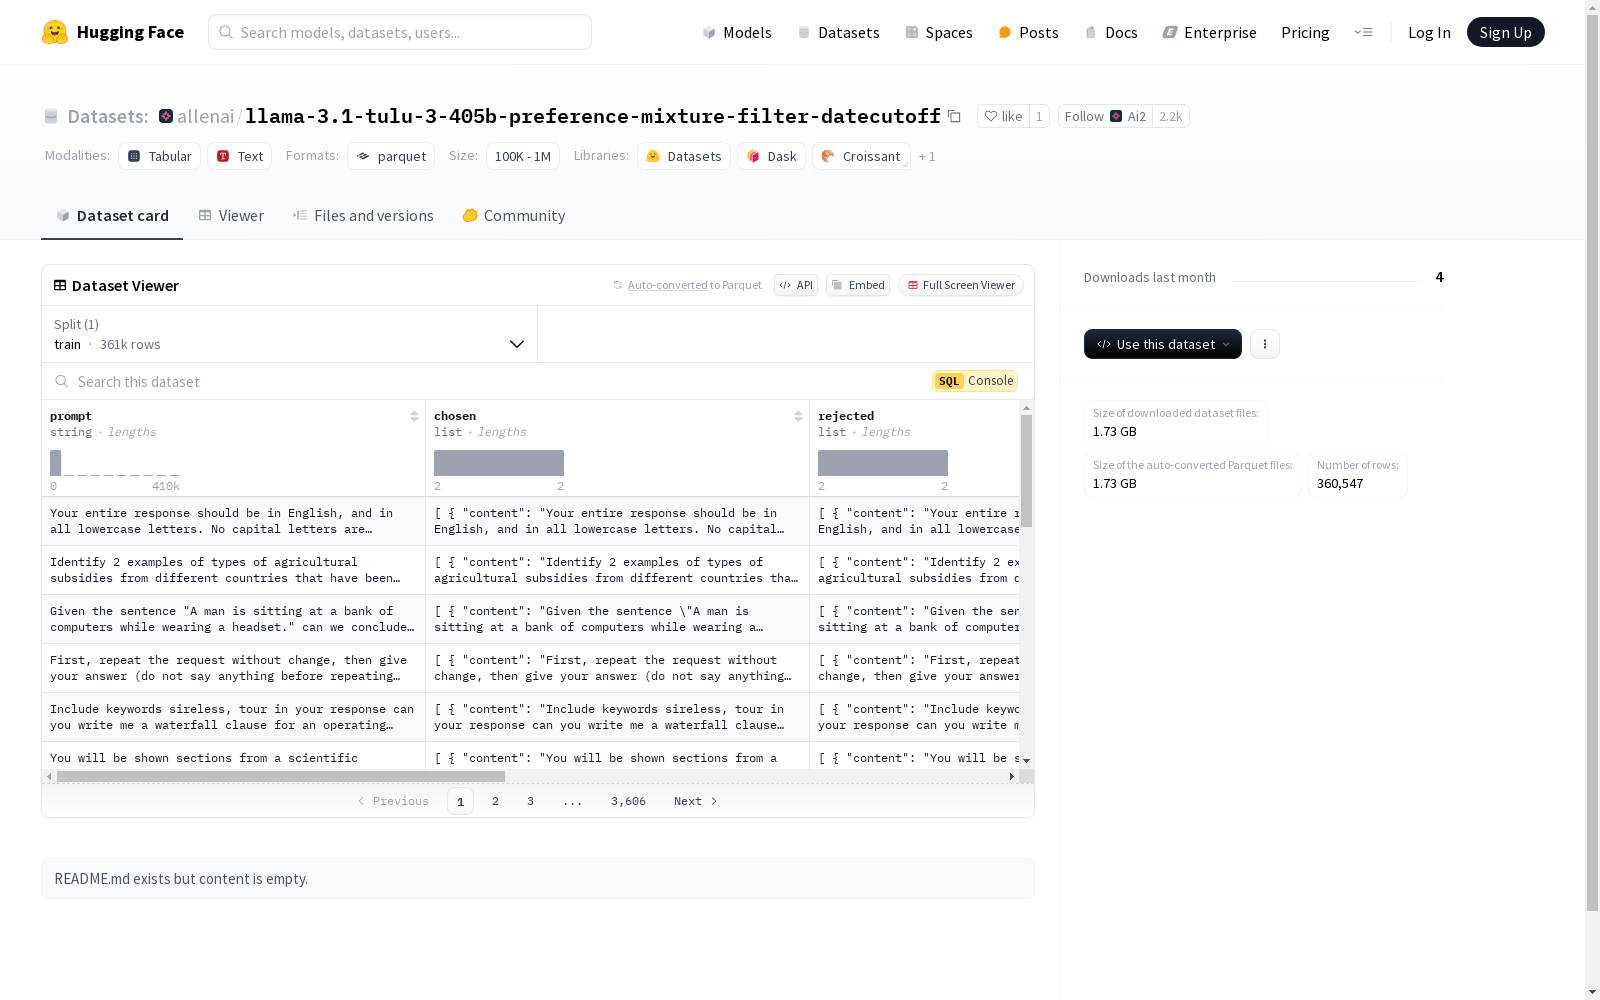
这是一个文本选择和评估的数据集,包含提示文本(prompt)、选中的文本内容及其角色(chosen)、被拒绝的文本内容及其角色(rejected)、选中文本的评分(chosen_rating)、拒绝文本的评分(rejected_rating)、选中文本的模型(chosen_model)、拒绝文本的模型(rejected_model)、数据源(source)和唯一标识符(id)。数据集分为训练集,示例数量为360,547,大小为3,315,923,420.58596字节。
This is a dataset for text selection and evaluation. It includes prompt text (prompt), selected text content and its corresponding role (chosen), rejected text content and its corresponding role (rejected), the rating score of the chosen text (chosen_rating), the rating score of the rejected text (rejected_rating), the model corresponding to the chosen text (chosen_model), the model corresponding to the rejected text (rejected_model), data source (source) and unique identifier (id). The dataset is split into a training set with 360,547 examples and a total size of 3,315,923,420.58596 bytes.