BWB
收藏资源简介:
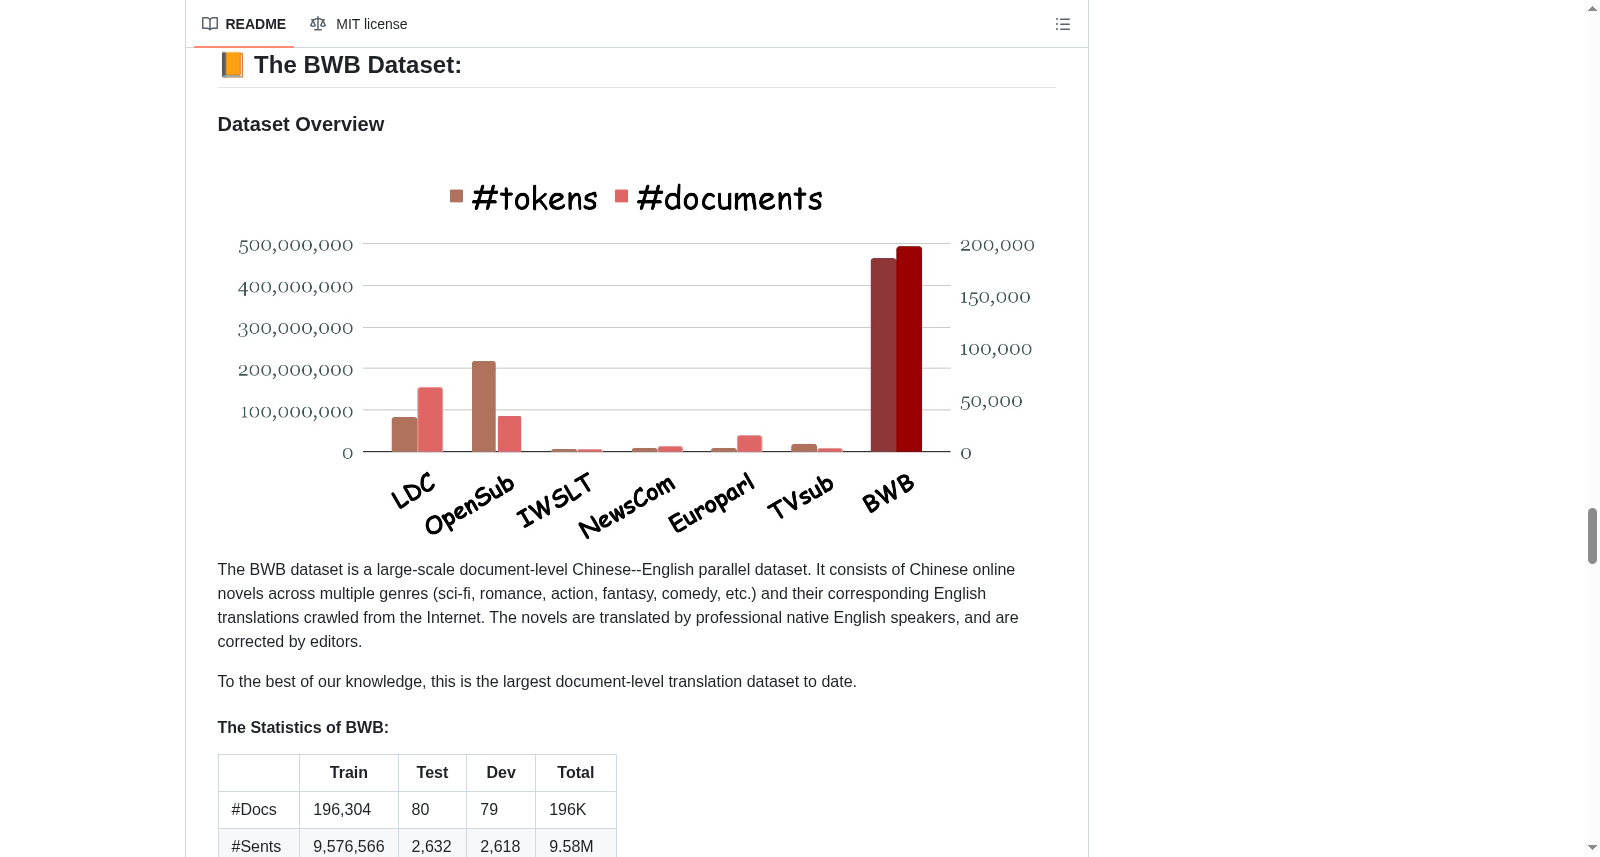
该数据集是一个大规模的文档级中英平行语料库,涵盖了来自互联网的多种类型的中文网络小说及其对应的英文翻译。该数据集解决了以往研究中缺乏具有人类翻译的广泛文学文本数据集的问题,并允许对翻译中的风格特征进行比较分析。它是开源BWB数据集的一个子集,具体包含了五个最受欢迎子体裁中的25本书,每本书选取了100个大小为3KB的片段。此外,该数据集的任务是对比Gpt-4翻译与人类翻译之间的差异。
This dataset is a large-scale document-level Chinese-English parallel corpus covering various types of Chinese online novels sourced from the Internet and their corresponding English translations. It addresses the gap in existing research where large-scale literary text datasets with human translations are scarce, and enables comparative analysis of stylistic features in translations. It is a subset of the open-source BWB dataset, specifically containing 25 books from the five most popular sub-genres, with 100 3KB segments selected from each book. Additionally, the task of this dataset is to compare the differences between GPT-4 translations and human translations.