npm-ai-agent-mcp-packages-enriched
收藏资源简介:
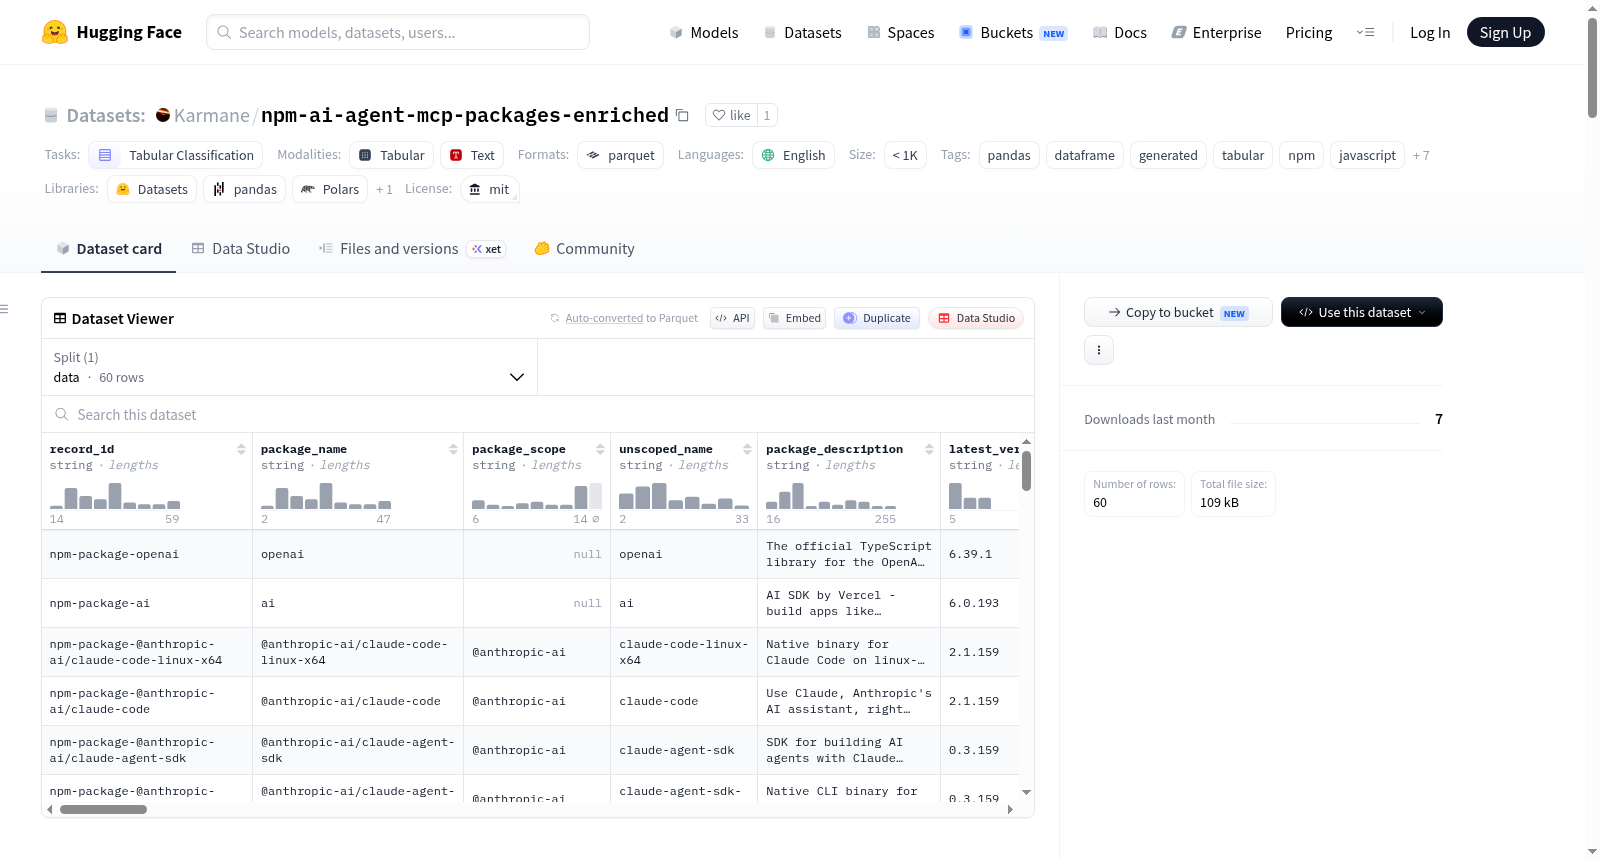
npm AI Agent和MCP包增强数据集整合了npm注册表中与AI代理、模型上下文协议(MCP)、编排和模型工具相关的公共包的注册表元数据和下载记录,形成一个分析就绪的数据框。该数据集旨在简化开发者工具市场研究、生态系统映射、依赖发现、包筛选和AI工具分析,避免了手动合并搜索结果的繁琐过程。数据集包含60个样本(行),每个样本代表一个通过重叠npm搜索词发现的包,并提供了56个丰富的特征字段(列)。核心内容包括:包标识信息(如包名、作用域、描述、版本、许可证)、发布信息(发布时间、维护者数量、包龄、是否近期发布)、下载指标(周下载量、月下载量、下载排名和层级)、搜索相关信息(匹配的搜索词、搜索排名、搜索分数)、技术特征(依赖项数量、是否包含CLI二进制文件、是否包含TypeScript类型定义、导出信息、Node引擎要求)、仓库和主页链接、生态系统分类(如开发者工具/CLI、MCP基础设施、AI工具/集成、代理框架),以及AI相关信号(提供商标识、是否包含核心AI信号、MCP信号、代理信号、SDK信号、商业化术语)。数据以Parquet格式存储,适用于表格分类等任务,为分析npm生态系统中AI和MCP相关工具包的流行度、技术栈、维护活跃度和市场趋势提供了结构化基础。
The npm AI Agent and MCP Package Enhanced Dataset integrates registry metadata and download records of public packages related to AI agents, Model Context Protocol (MCP), orchestration, and model tools from the npm registry into an analysis-ready data frame. This dataset aims to simplify developer tool market research, ecosystem mapping, dependency discovery, package filtering, and AI tool analysis, avoiding the tedious process of manually merging search results. It contains 60 samples (rows), each representing a package discovered through overlapping npm search terms, with 56 rich feature columns. Core content includes: package identification information (e.g., package name, scope, description, version, license), release information (release time, number of maintainers, package age, whether recently released), download metrics (weekly downloads, monthly downloads, download rank and tier), search-related information (matched search terms, search rank, search score), technical features (number of dependencies, inclusion of CLI binaries, TypeScript type definitions, export information, Node engine requirements), repository and homepage links, ecosystem classification (e.g., developer tools/CLI, MCP infrastructure, AI tools/integration, agent frameworks), and AI-related signals (provider identification, inclusion of core AI signals, MCP signals, agent signals, SDK signals, commercialization terms). Data is stored in Parquet format, suitable for tasks like tabular classification, providing a structured foundation for analyzing the popularity, tech stack, maintenance activity, and market trends of AI and MCP-related tool packages in the npm ecosystem.
数据集概述:npm AI Agent and MCP Packages Enriched Dataset
该数据集是一个经过富化的、面向AI Agent、MCP(模型上下文协议)、编排及模型工具类npm包的表格数据集,整合了公共npm注册表信息和下载记录,以便于开发者工具市场研究、生态系统映射和依赖发现。
数据集基本信息
- 语言: 英语 (en)
- 许可证: MIT (mit)
- 访问控制: 需要付费许可,通过链接购买后申请访问
- 任务类别: 表格分类 (tabular-classification)
- 数据集大小: n<1K (60行)
- 配置: 一个默认配置 (
default),数据文件为data/data.parquet
数据集结构
- 总行数: 60
- 总列数: 56
- 数据拆分:
data: 60行
数据列及描述(部分关键列)
| 列名 | 数据类型 | 描述 |
|---|---|---|
record_id |
字符串 | 基于npm包名的唯一稳定标识符 |
package_name |
字符串 | 规范的npm包名 |
package_scope |
字符串 | 有作用域的包的前缀(如 @modelcontextprotocol) |
unscoped_name |
字符串 | 去除作用域后的包名 |
package_description |
字符串 | npm元数据中的公开包描述 |
latest_version |
字符串 | npm注册表报告的最新版本号 |
license_name |
字符串 | 包元数据中的许可证标识符 |
author_name |
字符串 | 包作者名称 |
publisher_name |
字符串 | 最新版本的发布者用户名 |
maintainer_count |
整数 | 维护者数量 |
published_at |
日期时间字符串 | 最新版本的发布时间戳 |
first_published_at |
日期时间字符串 | 包在npm注册表中的首次创建时间戳 |
package_age_days |
整数 | 自首次发布至收集时间的总天数 |
days_since_publish |
整数 | 自最新版本发布至收集时间的总天数 |
is_recently_published_90d |
布尔值 | 最新版本是否在最近90天内发布 |
is_deprecated |
布尔值 | 最新版本是否被标记为弃用 |
weekly_downloads |
整数 | 官方npm上周下载量 |
monthly_downloads |
整数 | 官方npm上月下载量 |
search_score |
浮点数 | 跨匹配搜索词的最大npm搜索得分 |
matched_search_terms |
字符串 | 以管道符分隔的、返回该包的搜索词列表 |
matched_search_term_count |
整数 | 返回该包的不同搜索词数量 |
primary_search_term |
字符串 | 作为包主要来源标签的首个匹配搜索词 |
best_search_rank |
整数 | 所有匹配搜索词中的最佳搜索排名 |
mean_search_rank |
浮点数 | 所有匹配搜索词的平均搜索排名 |
keywords |
字符串 | 以管道符分隔的包关键词 |
keyword_count |
整数 | 包关键词数量 |
dependency_count |
整数 | 最新版本的生产依赖数量 |
dev_dependency_count |
整数 | 开发依赖数量 |
peer_dependency_count |
整数 | 对等依赖数量 |
bin_command_count |
整数 | CLI二进制命令数量 |
has_cli_bin |
字符串 | 是否有CLI二进制文件 |
has_typescript_types |
字符串 | 是否包含TypeScript类型声明 |
has_exports |
字符串 | 是否有导出声明 |
repository_url |
字符串 | 仓库URL |
ecosystem_segment |
字符串 | 生态系统分类(如 Developer Tooling / CLI, MCP Infrastructure, Agent Framework) |
provider_mentions |
字符串 | 提及的AI提供商名称(如 OpenAI, Anthropic, Claude, Gemini) |
has_core_ai_signal |
字符串 | 是否包含核心AI信号 |
has_mcp_signal |
字符串 | 是否包含MCP信号 |
has_agent_signal |
字符串 | 是否包含Agent信号 |
has_sdk_signal |
字符串 | 是否包含SDK信号 |
commercial_readiness |
字符串 | 商业化准备程度(如 high) |
last_collected_at |
日期时间字符串 | 最后一次数据收集时间 |
monthly_download_rank |
整数 | 月下载量排名 |
weekly_download_rank |
整数 | 周下载量排名 |
downloads_tier |
字符串 | 下载量等级(如 1m+) |
数据预览(前5行示例)
包名 (package_name) |
描述 | 周下载量 | 生态分类 | 提供商提及 | MCP信号 |
|---|---|---|---|---|---|
openai |
OpenAI API 的官方TypeScript库 | 23,430,731 | Developer Tooling / CLI | OpenAI | 否 |
ai |
Vercel 的 AI SDK,支持多种大模型 | 12,944,419 | MCP Infrastructure | OpenAI, Anthropic, Claude, Gemini | 是 |
@anthropic-ai/claude-code-linux-x64 |
Claude Code 的 Linux x64 原生二进制 | 9,308,309 | AI Utility / Integration | Anthropic, Claude | 否 |
@anthropic-ai/claude-code |
在终端中使用 Claude | 8,661,516 | Developer Tooling / CLI | Anthropic, Claude | 否 |
@anthropic-ai/claude-agent-sdk |
构建AI Agent的SDK | 7,066,332 | Agent Framework | Anthropic, Claude | 否 |
数据集用途
该数据集适用于:开发者工具市场研究、生态系统映射、依赖发现、包筛选、AI工具分析。