CentificAIResearch/BA-Agent-Bench
收藏资源简介:
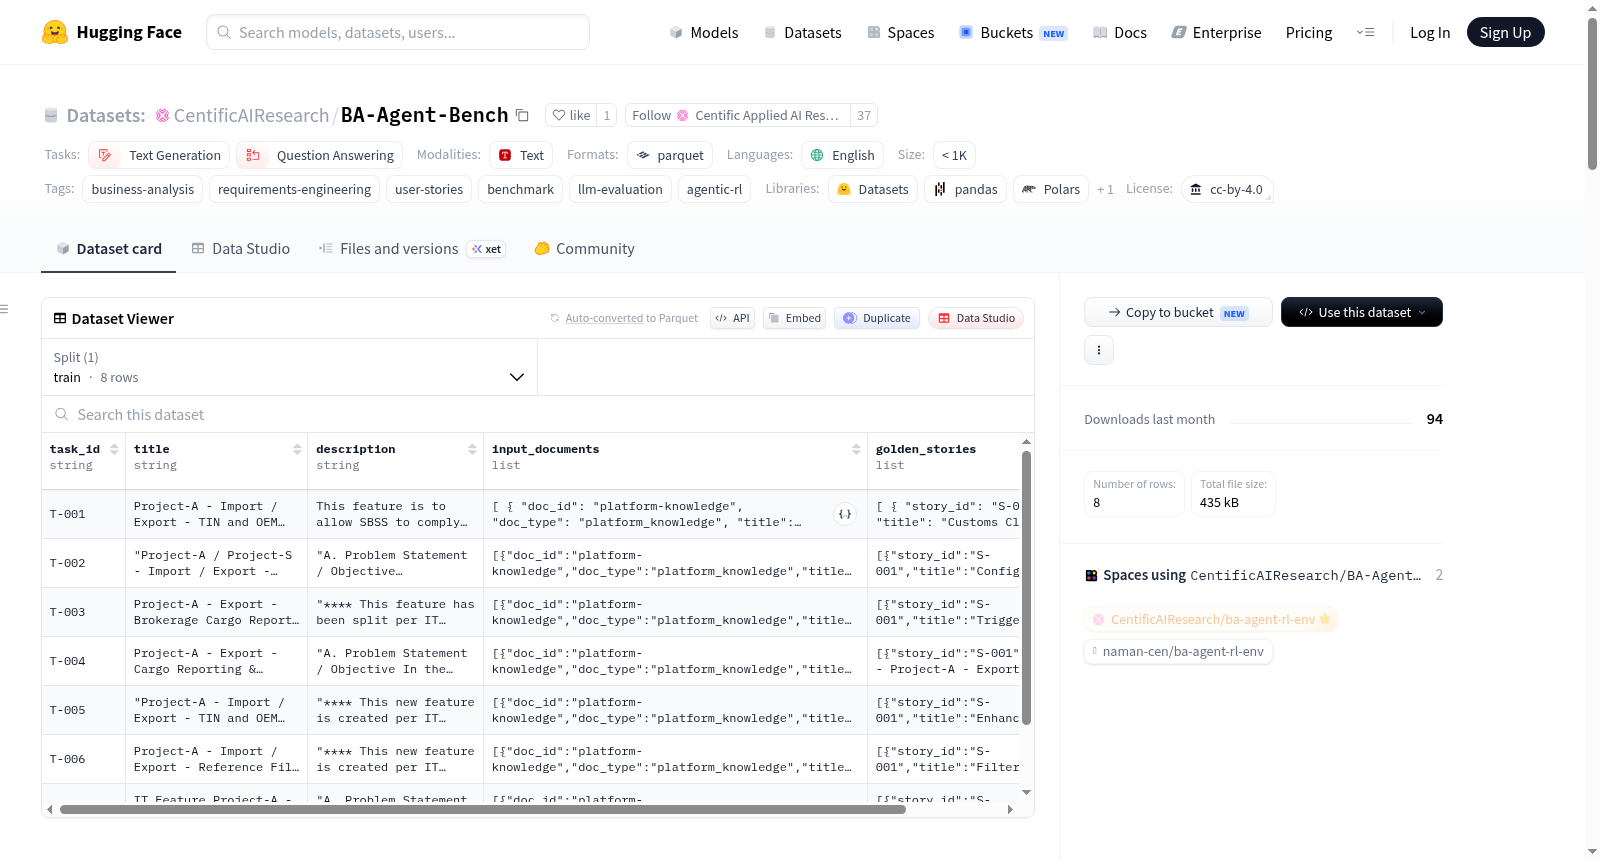
--- license: cc-by-4.0 language: - en size_categories: - n<1K task_categories: - text-generation - question-answering tags: - business-analysis - requirements-engineering - user-stories - benchmark - llm-evaluation - agentic-rl configs: - config_name: default data_files: train.parquet --- # BA-Agent-Bench (Subset) **BA Agent Bench** — purpose-built benchmark for evaluating **LLMs and multi-agent systems on enterprise requirements generation capability**. Measures whether a model or agent can take real production work-item specs and produce BA-grade user stories with acceptance criteria, matching the decomposition and rigor of certified Business Analysts. The full benchmark evaluates 8 systems (7 frontier LLMs + Centific BA Toolkit pipeline) on 7 enterprise features against 119 ground-truth user stories authored by certified Business Analysts. Composite score across **Alignment (35%) · Coherence (24%) · Completeness (18%) · Compliance (10%) · Testability (9%) · Spec Quality (4%)**. This dataset card is an **8-feature stratified subset** of the benchmark — sampled for public release so practitioners can inspect inputs and gold standard. Full benchmark, leaderboard, and harness → **[centific.com/benchmark/agentic-rl/1#start](https://www.centific.com/benchmark/agentic-rl/1#start)**. --- ## Why BA-Agent-Bench? Existing BA / requirements-engineering benchmarks rely on toy specs or single-shot story generation. Real BA work has: - Multi-document source specs (main requirement + KB / reference docs) - Domain-rich decomposition: per-entity, per-workflow, per-stage stories - BA-authored gold standard with full acceptance criteria - 7 quality dimensions (alignment, coherence, completeness, testability, specification quality, trust, compliance) BA-Agent-Bench targets all of the above on **production work items from an enterprise import/export logistics platform**. --- ## Subset Composition This subset contains **8 features** covering a range of domains, document counts, and decomposition complexity: | task_id | docs | stories | domain | |---|---|---|---| | T-001 | 4 | 27 | Customs Client ID processing | | T-002 | 4 | 13 | Commencement configuration | | T-003 | 4 | 12 | Brokerage Cargo Reports | | T-004 | 4 | 17 | Cargo Reporting & Declaration | | T-005 | 4 | 18 | TIN / OEM Client ID re-issue | | T-006 | 4 | 12 | Reference File Processing | | T-007 | 4 | 20 | OEM Client ID app improvement | | T-008 | 3 | 8 | Shipment-level Underbond | **Total:** 31 source documents · 127 golden stories · 8 distinct domains --- ## Schema Each row has the following columns: | Column | Type | Description | |---|---|---| | `task_id` | str | Original work-item identifier | | `title` | str | Feature title | | `description` | str | Feature description, scope, and business value | | `input_documents` | list[dict] | Source requirement docs: `{filename, content}` | | `golden_stories` | list[dict] | BA-authored user stories with acceptance criteria | ### `golden_stories` row | Field | Type | Description | |---|---|---| | `story_id` | str | Story identifier within feature | | `title` | str | Short story title | | `description` | str | Full "As a / I want / So that" narrative | | `acceptance_criteria` | str \| list[str] | Given/When/Then or free-text AC | | `story_points` | int | Effort estimate | | `state` | str | Workflow state when story was authored | --- ## How to Load ```python from datasets import load_dataset ds = load_dataset("CentificAIResearch/BA-Agent-Bench") print(ds["train"][0]) ``` Or read parquet directly: ```python import pandas as pd df = pd.read_parquet("hf://datasets/CentificAIResearch/BA-Agent-Bench/train.parquet") print(df.columns.tolist()) for _, row in df.iterrows(): print(row["task_id"], len(row["golden_stories"])) ``` --- ## Full Dataset & Related Resources This subset is drawn from a larger benchmark suite covering 26+ enterprise features with full evaluation infrastructure (LLM-judge metrics, multi-model leaderboard, automated scoring harness). - **Benchmark portal:** [centific.com/benchmark/agentic-rl/1#start](https://www.centific.com/benchmark/agentic-rl/1#start) --- ## License CC-BY-4.0 — free to use with attribution. ## Citation ```bibtex @dataset{ba_agent_bench_2026, title = {{BA-Agent-Bench}: Benchmark for {BA}-grade Story Generation and Multi-agent {BA} Pipelines}, author = {Centific AI Research}, year = {2026}, publisher = {HuggingFace}, url = {https://huggingface.co/datasets/CentificAIResearch/BA-Agent-Bench} } ```
BA-Agent-Bench (Subset) is a purpose-built benchmark for evaluating LLMs and multi-agent systems on enterprise requirements generation capability. It measures whether a model or agent can take real production work-item specs and produce BA-grade user stories with acceptance criteria, matching the decomposition and rigor of certified Business Analysts. The subset contains 8 features covering domains such as Customs Client ID processing, Cargo Reporting & Declaration, and Reference File Processing, with a total of 31 source documents and 127 golden stories authored by certified Business Analysts. Each row includes task_id, title, description, input_documents (a list of source requirement documents), and golden_stories (a list of user stories with fields like story_id, title, description, acceptance_criteria, story_points, and state). This subset is sampled from a larger benchmark suite for public release, allowing practitioners to inspect inputs and gold standards. It is designed for NLP tasks like text-generation and question-answering, supporting enterprise business analysis, requirements engineering, and agent evaluation.