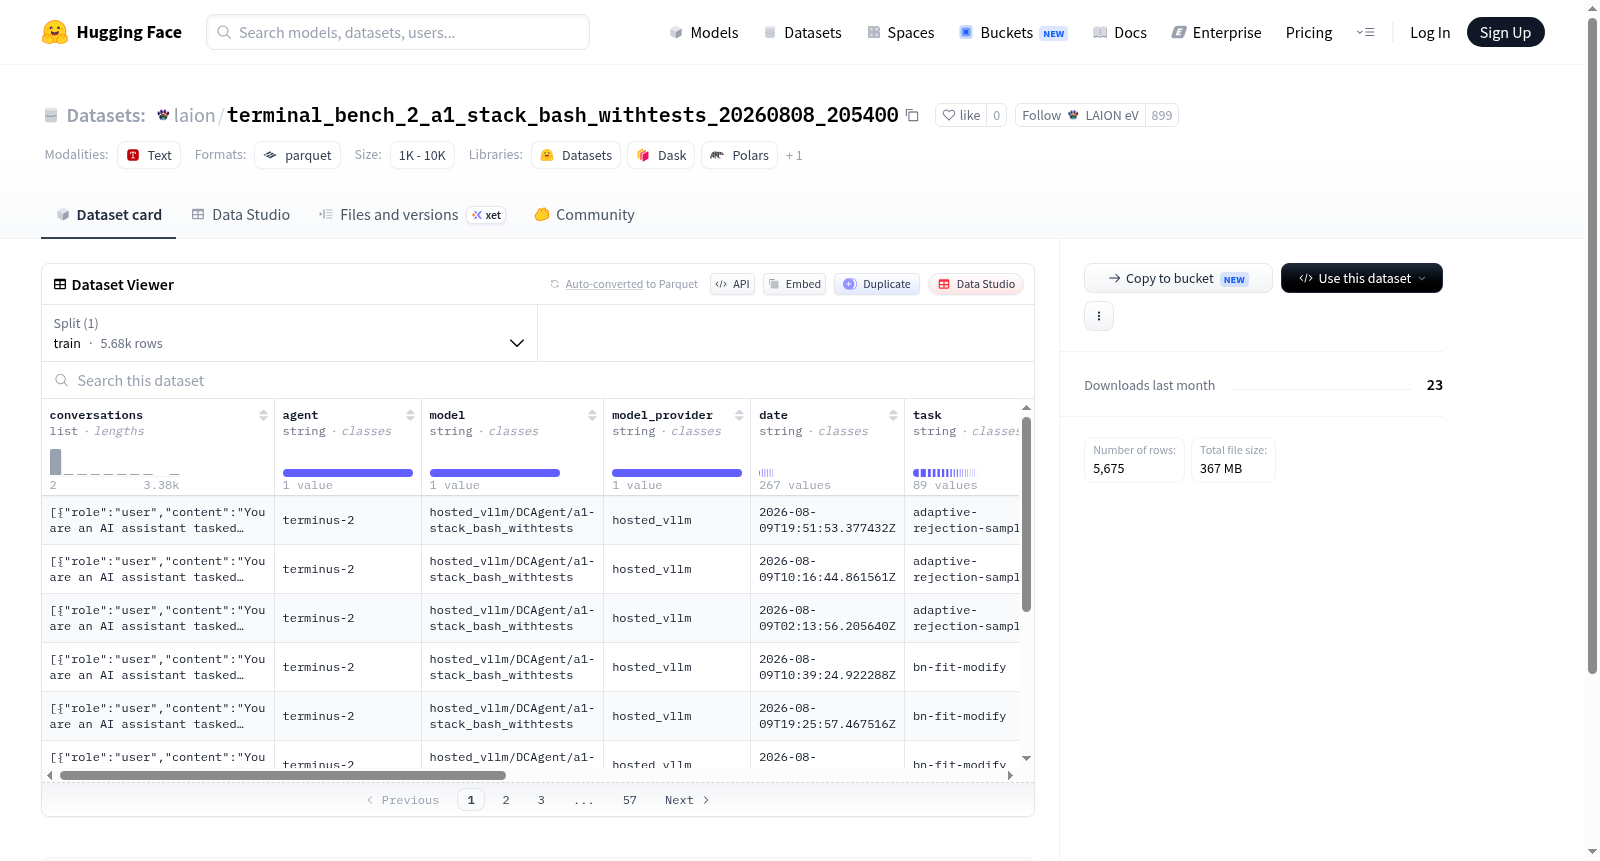
terminal_bench_2_a1_stack_bash_withtests_20260808_205400
收藏资源简介:
该数据集包含多轮对话样本,每条样本包含对话内容(conversations,由角色和文本组成)、代理标识(agent)、模型名称(model)、模型提供商(model_provider)、日期(date)、任务(task)、轮次(episode)、运行ID(run_id)、试验名称(trial_name)、结果(result)、验证器输出(verifier_output)以及追踪来源(trace_source)。数据集共包含5675个训练样本,总大小约555MB。适用于对话系统评估、代理行为分析、模型性能追踪等任务。
This dataset contains multi-turn dialogue samples. Each sample includes conversation content (conversations, composed of roles and texts), agent identifier (agent), model name (model), model provider (model_provider), date (date), task (task), episode (episode), run ID (run_id), trial name (trial_name), result (result), verifier output (verifier_output), and trace source (trace_source). The dataset contains a total of 5675 training samples, with a total size of approximately 555MB. It is suitable for tasks such as dialogue system evaluation, agent behavior analysis, and model performance tracking.
数据集详情:laion/terminal_bench_2_a1_stack_bash_withtests_20260808_205400
基本信息
- 数据集名称:terminal_bench_2_a1_stack_bash_withtests_20260808_205400
- 所属组织:LAION
- 数据集地址:https://huggingface.co/datasets/laion/terminal_bench_2_a1_stack_bash_withtests_20260808_205400
数据规模
| 项目 | 数值 |
|---|---|
| 数据集总大小 | 554,972,535 字节(约 529 MB) |
| 下载大小 | 366,499,686 字节(约 349 MB) |
| 训练集样本数 | 5,675 条 |
| 数据划分 | 仅包含 train 分割 |
数据特征(字段说明)
数据集包含以下 12 个字段:
- conversations(对话内容)— 列表类型,包含两个子字段:
role(角色):字符串类型content(内容):字符串类型
- agent(智能体):字符串类型
- model(模型):字符串类型
- model_provider(模型提供方):字符串类型
- date(日期):字符串类型
- task(任务):字符串类型
- episode(回合):字符串类型
- run_id(运行标识):字符串类型
- trial_name(试验名称):字符串类型
- result(结果):字符串类型
- verifier_output(验证器输出):字符串类型
- trace_source(轨迹来源):字符串类型
数据用途
该数据集用于终端基准测试(Terminal Bench),涉及 Bash 命令执行场景,并包含测试验证环节。数据集中记录了智能体(agent)在多轮对话中执行任务的过程,包括模型信息、运行参数、任务结果及验证输出等元数据,适用于评估和训练终端操作相关的智能体模型。