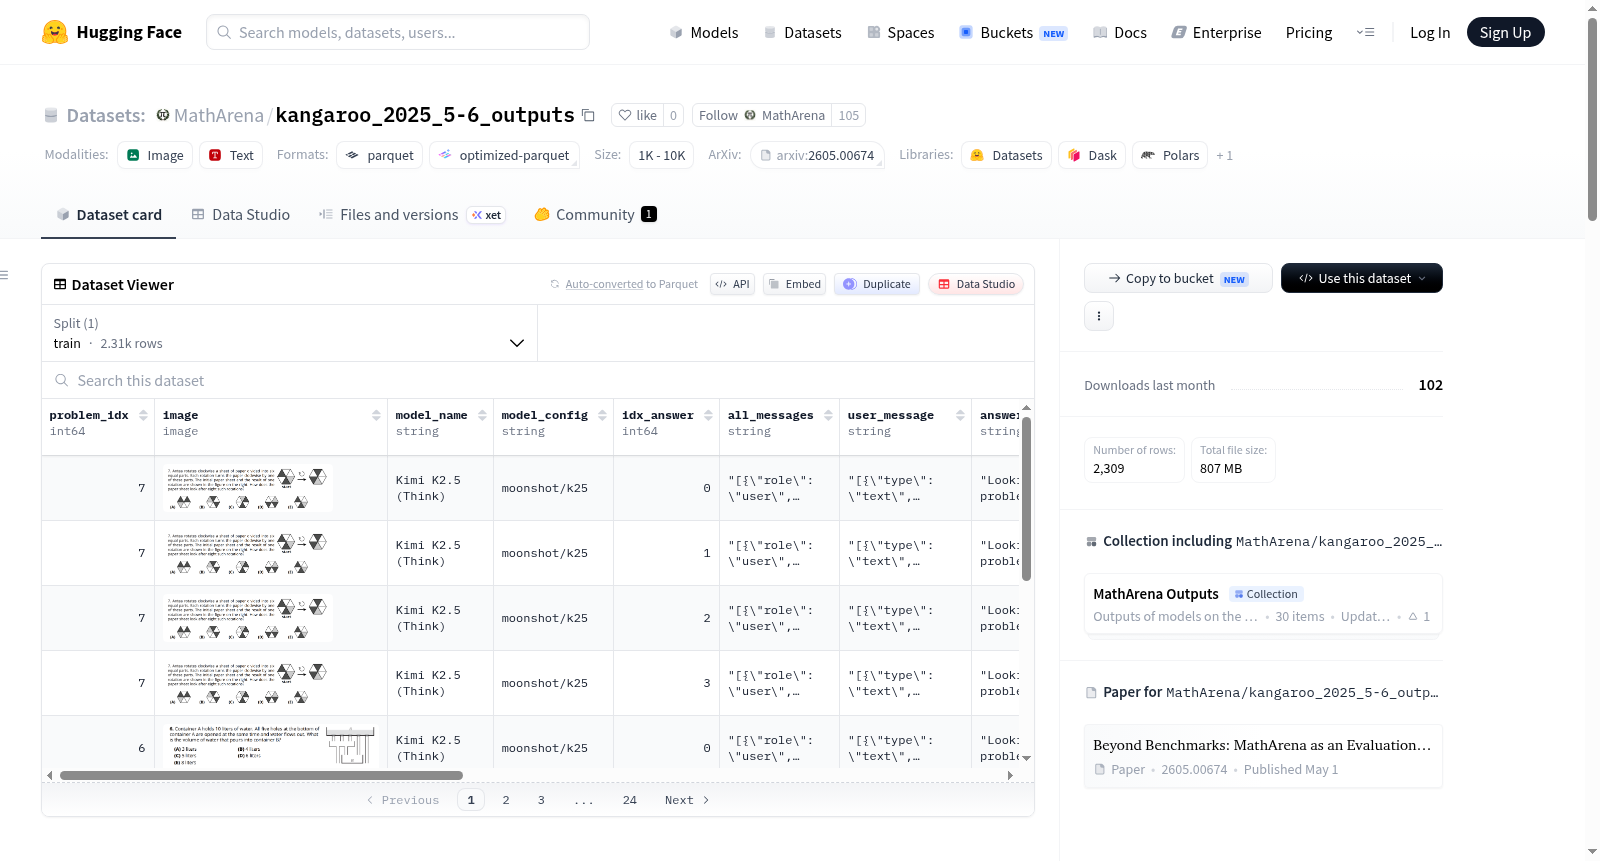
MathArena/kangaroo_2025_5-6_outputs
收藏资源简介:
--- dataset_info: features: - name: problem_idx dtype: int64 - name: image dtype: image - name: model_name dtype: string - name: model_config dtype: string - name: idx_answer dtype: int64 - name: all_messages dtype: string - name: user_message dtype: string - name: answer dtype: string - name: input_tokens dtype: int64 - name: output_tokens dtype: int64 - name: cost dtype: float64 - name: input_cost_per_tokens dtype: float64 - name: output_cost_per_tokens dtype: float64 - name: source dtype: float64 - name: history dtype: string - name: gold_answer dtype: string - name: parsed_answer dtype: string - name: correct dtype: bool splits: - name: train num_bytes: 878916723 num_examples: 2309 download_size: 806697002 dataset_size: 878916723 configs: - config_name: default data_files: - split: train path: data/train-* --- dataset_info: features: - name: problem_idx dtype: int64 - name: image dtype: image - name: model_name dtype: string - name: model_config dtype: string - name: idx_answer dtype: int64 - name: user_message dtype: string - name: answer dtype: string - name: input_tokens dtype: int64 - name: output_tokens dtype: int64 - name: cost dtype: float64 - name: input_cost_per_tokens dtype: float64 - name: output_cost_per_tokens dtype: float64 - name: source dtype: float64 - name: gold_answer dtype: string - name: parsed_answer dtype: string - name: correct dtype: bool splits: - name: train num_bytes: 232526992.0 num_examples: 768 download_size: 57276211 dataset_size: 232526992.0 configs: - config_name: default data_files: - split: train path: data/train-* license: cc-by-nc-sa-4.0 language: - en pretty_name: Model Outputs Kangaroo 2025 5-6 size_categories: - 1K<n<10K --- ### Homepage and repository - **Homepage:** [https://matharena.ai/](https://matharena.ai/) - **Repository:** [https://github.com/eth-sri/matharena](https://github.com/eth-sri/matharena) ### Dataset Summary This dataset contains model answers to the questions from Kangaroo 2025 5-6 generated using the MathArena GitHub repository. ### Data Fields The dataset contains the following fields: - `problem_idx` (`int64`): Problem index within the corresponding MathArena benchmark. - `image` (`image`): Problem image associated with this model response. - `model_name` (`string`): Human-readable model name shown in MathArena results. - `model_config` (`string`): Path to the model configuration used to produce this response. - `idx_answer` (`int64`): Attempt index for this model/problem pair. - `all_messages` (`string`): JSON-serialized full conversation for this attempt. - `user_message` (`string`): User prompt sent to the model for this attempt. - `answer` (`string`): Full model response. - `input_tokens` (`int64`): Number of input tokens billed or counted for this attempt. - `output_tokens` (`int64`): Number of output tokens generated for this attempt. - `cost` (`float64`): Estimated API cost in USD for this attempt. - `input_cost_per_tokens` (`float64`): Input-token price used for cost estimation, in USD per one million tokens. - `output_cost_per_tokens` (`float64`): Output-token price used for cost estimation, in USD per one million tokens. - `source` (`float64`): Source or provenance identifier for the problem. - `history` (`string`): JSON-serialized intermediate solver or agent history, when available. - `gold_answer` (`string`): Gold answer used for automatic scoring. - `parsed_answer` (`string`): Answer extracted from the model response by the MathArena parser. - `correct` (`bool`): Whether the parsed model answer matched the gold answer, stored as a boolean or numeric 0/1 value. ### Source Data The original questions were sourced from the Albanian Kangaroo 2025. Questions were extracted, translated, and screenshotted. ### Licensing Information This dataset is licensed under the Attribution-NonCommercial-ShareAlike 4.0 International (CC BY-NC-SA 4.0). Please abide by the license when using the provided data. ### Citation Information ``` @article{dekoninck2026matharena, title={Beyond Benchmarks: MathArena as an Evaluation Platform for Mathematics with LLMs}, author={Jasper Dekoninck and Nikola Jovanović and Tim Gehrunger and Kári Rögnvaldsson and Ivo Petrov and Chenhao Sun and Martin Vechev}, year={2026}, eprint={2605.00674}, archivePrefix={arXiv}, primaryClass={cs.CL}, url={https://arxiv.org/abs/2605.00674}, } ```
MathArena 2025 5-6 Competition Model Answers Dataset, containing model answers to math problems and related feature information.