openpecha/tibetan-metadata-extracted
收藏资源简介:
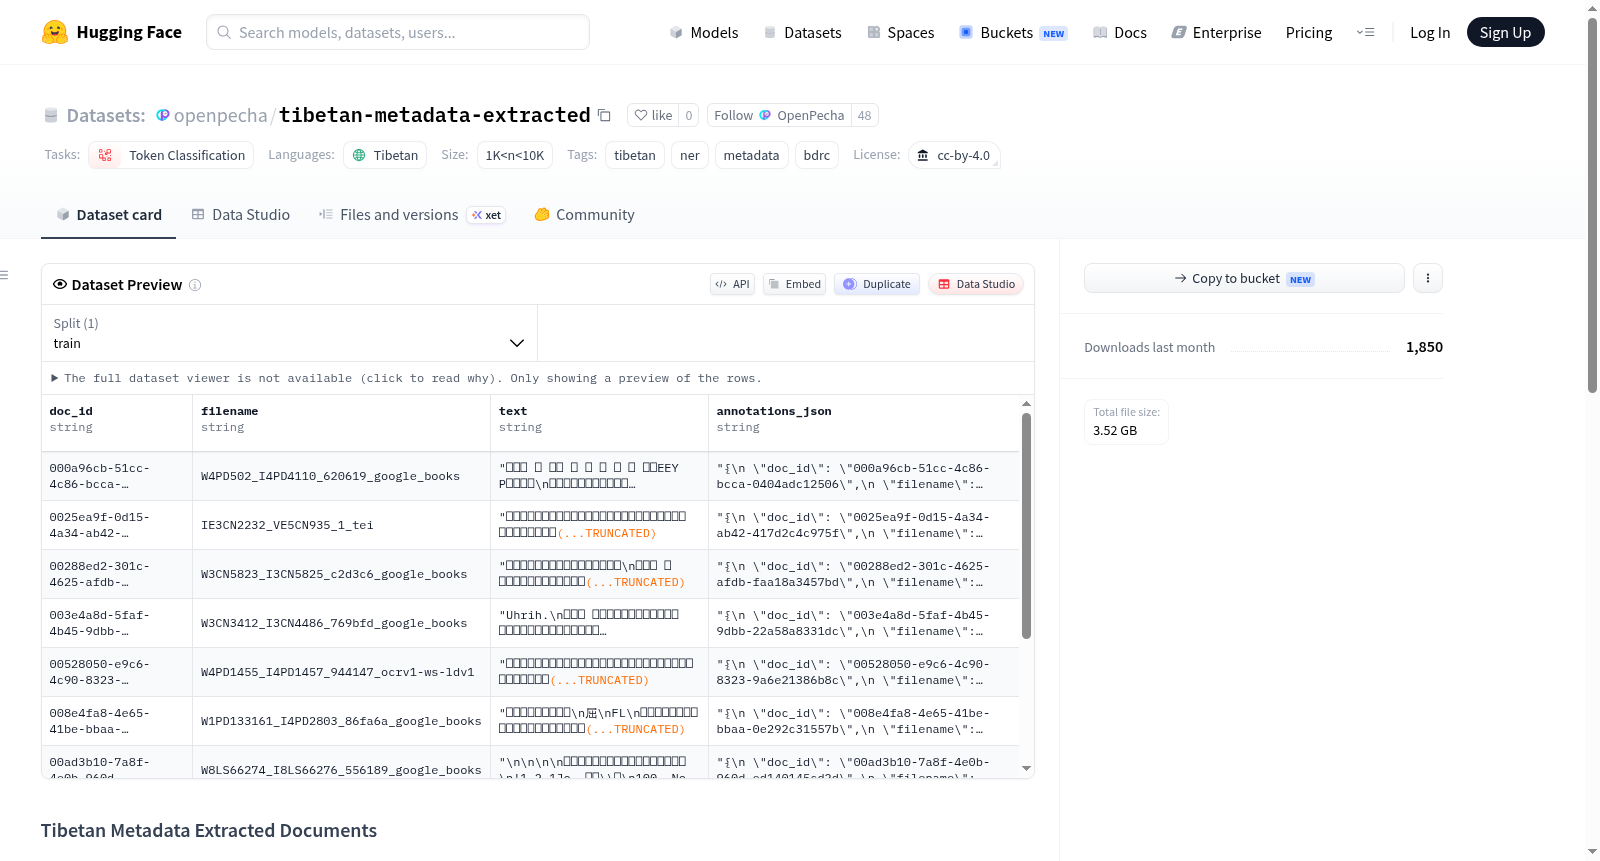
--- license: cc-by-4.0 language: - bo task_categories: - token-classification tags: - tibetan - ner - metadata - bdrc size_categories: - 1K<n<10K --- # Tibetan Metadata Extracted Documents Raw BDRC outliner exports used to build [ganga4364/tibetan-metadata-detector](https://huggingface.co/datasets/ganga4364/tibetan-metadata-detector). ## Contents 3,794 approved documents with annotated title/author spans. Each row: | Field | Description | |-------|-------------| | `doc_id` | Document UUID | | `filename` | Source filename | | `text` | Full document text (UTF-8) | | `annotations_json` | JSON with `segments` and flat `annotations` (title/author spans) | ## Related repos - Window splits + model training data: [ganga4364/tibetan-metadata-detector](https://huggingface.co/datasets/ganga4364/tibetan-metadata-detector) - Fine-tuned model: [ganga4364/tibetan-metadata-roberta-ner](https://huggingface.co/ganga4364/tibetan-metadata-roberta-ner) - Demo: [ganga4364/tibetan-metadata-highlight](https://huggingface.co/spaces/ganga4364/tibetan-metadata-highlight) ## Usage ```python from datasets import load_dataset ds = load_dataset("ganga4364/tibetan-metadata-extracted") doc = ds["train"][0] ```
The dataset is named Tibetan Metadata Extracted Documents and contains 3,794 approved documents with annotated title and author spans. It is derived from raw BDRC (Buddhist Digital Resource Center) outliner exports and used to build a Tibetan metadata detection model. Each document includes the following fields: doc_id (document UUID), filename (source filename), text (full document text in UTF-8), and annotations_json (JSON with title and author span annotations). The dataset is in Tibetan language, falls under the token-classification task category, and is suitable for named entity recognition (NER) and metadata processing, with a size between 1,000 and 10,000 samples.