tianyang/repobench-r
收藏资源简介:
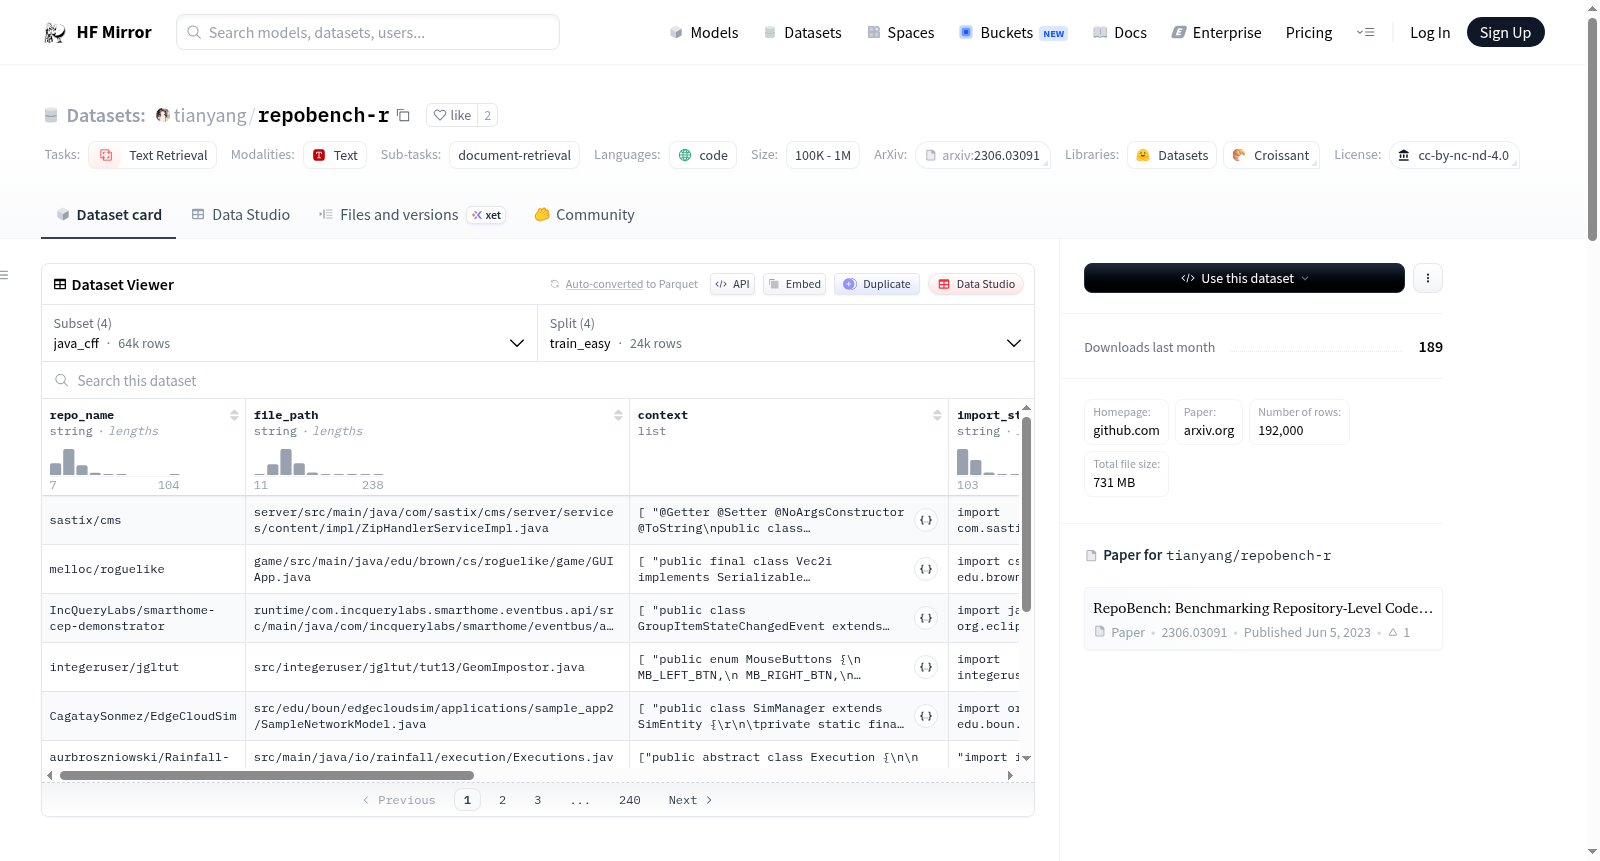
RepoBench-R(检索)是RepoBench的一个子任务,专注于从项目仓库中检索最相关的代码片段以进行下一行代码预测。数据集包含四种设置:python_cff、python_cfr、java_cff和java_cfr,每种设置又分为train_easy、train_hard、test_easy和test_hard四个分割。数据集的每个数据点包含仓库名称、文件路径、上下文代码片段、导入语句、黄金代码片段索引、代码和下一行代码。
RepoBench-R (Retrieval) is a subtask of RepoBench, focusing on retrieving the most relevant code snippets from project repositories for next-line code prediction. The dataset includes four settings: python_cff, python_cfr, java_cff, and java_cfr. Each setting is further divided into four splits: train_easy, train_hard, test_easy, and test_hard. Each data point in the dataset contains repository name, file path, contextual code snippet, import statements, ground-truth code snippet index, code, and next-line code.
数据集概述
数据集名称
RepoBench-R (Retrieval)
数据集描述
RepoBench-R 是 RepoBench 的一个子任务,专注于从项目仓库中检索最相关的代码片段,用于下一行代码预测。
数据集结构
数据集包含以下字段:
repo_name: 数据点的仓库名称file_path: 文件路径context: 上下文代码片段列表import_statement: 文件中的所有导入声明gold_snippet_index: 黄金代码片段在上下文列表中的索引code: 下一行预测的代码next_line: 代码的下一行
数据集子集
数据集包含以下子集:
python_cff: Python 数据集,cff设置python_cfr: Python 数据集,cfr设置java_cff: Java 数据集,cff设置java_cfr: Java 数据集,cfr设置
每个子集包含以下分割:
train_easy: 训练集,简单难度train_hard: 训练集,困难难度test_easy: 测试集,简单难度test_hard: 测试集,困难难度
加载数据示例
python from datasets import load_dataset
dataset = load_dataset("tianyang/repobench-r", "python_cff", split="test_easy")
许可证信息
CC BY-NC-ND 4.0
引用信息
bibtex @misc{liu2023repobench, title={RepoBench: Benchmarking Repository-Level Code Auto-Completion Systems}, author={Tianyang Liu and Canwen Xu and Julian McAuley}, year={2023}, eprint={2306.03091}, archivePrefix={arXiv}, primaryClass={cs.CL} }